Reading the CUDA Programming Guide for LLM inference speed
- Source
- x.com
- Date

we launched the most comprehensive ai performance engineering repo in the world and we're posting every single resource follow and save to keep up with the series. links in thread 🧵 part 10: CUDA Programming Guide making an LLM faster means understanding where execution is waiting. an attention kernel can wait for its next tile of data, while the serving runtime can leave the GPU waiting for the next launch. NVIDIA's CUDA Programming Guide explains the mechanisms behind those waits. for a modern AI performance engineer working in PyTorch, Triton, or CUDA, it helps with: - tuning attention, matmul, and normalization kernels. the SIMT and CUDA Tile chapters connect layouts and data reuse to GPU execution. the resource guidance explains why larger tiles or more fusion can introduce register spills. - overlapping data movement with computation. asynchronous copies, TMA, and producer/consumer pipelines explain how supported GPUs can load the next tile while processing the current one, with the synchronization required to reuse buffers safely. - managing growing KV caches. the virtual memory chapter explicitly connects its allocation model to LLM serving: reserve an address…

Context
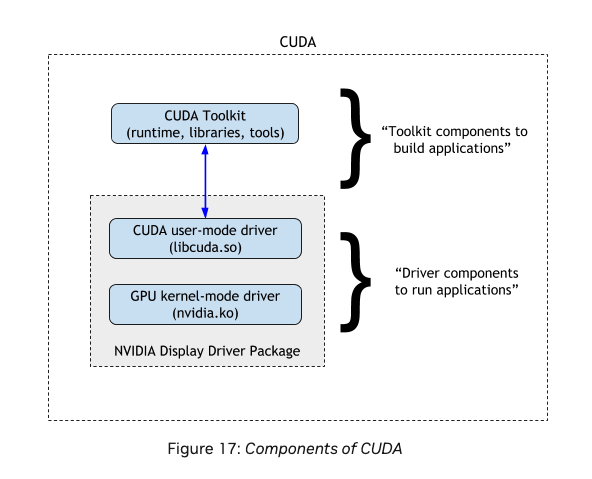
wafer_ai, in part 10 of an X series on AI performance engineering, argues that speeding up a means finding where execution is waiting, and that NVIDIA's CUDA Programming Guide explains those waits. CUDA is NVIDIA's programming platform for GPUs. The guide's contents page does list sections on CUDA Graphs, a stream-ordered memory allocator, memory synchronization domains and virtual memory management, the topics the post draws on.
One example is the , the stored data a model keeps for earlier text, which grows as a conversation does. The post says the guide's virtual memory chapter ties its allocation model to LLM serving: reserve an address range, then map more physical memory into it as the cache grows, without moving existing data. Another is CUDA Graphs, which the post says cut repeated CPU launch setup between kernels. These are the post's descriptions of the guide's chapters, which were not checked against the chapter text, and no speedup is measured.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
Checking sign-in…
Loading comments…