vLLM Runs DeepSeek v4.1 Flash Day-0 on NVIDIA, Stalls on AMD
- Source
- x.com
- Date
SemiAnalysis reports that on DeepSeek V4.1 Flash's release day, NVIDIA's vLLM stack ran the model cleanly across hardware from H100 through the newer GB300, while AMD's announced ROCm image for the same model had still not shipped a full day after release. Day-zero framework support is what decides whether a new open model can actually be deployed in production the day it launches, rather than sitting unusable while teams wait for a serving stack to catch up. This gap follows the same pattern seen with earlier open model releases, where NVIDIA's software ecosystem consistently reaches parity with a new release faster than AMD's does. For teams evaluating AMD hardware as a cost alternative for serving open models, this is a concrete, dated data point on how far that software gap still runs, not a one-off complaint.

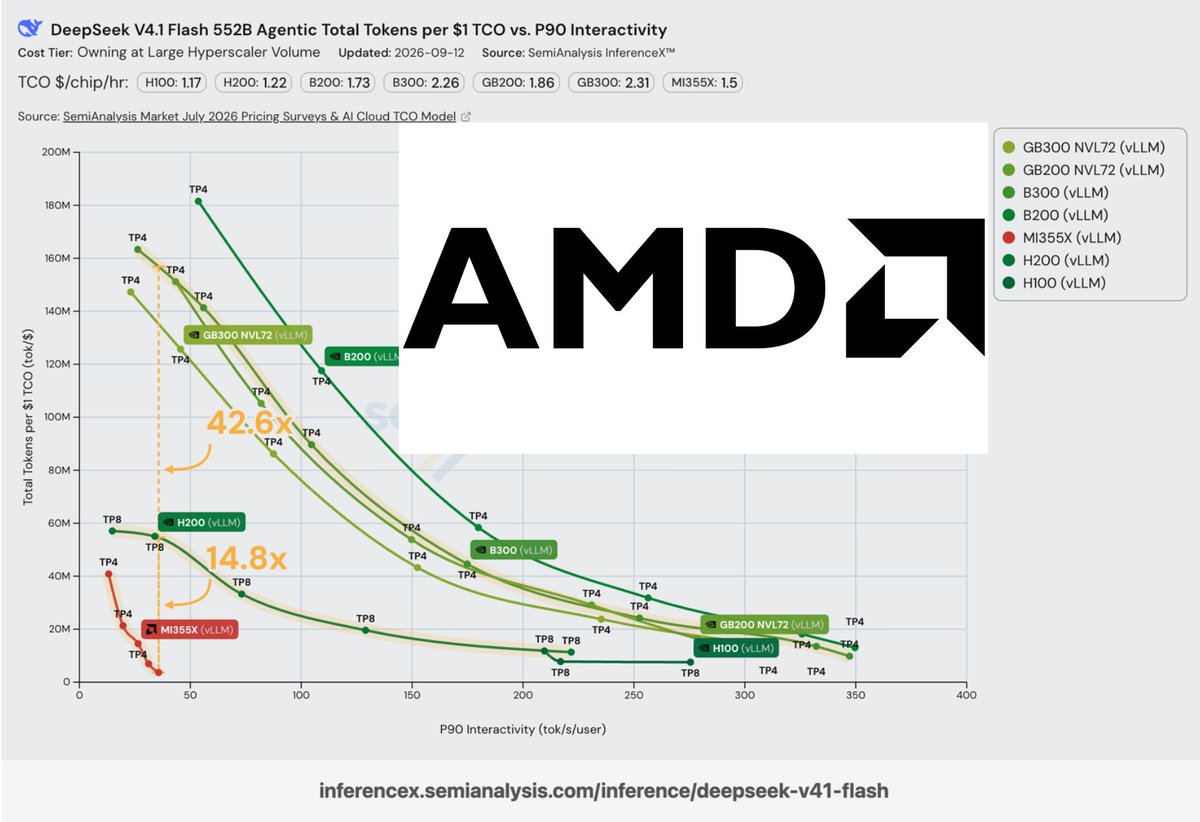
On the Day 0 release of DeepSeekv4.1 Flash, NVIDIA vLLM works out of the box with zero issues across all 6 SKUs: H100, H200, B200, B300, GB200, GB300! Amazing work by the NVIDIA & Inferact teams! In comparison, AMD vLLM still does not work on DeepSeekv4.1 Flash, as we will describe below👇️(1/2)🧵

Context
vLLM is a widely used open-source system for serving large language models efficiently. On the day DeepSeek released its v4.1 Flash model, SemiAnalysis reports that NVIDIA's vLLM support worked with zero issues across all six of its current GPU types: H100, H200, B200, B300, GB200 and GB300.
By contrast, SemiAnalysis reports AMD's vLLM support for the same model was still not working as of that post. Two days later, AMD did release its own image for the model, but SemiAnalysis found it cost far more per dollar to run than NVIDIA's hardware once it arrived.

Checking sign-in…
Loading comments…