Language Models for Text Classification: From Bag-of-Words to Jev
Source
magazine.sebastianraschka.com
Author
Sebastian Raschka, PhD
Date
Context
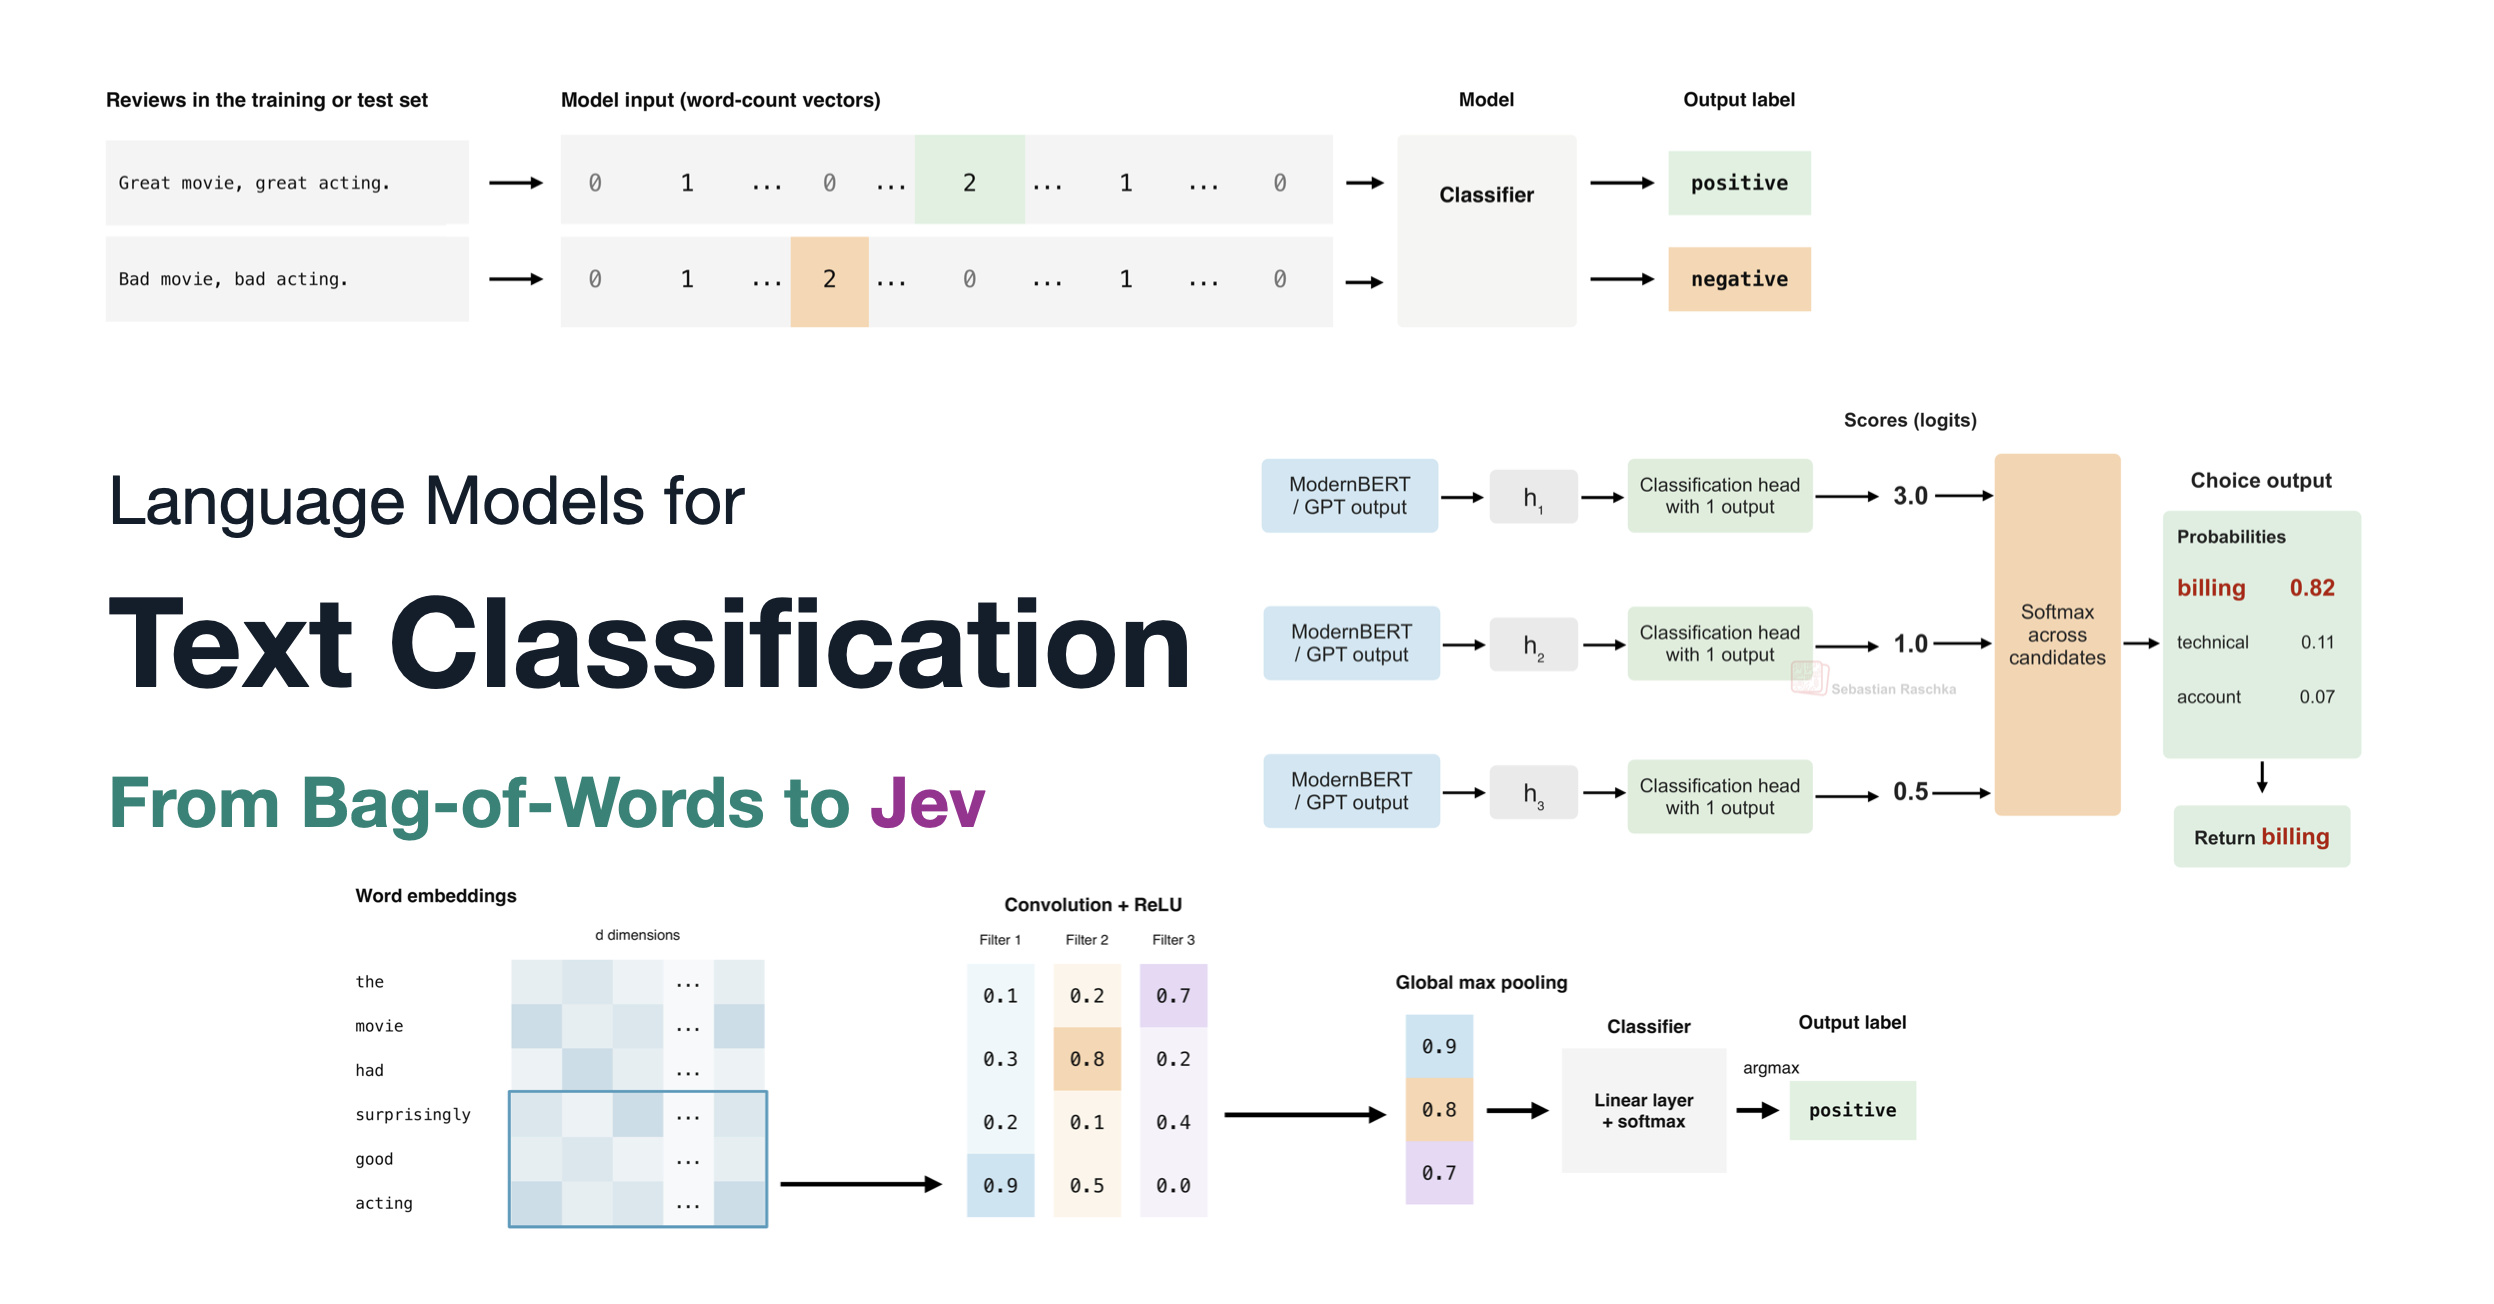
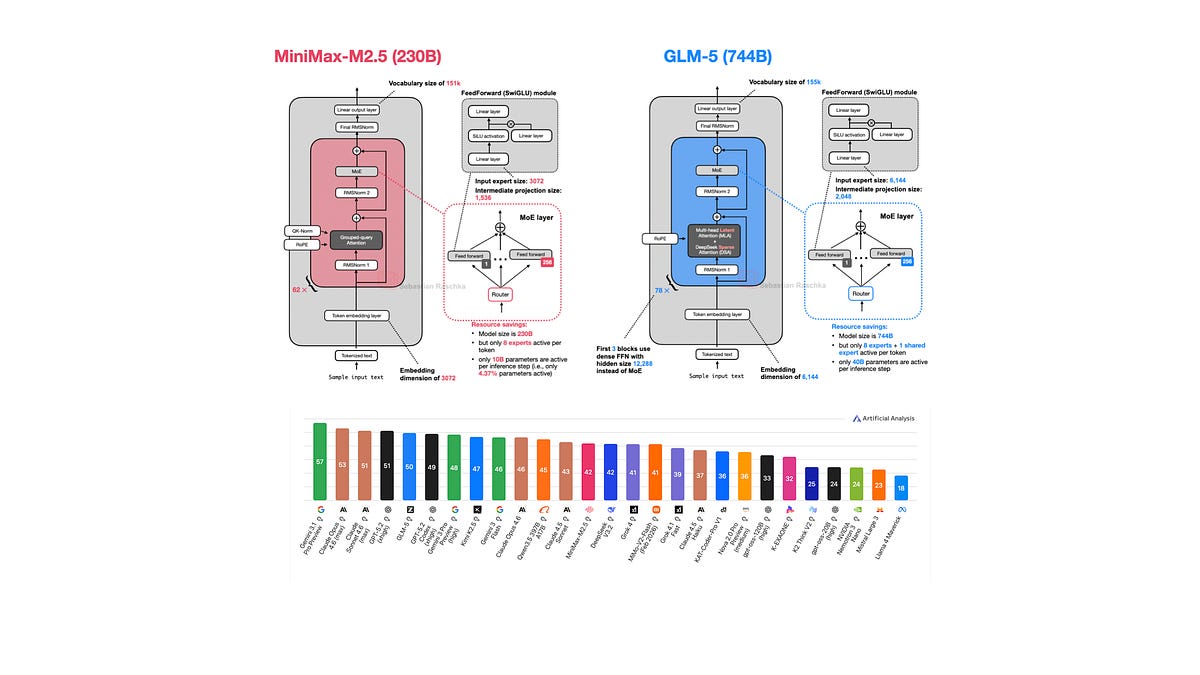
Jev lets users describe a text-classification task and its possible answers without training a separate model for that task. In Sebastian Raschka'shands-on evaluation, TypeSafe AI's model received movie reviews with descriptions of positive and negative sentiment. Its Choice interface achieved 96.47% accuracy on 25,000 test reviews at a reported API cost of about $0.65. That is a concrete example of ready-made classification, although Raschka could not establish whether those reviews had appeared in training. His proposed explanations of Jev's architecture remain educated guesses.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.