Eric Jang – Building AlphaGo from scratch
- Source
- dwarkesh.com
- Author
- Dwarkesh Patel
- Date
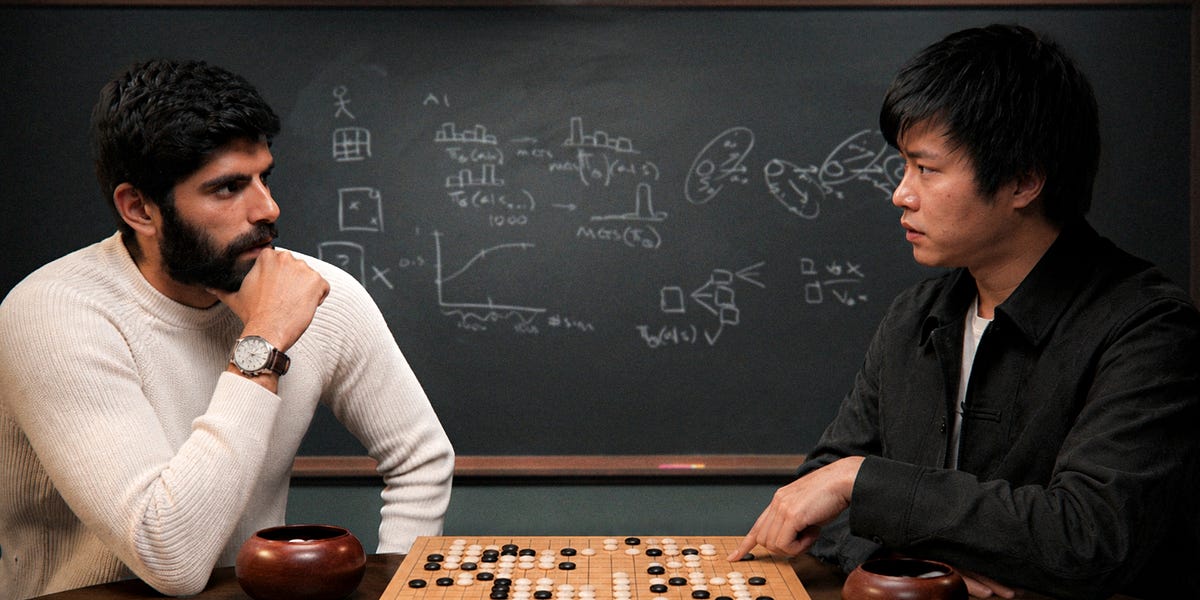
Explains why AlphaGo's MCTS gives a per-move training target that avoids the credit-assignment problem naive policy-gradient RL faces across 100k- trajectories, plus a candid breakdown of which AI research tasks LLMs can already automate and which they can't. Useful mental models for anyone building or reasoning about RL and agentic research loops.
“Thanks to LLM coding, what took a whole team of research scientists at DeepMind and millions of dollars of research and compute can now be done for a few thousand dollars of rented compute.”
Eric Jang
“In deep learning, initialization is everything. You always want to initialize your research project to something as close to success as possible”
Eric Jang
“This was a breakthrough that I think most people don’t even fully comprehend today, how profound that accomplishment is.”
Eric Jang
“Because Go is such a combinatorially complex game, you cannot afford to build the tree in advance and then search it. You must search while building the tree.”
Eric Jang
“The compute required to be the first to do something is always much larger than the compute it takes to catch up.”
Eric Jang
- 00:00:00Basics of Go
- 00:08:17Monte Carlo Tree Search
- 00:32:04What the neural network does
- 01:00:33Self-play
- 01:25:38Alternative RL approaches
- 01:45:47Why doesn't MCTS work for LLMs
- 02:01:09Off-policy training
- 02:12:02RL is even more information inefficient than you thought
- 02:22:16Automated AI researchers
 videoWhat rebuilding AlphaGo teaches us about self-play, RL, and future of LLMs - Eric JangDwarkesh Patel
 videoDavid Silver and Lasse Espeholt of Ineffable Intelligence: A Superlearner for the Age of ExperienceSequoia Capital
 podcastAI researchers debate how close we are to recursive self-improvementDwarkesh Patel
Checking sign-in…
Loading comments…