tau2-bench v1.0.1 — τ-bench 1.0.1 — banking_knowledge Grading Fixes
- Source
- github.com
- Author
- benshi34
- Date
Context
A higher banking score in tau2-bench 1.0.1 can reflect corrected grading without any change in an 's behavior. Previously, an extra verification read, such as checking accounts after opening one, changed a logged database state and could make an otherwise correct run fail. The release stops those extra reads from invalidating the comparison while preserving required-read checks. Regrading recorded runs raised single-attempt scores by up to 9.02 percentage points. A separate correction to a task's expected refund can change results in either direction. Banking scores therefore need matching grading versions for comparison; the release says other domains are unaffected. Release notes.
- The bug that ate the scores: every tool read was logged to a database table included in the reward's hash comparison, so one prudent extra check, like listing a customer's accounts right after opening one, turned a correct run into a zero.
- Fixing it moved leaderboard scores only upward, by as much as 9 points pass^1 (gpt-5-5 went 37.4 to 46.4), with no run flipping pass to fail. The grader had been taxing caution rather than measuring it.
- `25` and `25.0` are the same JSON number but produced different deterministic record IDs and therefore different database states, so argument spelling alone could fail a task. Numeric tool arguments are now normalized before hashing.
- One fixture leaked its own answer key: fee descriptions carried annotations like '(SHOULD BE FREE - 1ST OF 2)', so an agent never had to derive the free-withdrawal allowance from the policy docs. Scrubbing them changes what the task measures.
- A transactions tool returned raw insertion order while the knowledge base documented most-recent-first, which made the 'dispute the earliest duplicate charge' tasks unresolvable from tool output alone. Docs and tool behavior have to agree or the task is unfair.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
“Under the grading-scheme fixes, re-grading the leaderboard trajectory sets moves scores **only upward** — no previously-passing simulation fails — by up to ~9 points pass^1 depending on the model.”
“One prudent verification read not present in the golden trajectory — e.g. listing a user's accounts right after opening one — failed the task, even though the knowledge base encourages such reads.”
“This made the "dispute the earliest duplicate" tie-breaker unresolvable from tool output on the duplicate-charge tasks (083–085).”
“This is a gold-value change: trajectories that reproduced the old $8.00 refund fail task_074 under 1.0.1, while policy-faithful $14.50 refunds now pass.”
 repotau2-bench v2.0.0 — τ-bench 2.0.0 — Multilingual and Voicesoham-sierra
 articleTauIndianBankBench: Procedure-Aware, Action-Oriented Evaluation of Tool-Using Conversational AgentsKrishanu Adhikary, Prashant Devadiga
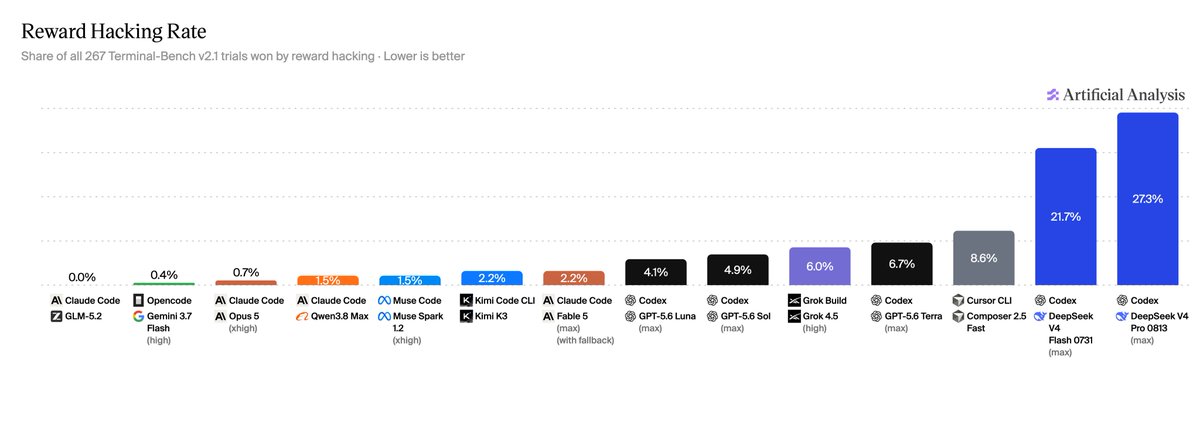 postArtificial Analysis zeroes reward-hacked Terminal-Bench runs in its coding indexArtificial Analysis
Checking sign-in…
Loading comments…