Patterns for Building LLM-based Systems & Products
- Source
- eugeneyan.com
- Author
- Eugene Yan
- Date
Context
Reusing a saved AI answer can avoid another model call, but similar questions do not always deserve the same answer. In a 2023 systems guide, Eugene Yan illustrates the problem with requests about different sequels: their wording may be close enough for a similarity search to return a summary of the wrong film.
The proposed alternative is to identify what makes an answer reusable, such as the exact item or pair of items being discussed, and use those identifiers when storing and retrieving it. Caching then depends on task identity as well as repetition. Its usefulness also depends on whether enough requests recur to justify maintaining the saved answers.
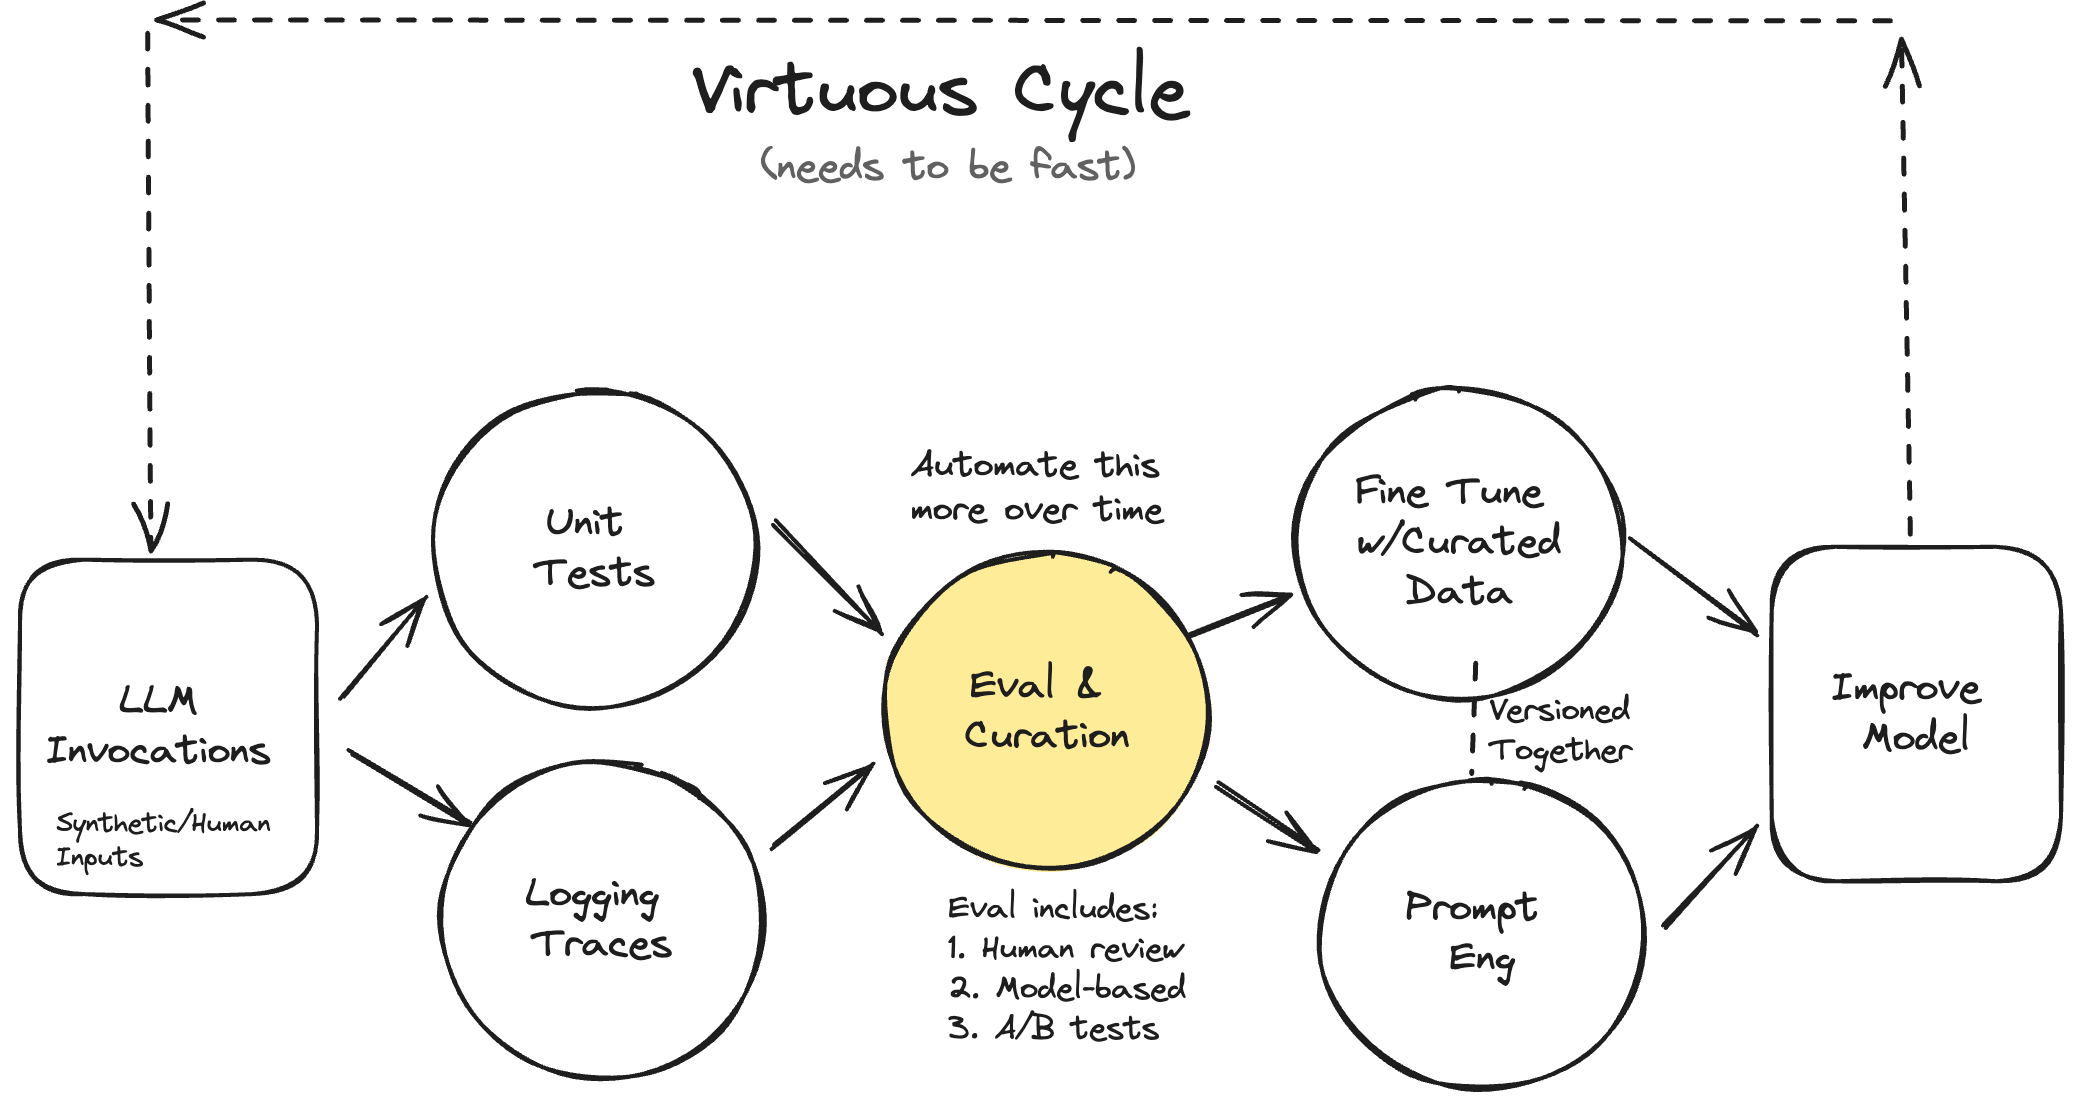
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- RAG — Retrieval-augmented generation — fetching relevant documents first and pasting them into the model's context so it answers from your data instead of memory.
- fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
- guardrails — The checks around a model that block bad inputs and outputs — filters, validators, and permission rules the model itself can't override.
“There is a large class of problems that are easy to imagine and build demos for, but extremely hard to make products out of. For example, self-driving: It’s easy to demo a car self-driving around a block, but making it into a product takes a decade.”
Karpathy
“How important evals are to the team is a major differentiator between folks rushing out hot garbage and those seriously building products in the space.”
“The vibe-based eval cannot be underrated. … One of our evals was just having a bunch of prompts and watching the answers as the models trained and see if they change. Honestly, I don’t really believe that any of these eval metrics capture what we care about.”
Jonathan Frankle
“do not work with/report or trust MMLU scores”
Checking sign-in…
Loading comments…