LLM Evals: Everything You Need to Know
- Source
- hamel.dev
- Author
- Hamel Husain
- Date
Context
An can choose a sensible tool and still fail the user's task. In the evaluation FAQ, Hamel Husain recommends first checking the completed outcome, including any required change outside the conversation. For a scheduling task, that means checking whether the appointment was actually arranged.
Once failed tasks are identified, the execution record can reveal where they broke: the inputs extracted, tools selected, returned results and handling of errors. Grouping failures by the last successful stage and the first failing stage helps concentrate debugging effort. This connects component checks to the outcome they are supposed to produce.
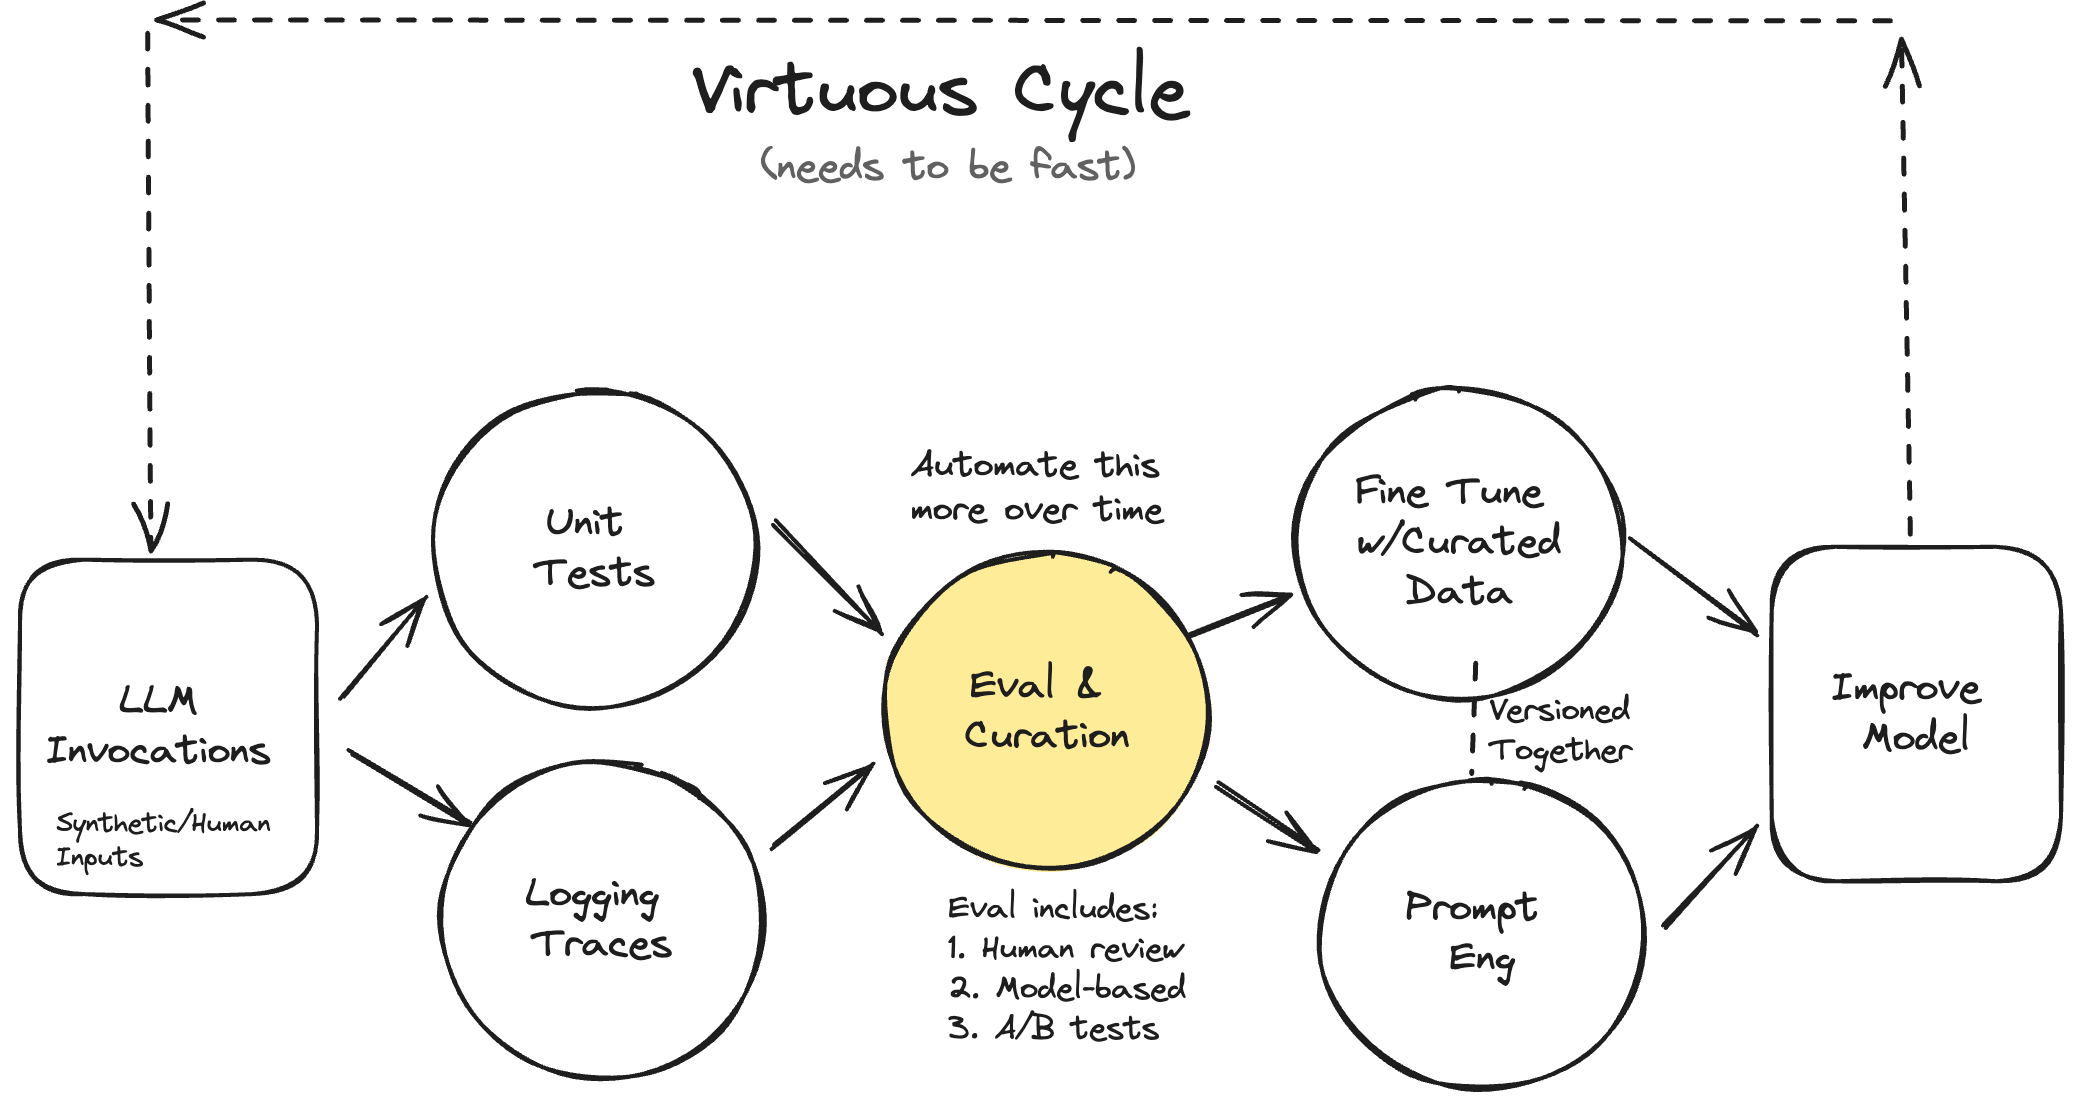
- The time split is uncomfortable: on real projects, 60-80% of development time went to error analysis and . Evals are part of building, like debugging, not a separate budget line.
- A 100% eval pass rate is a bad sign. It means the tests are not stressing the system; something nearer 70% suggests the evals are actually catching real failures.
- Error analysis borrows its shape from qualitative research: open coding (free-form notes on traces, tagging the first failure you see), then axial coding (grouping those notes into a failure taxonomy and counting each bucket). The counts decide which evals to build.
- Stop reviewing traces at theoretical saturation — the point where new traces stop revealing new failure modes. Rule of thumb: review at least 100, and if roughly 20 in a row add no new category, you are done.
- Do not pitch 'evals' to your team, pitch findings. Read 50-100 real conversations, present the top failure modes with how often each happens, and keep a running log of issues caught before users saw them.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
“In the projects we’ve worked on, we’ve spent 60-80% of our development time on error analysis and evaluation .”
Hamel Husain
“If you’re passing 100% of your evals, you’re likely not challenging your system enough. A 70% pass rate might indicate a more meaningful evaluation that’s actually stress-testing your application.”
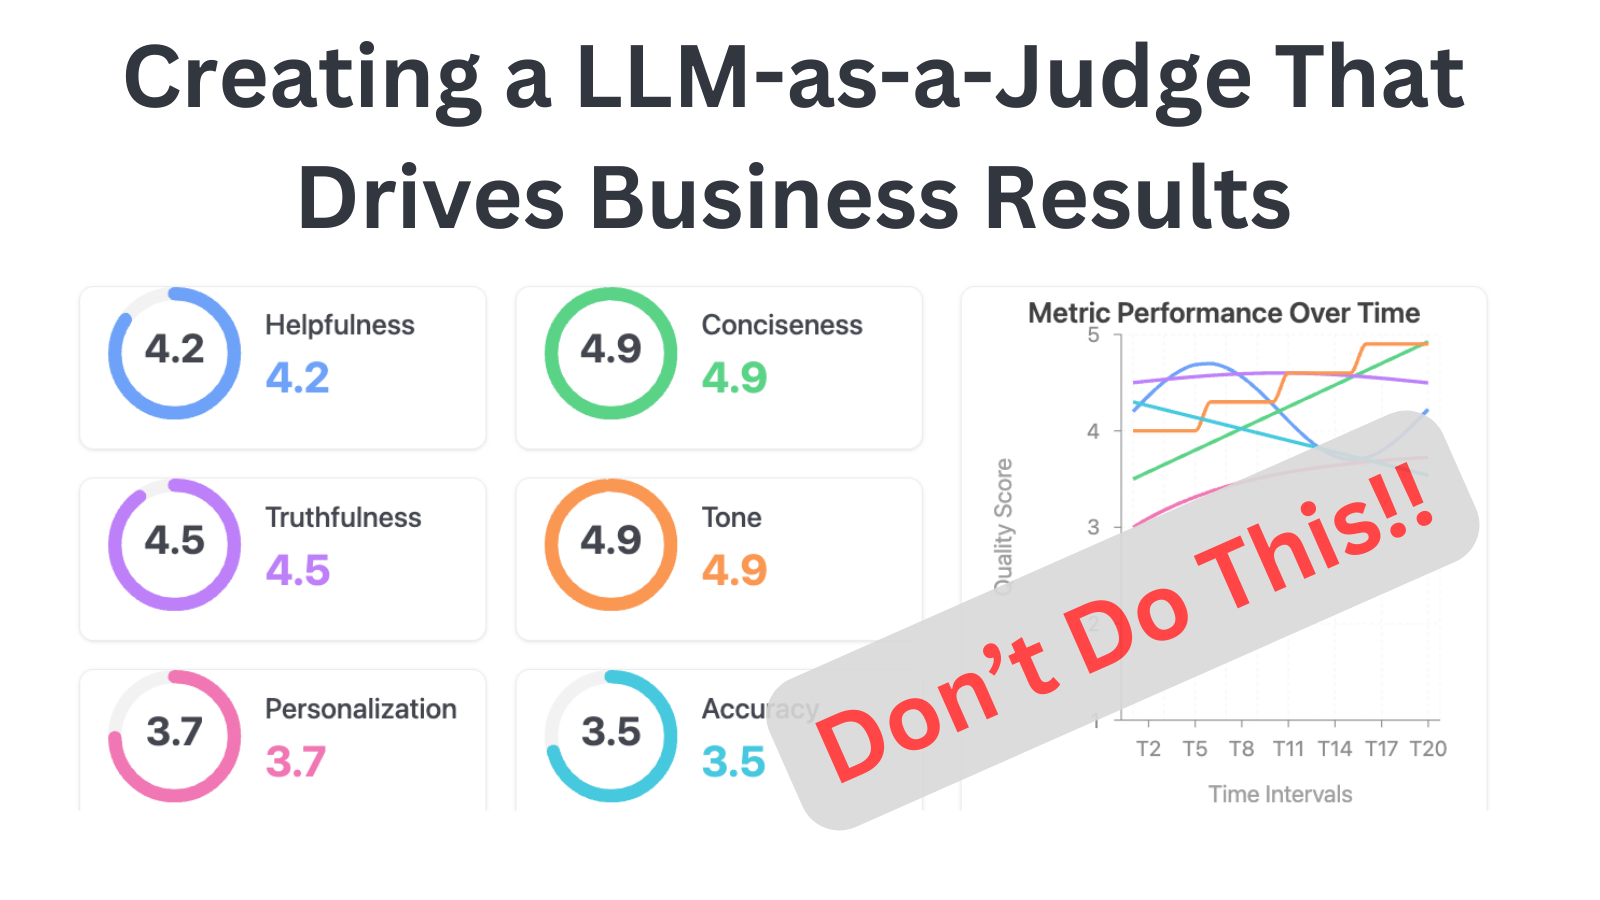
“All you get from using these prefab evals is you don’t know what they actually do and in the best case they waste your time and in the worst case they create an illusion of confidence that is unjustified.”
“Use LLMs to scale what you’ve learned, not to avoid looking at data.”
Checking sign-in…
Loading comments…