Evaluating the Effectiveness of LLM-Evaluators (aka LLM-as-Judge)
- Source
- eugeneyan.com
- Author
- Eugene Yan
- Date
Context
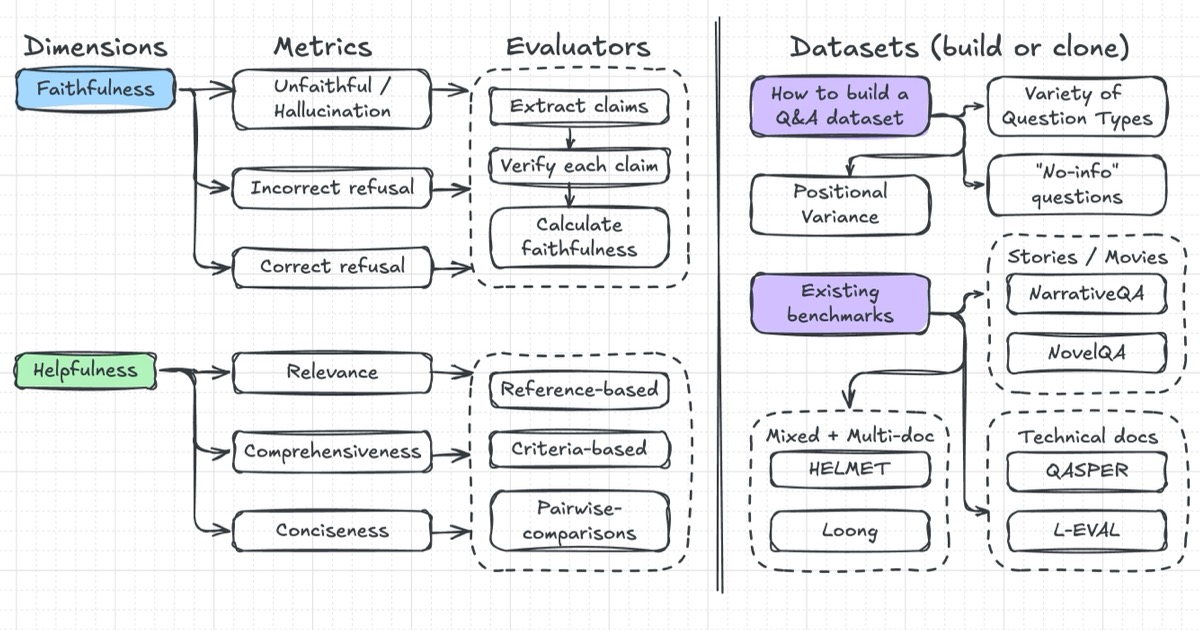
An AI evaluator that chooses the better of two answers has not established that either answer is acceptable. Eugene Yan's review of language-model evaluators distinguishes relative preference from checking an individual answer against a requirement. A tone comparison may suit the first approach; checking whether a summary contradicts its source needs an explicit criterion.
That choice also determines how to assess the evaluator. For defect detection, compare its decisions with human-labeled examples and inspect both missed defects and false alarms. A single agreement score can obscure which mistake the evaluator makes, leaving a product team without the information needed to decide whether to trust its judgments.
- alignment — The work of making AI systems actually pursue what their builders and users intend, rather than something subtly or dangerously different.
- fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
“Most folks have human annotators as the baseline. Here, we aim for the LLM-human correlation to match human-human correlation. Compared to human annotators, LLM-evaluators can be orders of magnitude faster and cheaper, as well as more reliable.”
Eugene Yan
“Pairwise comparison chooses the better of two responses or declares a tie. It’s typically used—and more reliable—for subjective evals such as persuasiveness, tone, coherence, etc. Studies show that pairwise comparisons lead to more stable results and smaller differences between LLM judgments and human annotations relative to direct scoring.”
Eugene Yan
“I tend to be skeptical of correlation metrics. They don’t account for chance agreement and thus could be overoptimistic (though Cohen’s $\kappa$ is an exception).”
Eugene Yan
“Across both tasks, the results showed that as the LLM-evaluator increased in parameter count, it becomes more accurate at identifying harmful behavior as well as classifying it.”
Eugene Yan
“The findings showed that applying Chain-of-Thought (CoT) improves the accuracy of LLM-evaluators. Furthermore, the trends suggest that LLM-evaluators larger than 52B can be competitive with preference models finetuned on human feedback.”
Eugene Yan
Checking sign-in…
Loading comments…