Evaluating Long-Context Question & Answer Systems
- Source
- eugeneyan.com
- Author
- Eugene Yan
- Date
Context
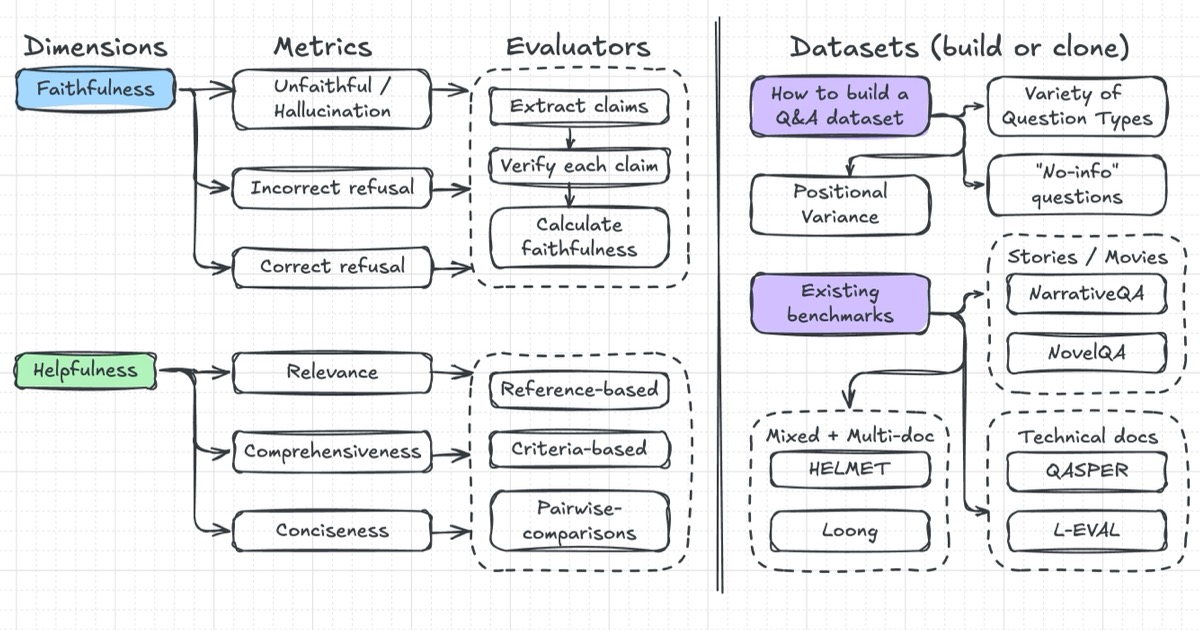
A document-answering system can give a generally correct answer and still fail its user by ignoring what their document actually says. Eugene Yan separates this source faithfulness from usefulness in his guide to evaluating long-context question answering. must check both whether the document supports the claims and whether the response directly answers the question.
Citations alone cannot establish either quality. The cited passage must support the answer, and pointing to a relevant clause may still leave its consequences unexplained. Tests also need questions the document cannot answer, alongside answerable ones, so they catch both invented answers and unnecessary refusals.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
“Positional variance: Evidence may appear at the beginning, middle, or end of documents, making it a challenge for models with limited effective context or those susceptible to the “lost in the middle” problem.”
Eugene Yan
“We also want to distinguish faithfulness from correctness. An answer might be correct based on general knowledge but still be unfaithful if it contradicts the document.”
Eugene Yan
“A study by Xu et al. (2023) found that domain experts in fields like biology or economics preferred answers that were both comprehensive and faithful, particularly for long-form questions. In contrast, crowd-workers often emphasized surface aspects such as conciseness or detail.”
Eugene Yan
“NarrativeQA intentionally generates questions based on summaries rather than full texts. This encourages questions that test narrative comprehension rather than shallow fact recall. For the same reason, QASPER creates questions based on abstracts from academic papers that models then answer based on the full paper.”
Eugene Yan
“People find comparing two answers easier than assigning absolute ratings, resulting in greater consistency across annotators.”
Eugene Yan
Checking sign-in…
Loading comments…