Google's week: EmbeddingGemma 2, Nano Banana 2.1, Gemini business agent
- Source
- x.com
- Date

It’s Friday 🎉 Here’s a look at this week’s announcements: — https://t.co/aIbQoguyFu is now available globally in English, allowing anyone to use our detector portal to easily verify if images, video, or audio files were AI-generated by Google or industry partners — Nano Banana 2.1, featuring leaps in visual design, subject consistency, and precise spot editing that lets you change specific details without altering the whole image — EmbeddingGemma 2, our first natively multimodal open model that unifies text, images, video, audio, and code into a single space for on-device embeddings — @GoogleGemma 4 paired with BOTANIC-1, a specialized AI trained on plant DNA, to rapidly pinpoint the exact mutations that make crops thrive — Gemini agent for your business, a universal cloud agent running 24/7 to get your work done — Guided Vision in Gemini Live, offering real-time visual assistance and dynamic audio descriptions via your camera, built alongside the blind and low-vision community
Context
Among the items in a weekly roundup from the GoogleAI account, EmbeddingGemma 2 is the one that shows what a shared space is for. An embedding model turns content into a list of numbers so that similar items sit close together and can be found by comparing numbers. According to the post, Google's EmbeddingGemma 2 is its first natively open model, placing text, images, video, audio and code in a single space for embeddings that run on a device.
The practical meaning of one space is that a text query and a photo or an audio clip can be compared directly, so a search over personal files would not need a separate model for each file type. That is an from how embeddings work, not a result the post demonstrates, and the post gives no benchmarks or size figures. Intel has a separate item on the model's release.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
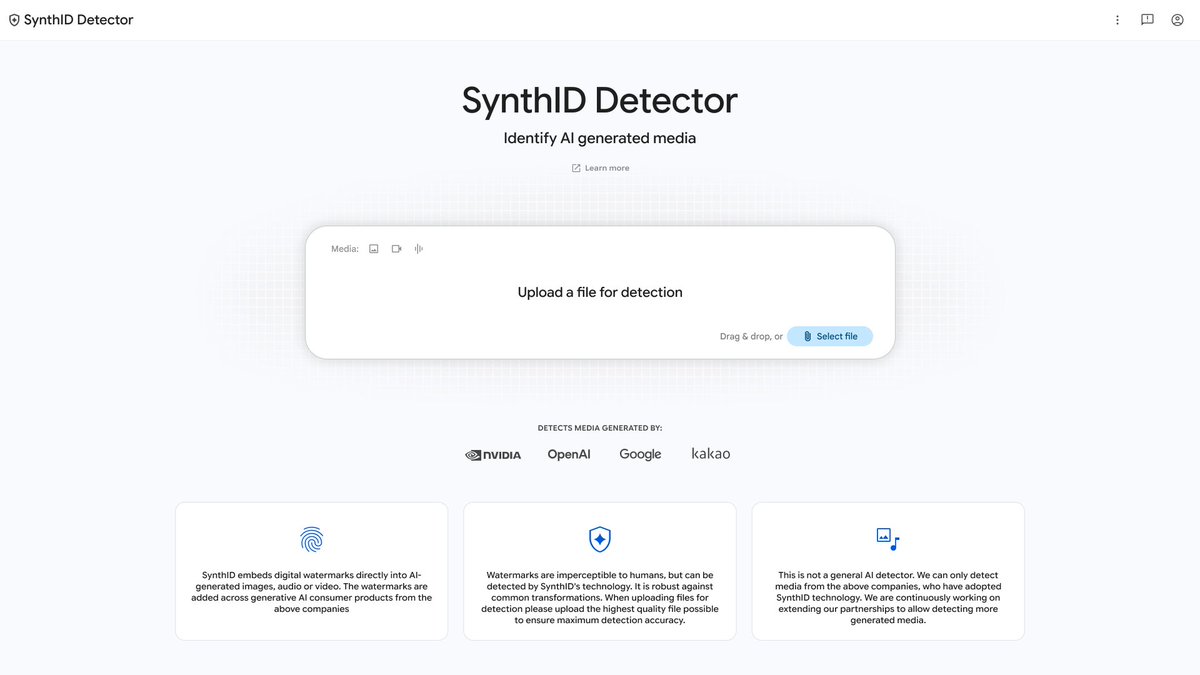 postGoogle opens SynthID watermark checks to everyone, with partner coverage
 postGemma 4 orchestrates a plant DNA model to find crop mutations in minutes
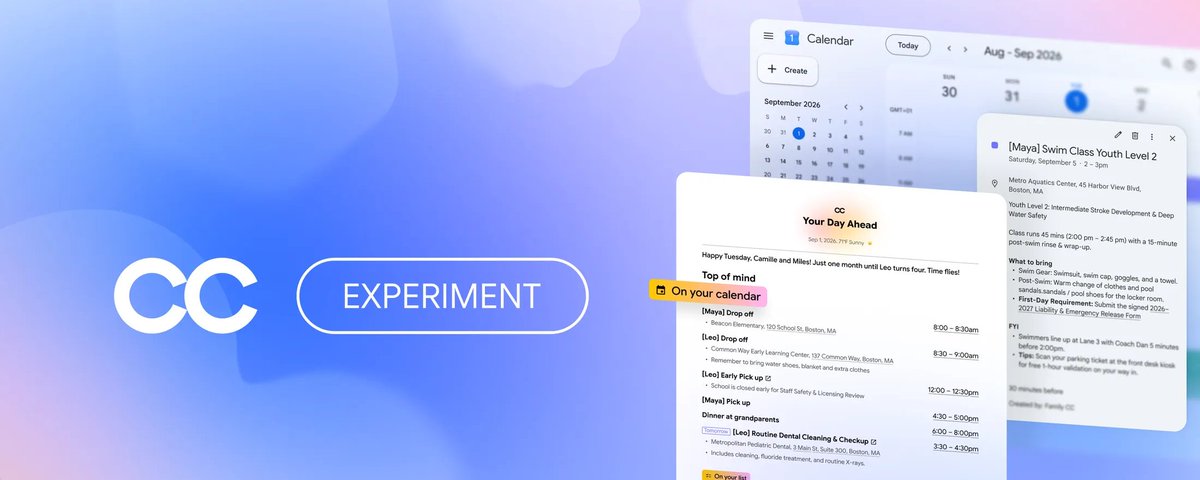 articleGoogle's Project CC gives a family agent its own identity and sandbox
- postGoogle AI's Weekly Recap Includes New TTS Models and a Space Compute Prototype
Checking sign-in…
Loading comments…