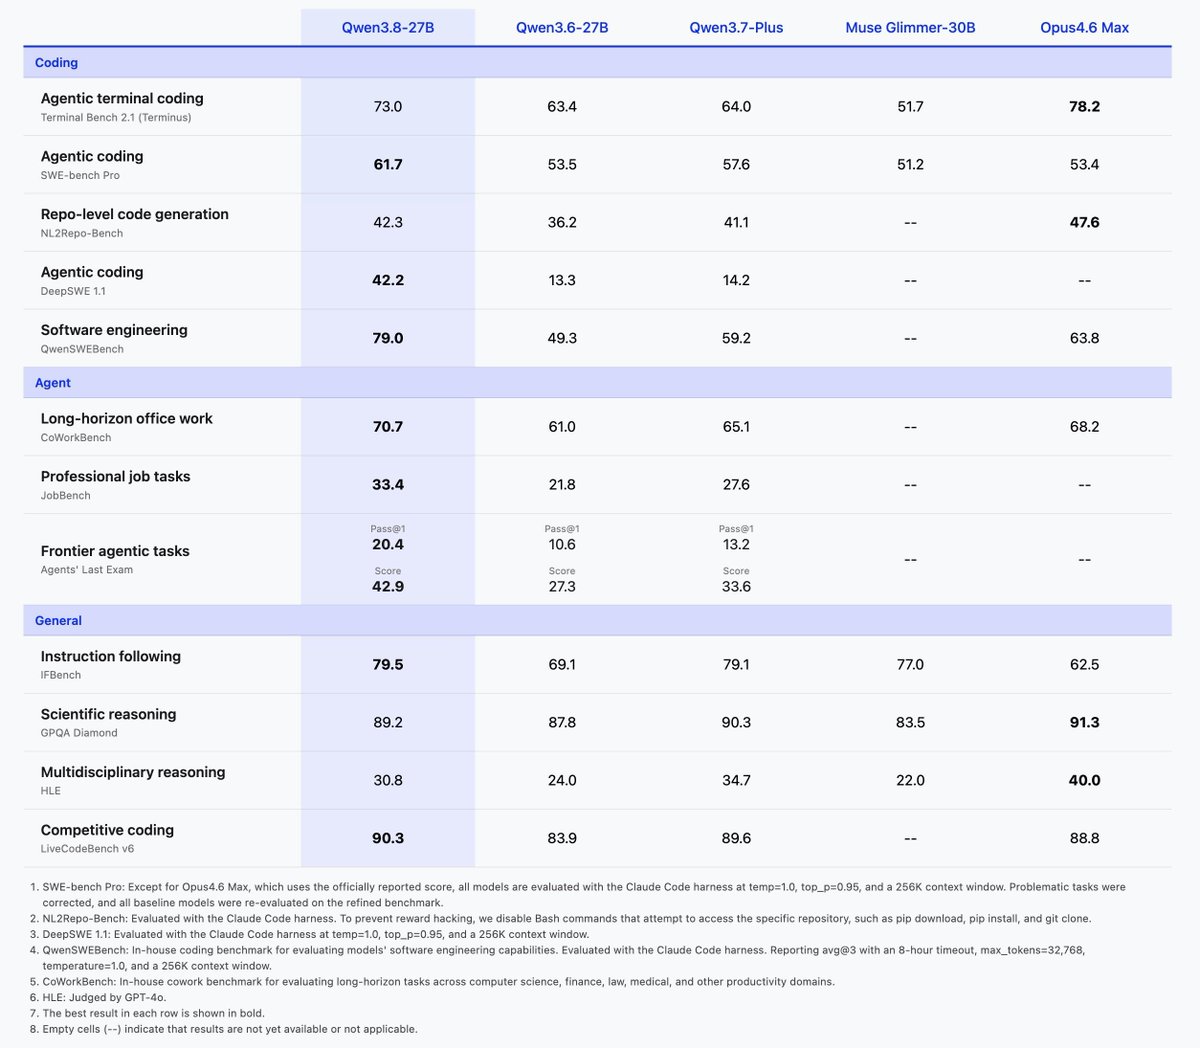
Qwen 3.8 27B weights are coming out next week. It's a big deal.
- Source
- x.com
- Date

Qwen 3.8 27B weights are coming out next week. It's a big deal. We are going to have close to GLM-5.2 level intelligence running locally on a 36GB MacBook ($4k) at ~25 tok/sec. Watch this so you know what's coming. Great convo w/ @jason @Lons @eisokant @Ape https://t.co/32R5Nqsn1C
Context
The downloadable release anticipated by this August 7 post subsequently happened: Qwen records Qwen3.8-27B's release on August 14 in its official repository. The model card provides weights and configuration for developers to operate the model on their own systems.
That confirms access to the model, while the post's claim of roughly 25 generated text per second on a 36GB MacBook remains a forecast. The original post supplies no measured laptop run or configuration. Downloadable weights make self-hosting possible; they do not by themselves establish that particular computer's speed or the claimed quality comparison.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference

Checking sign-in…
Loading comments…