Long Live the Short King: Why 4-hi HBM Wins
- Source
- newsletter.semianalysis.com
- Author
- Myron Xie
- Date
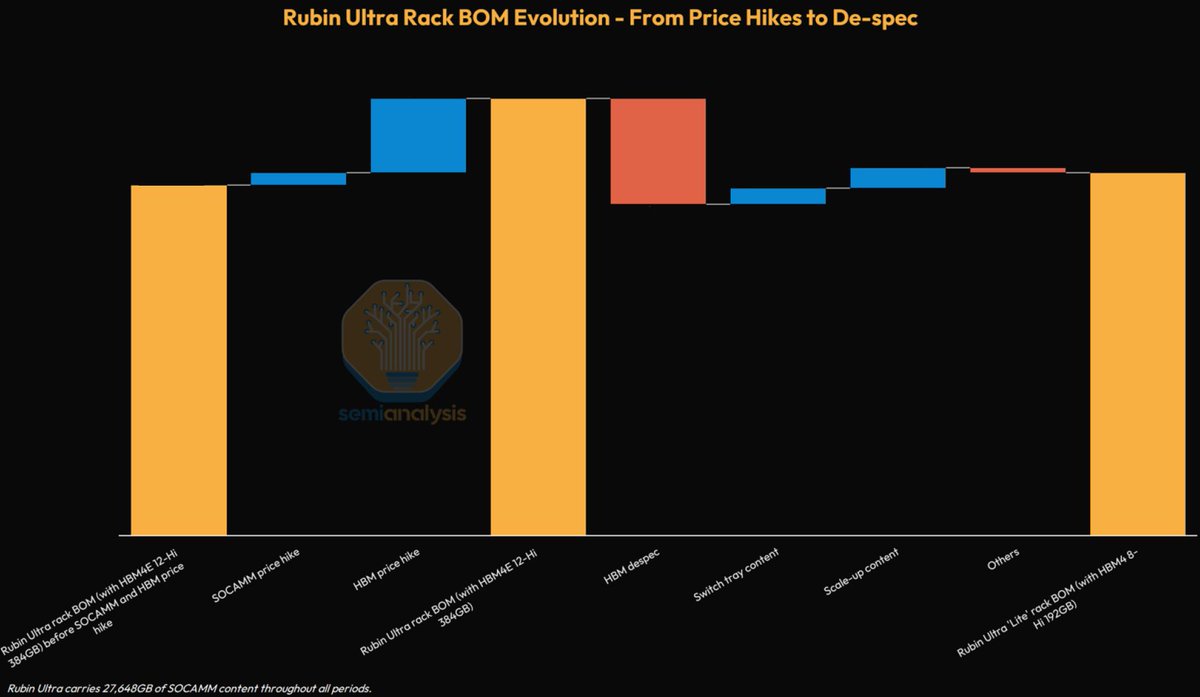
Stacking more DRAM dies on top of each other in a single HBM module raises total memory capacity, but every added layer also adds thermal and yield problems that get worse the taller the stack gets. SemiAnalysis argues the industry misjudged where that tradeoff pays off. Taller 12-hi stacks looked attractive purely on capacity, but for inference workloads, which are bottlenecked on memory bandwidth far more than raw capacity, shorter 4-hi and 8-hi stacks deliver more bandwidth for every dollar spent on packaging and yield losses. Nvidia's decision to cut Rubin Ultra's memory capacity down to 192GB is presented as evidence the market is already correcting toward this view rather than chasing capacity numbers for their own sake. For teams planning hardware purchases or capacity for the next generation of accelerators, the practical implication is that memory bandwidth, not stated capacity, should drive comparisons between competing chip designs, and that supply for shorter HBM stacks is likely to tighten as more vendors follow the same shift.
Context
More memory does not always make an AI server better value. SemiAnalysis argues that four-layer stacks of high-bandwidth memory can offer a cheaper way to feed data to processors than taller stacks. In its analysis, four layers retain the full data interface of the discussed memory design while using fewer memory chips. Capacity falls, but bandwidth need not.
That trade works when the system already has enough capacity for model parameters and the working data retained for active requests. If reading that data quickly is the bottleneck, extra storage contributes little. Larger models or more simultaneous requests can make capacity valuable again, so the argument depends on the workload and the whole system's memory budget.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…