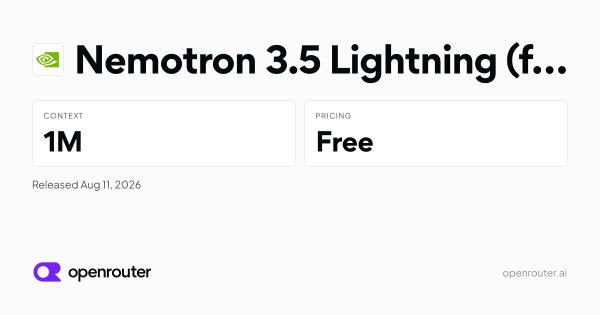
The context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → capacity advertised for NVIDIA's Nemotron 3.5 Lightning does not describe every hosted endpoint. OpenRouter's September 11 snapshot listed a 262,144-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → context window for its standard endpoint and one million tokens for the free endpoint. Its guide also recorded different structured-output support between them. An application switching endpoints could therefore exceed the destination's input limit or lose a required response-format capability. The endpoint's supported limits determine what a request can use.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.