Gemini Live audio
- Source
- simonwillison.net
- Date
Context
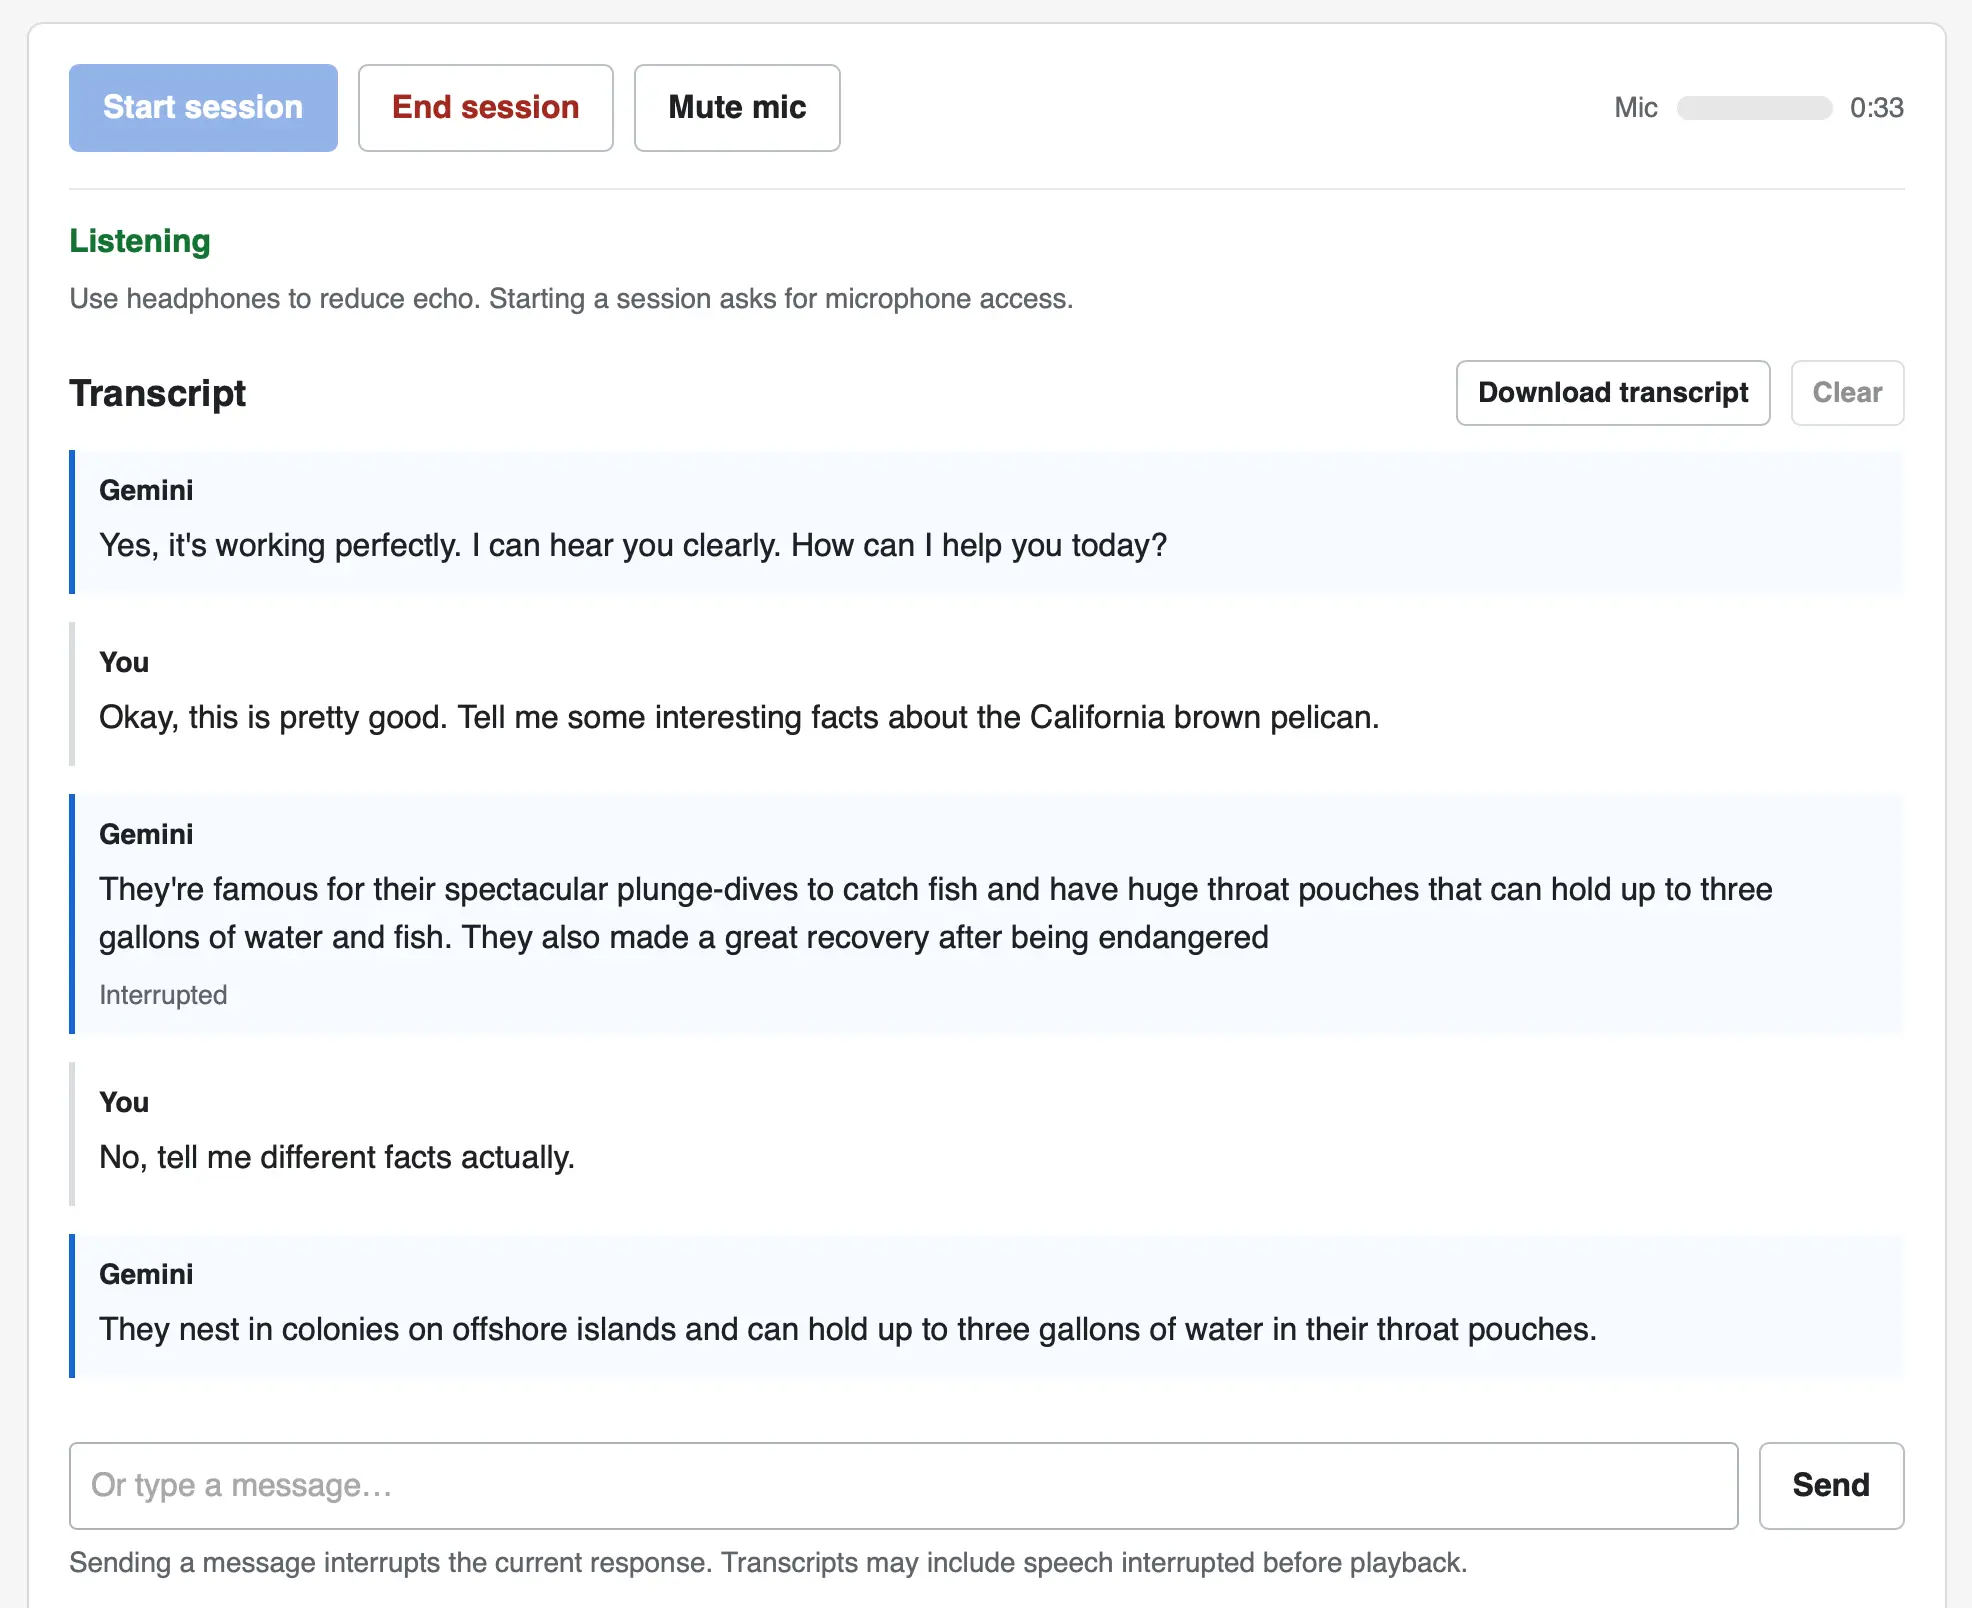
Simon Willison published a browser interface for trying Google's Gemini Live speech models, and the post says GPT-6 Astra built it from Google's documentation. The interface lets a user choose a model and voice, add an optional , and hold a spoken conversation that allows interrupting the model while it is talking.
According to the post, the interface uses no libraries. It connects to the service over a WebSocket and uses the browser's Web Audio API for both capturing speech and playing responses. The example suggests that an interruptible voice demo can be assembled from built-in browser audio and a connection, and the interruption behavior is what distinguishes conversation from playing back a generated recording.
- Google shipped two new speech-to-speech models, Gemini 3.8 Live and a 3.8 Live Extended Thinking variant, accessible over the Gemini Live API.
- Simon Willison built a working voice-chat web UI for the new models using no client libraries at all, connecting directly to the wss://generativelanguage.googleapis.com BidiGenerateContent WebSocket endpoint.
- The demo captures and plays back audio entirely through the browser's native Web Audio API AudioContext, and supports interrupting the model mid-response.
- system prompt — The standing instructions a model receives before any user input — defining its role, rules, tools, and tone for the whole conversation.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
Checking sign-in…
Loading comments…