The Road from 2 GPUs to a 32-GPU Cluster
- Source
- x.com
- Author
- Max Zanoga
- Date
Context
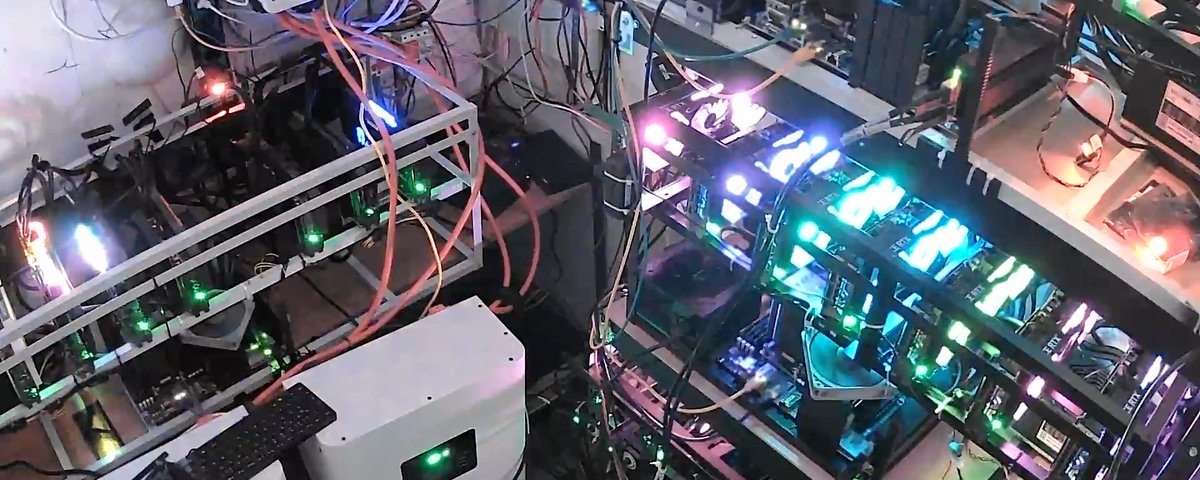
Scaling a home AI cluster requires making its connections and power delivery dependable. Max Zanoga describes expanding to 32 graphics cards across four servers, but the instructive part is what repeatedly stopped the build: too few expansion slots, networking setup, a difficult software stack, unstable card adapters and intermittent power resets.
Zanoga reports that replacing the adapters and power supplies made the cluster stable. The account also shows why the budget extends beyond the GPUs: solar equipment, batteries and cooling are listed separately from the server components. With performance benchmarks still promised, it is an integration case study rather than evidence of a general cost advantage over rented AI services.
- PCIe lanes, not slots or money, cap a build. At six cards the author swapped a Supermicro H12SSL-i motherboard for an ASUS ROMED8-2T purely for lanes, then hit the ceiling again until MCIO adapters freed up more.
- Going multi-node was the real jump. llama.cpp RPC over Ethernet had too much latency, so the fix was used datacenter gear from eBay: a Mellanox SB7800 InfiniBand switch and ConnectX-6 cards, which then needed 3D-printed cooling shrouds.
- The nastiest bug was power. Dell D2400E-S0 supplies would randomly cut power to a GPU with no relation to load and no way to reproduce it. Swapping to 2000W Super Flower units is what finally made the cluster predictable.
- Software was harder than hardware. Getting vLLM plus Ray running across the cluster took more than 100 Docker configurations and was the point where the author nearly quit.
- The economics only flip at volume: roughly $30k for GPUs and server components, bought before the memory price spike, which beats API pricing once you process billions of a month — and keeps the data local.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
“Two years later I have 32 RTX 3090s across 4 servers, 768GB of VRAM total, connected with InfiniBand and running on solar power.”
“once you process billions of tokens a month, running your own hardware is cheaper than paying for an API, and your data stays with you.”
“One thing I'd recommend: clone your SSD right after you get your switch. Make the clone first, then experiment, so you can always roll back.”
“The question I get most: roughly 30k just for the GPUs and server components.”

Checking sign-in…
Loading comments…