Claude’s new auto eval tool
- Source
- hamel.dev
- Author
- Hamel Husain
- Date
Context
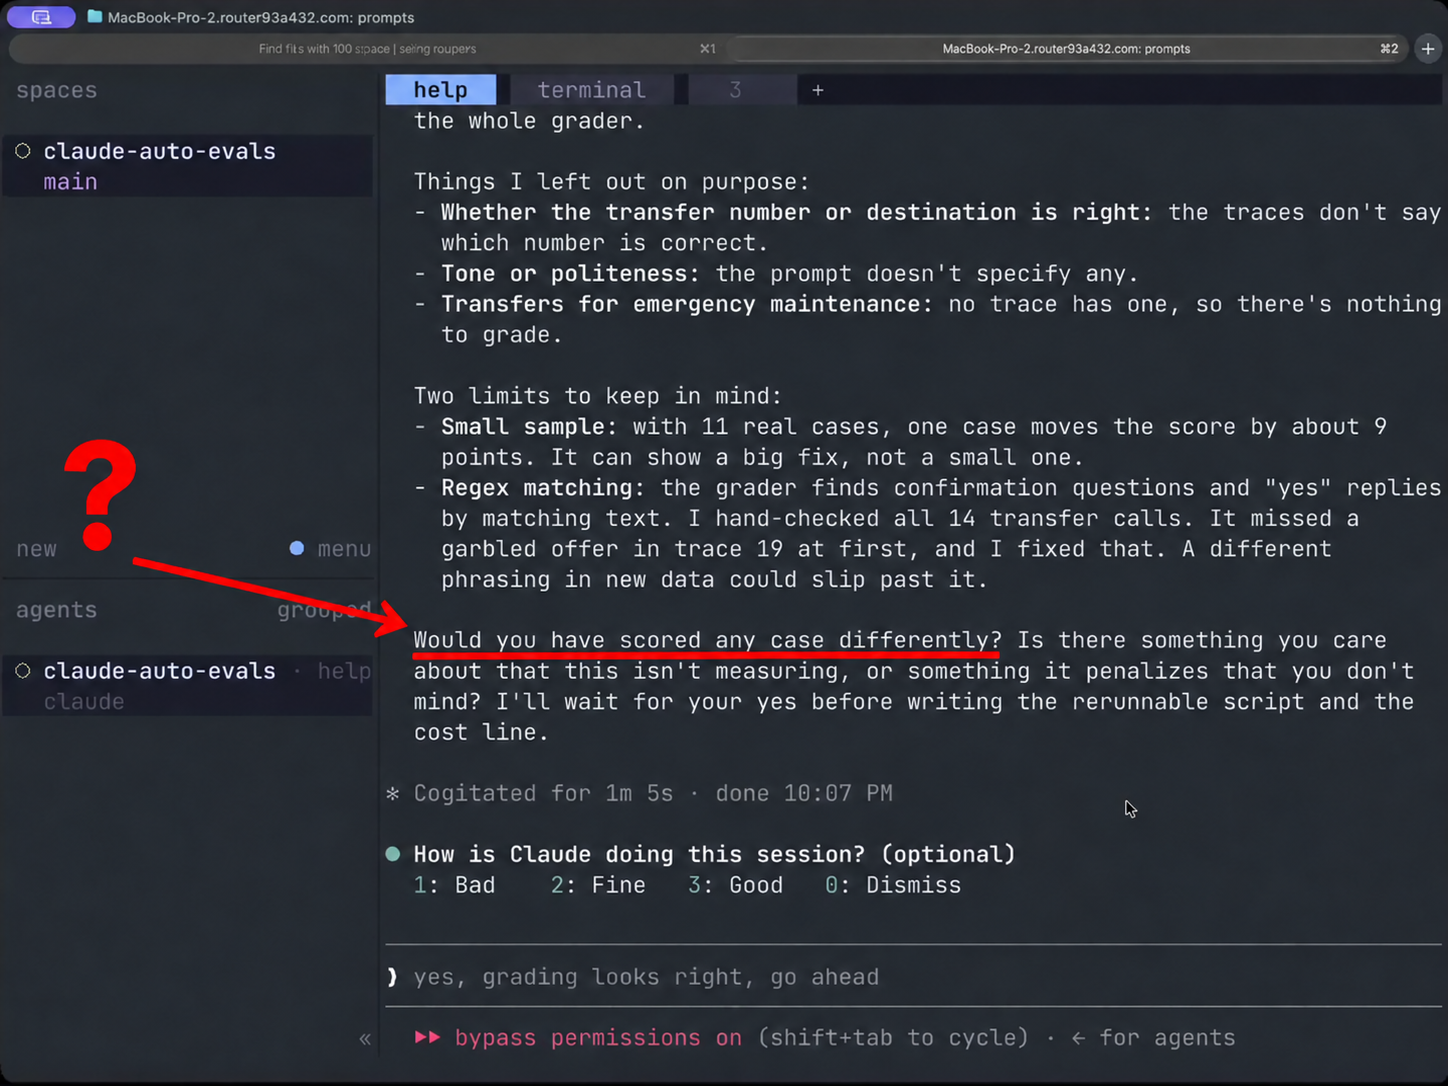
An automated tool still needs to make its judgments inspectable. In Hamel Husain's walkthrough of Anthropic's Claude evaluation tooling, the proposed a call-transfer test before the reviewers had examined their apartment-leasing conversations. Later it requested feedback on aggregate labels without enough case-level to judge them.
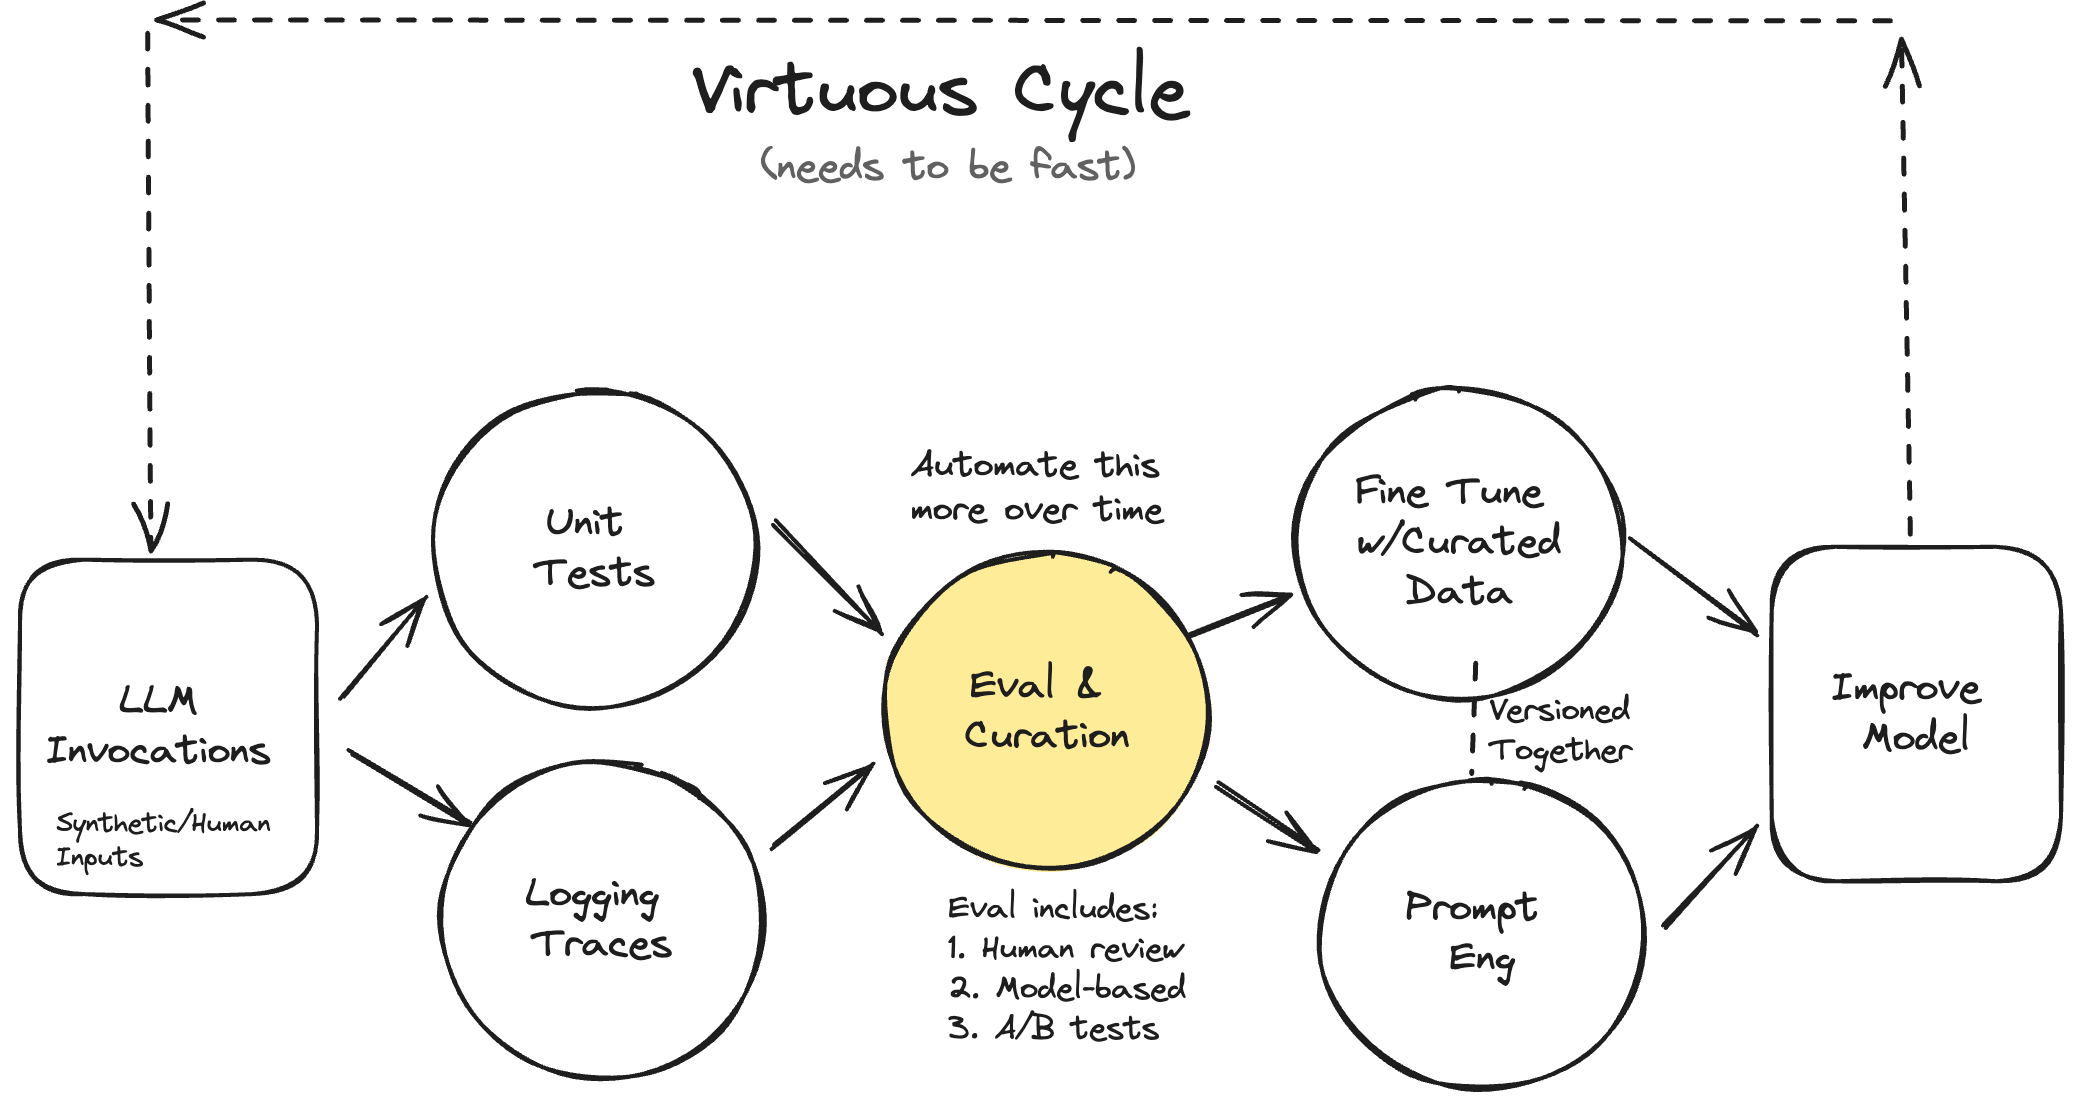
The walkthrough also calls the tool the strongest one-shot issue discovery Husain has seen. The objection concerns turning those discoveries into trustworthy tests: reviewers need to examine actual conversations, choose consequential failures and inspect the grading logic. The release's intended workflow includes human approval of the inputs and of the grader; the walkthrough shows why the quality of that review interface matters.
- Hamel Husain and Isaac Flath found the build_eval workflow in Anthropic's claude-api plugin asked them to pick a failure to turn into an eval before they had reviewed any conversations. Husain argues you should look at the data first, then decide which failures matter.
- To validate labels, the tool had reviewers skim long conversations in a Markdown file and report corrections in chat. The pair asked Claude to build a web annotation app instead, and Husain argues most eval work belongs in a web app rather than a chat window.
- The generated call-transfer evaluator bundled four checks, one and three code-based, into a single pass/fail score. Husain recommends scoping each eval to one error, or at least separating code checks from judge checks, and reading the judge prompt itself.
- On the positive side, Husain says the plugin's one-shot issue discovery surfaced problems with human handoff, formatting and voice behavior that other auto-eval approaches had missed, the strongest result of that kind he has seen.
- His verdict is to hold off for now. The plugin's author told him it would be updated in response to the feedback, so the specific workflow reviewed here may change.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- LLM-as-judge — Using one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.


Checking sign-in…
Loading comments…