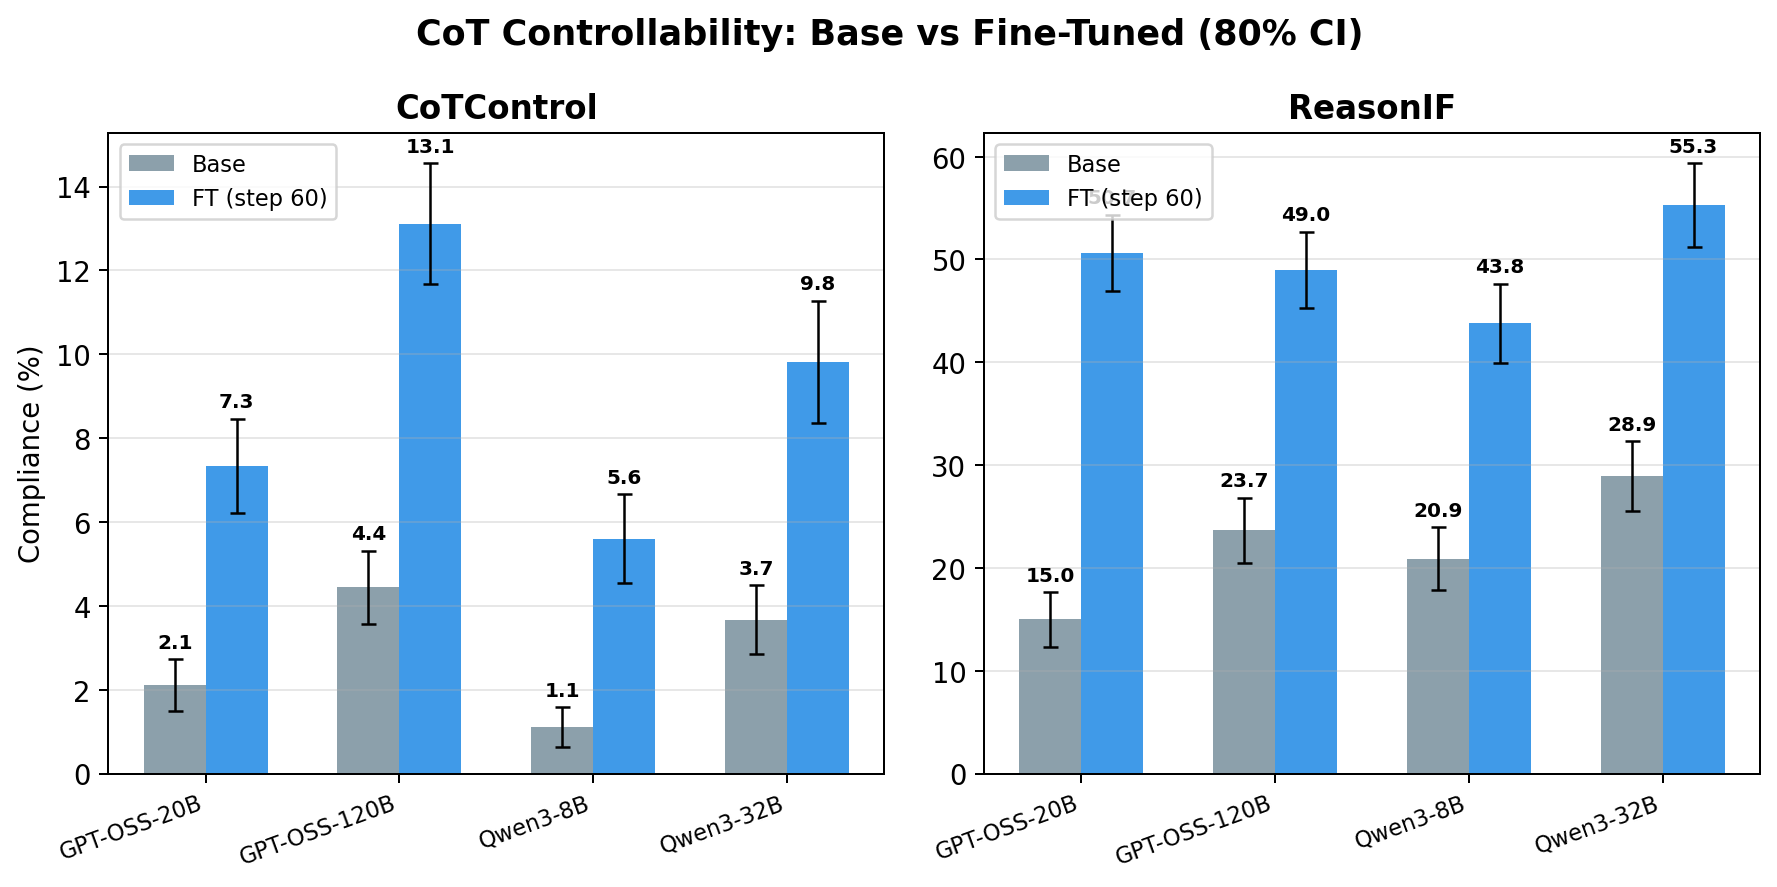
A model's written reasoning is easier to monitor if it cannot readily control which clues appear there. METR's fine-tuning experiments tested whether training on a small set of examples could make reasoning models better at following instructions about the content and format of their reasoning traces.
Compliance improved on a separate evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition →, although it remained low overall. The finding suggests that difficulty controlling these traces may change with training, so it should not be treated as a permanent safeguard. The researchers explicitly did not establish that the improvement made monitoring less effective, and their targeted training setup differs from ordinary frontier-model training.
Terms in this piece · Glossary
fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
chain-of-thought — Having a model write out intermediate reasoning steps before its answer, which markedly improves performance on hard problems.
 articleWhen Chain-of-Thought Helps and When It Hurts: An Empirical Investigation of the Serial-Depth Bottleneck in LLM ReasoningTughanbulut Kurtulush
 articleWe tested every major AI reasoning system. There is no clear winner.Mike Knoop
 articleMeasuring Faithfulness In Chain Of Thought ReasoningAnthropic research