← All IntelIntel / post
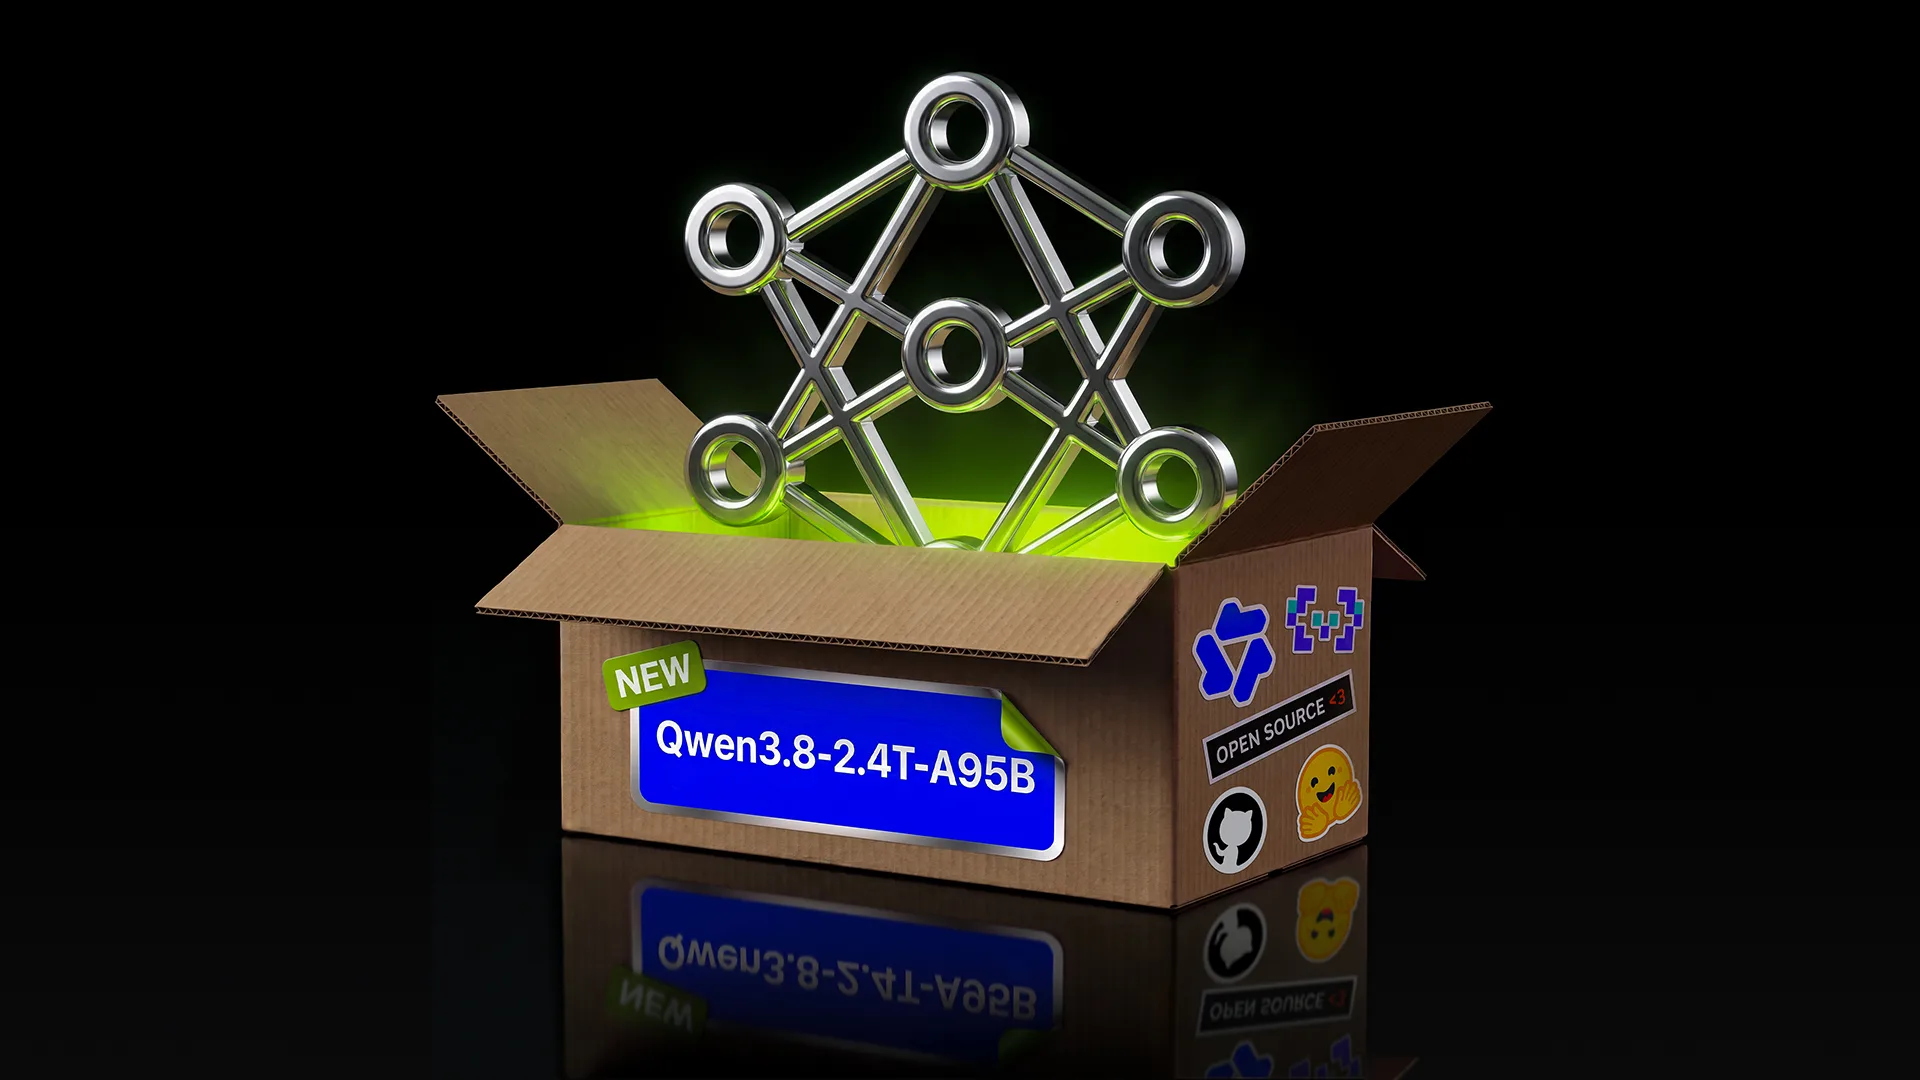
Big model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
- Source
- x.com
- Author
- alexocheema
- Date
Context
The 95-billion active-parameter figure describes only part of the model discussed in Alex Cheema's deployment post. Qwen's model card lists 2.4 trillion parameters in total and 95 billion activated, with a architecture that selects a subset of its experts for computation.
The linked release contains FP8 weights, which store numerical values at reduced precision. Cheema's proposed four-computer setup explicitly assumes a further reduction to four-bit weights. That makes it a proposal about a different representation of the model, rather than evidence that the linked release has been demonstrated on that setup.
Terms in this piece · Glossary
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Read the source x.com
More from alexocheema
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference
 postLocal inference crosses over: the M5 Ultra and the 1,000x claim
Recommended reads
Comments
Checking sign-in…
Loading comments…