Full Duplex Models: Moshi and the New Voice AI Paradigm
- Source
- youtube.com
- Author
- Julia TurcTop Viber
- Date

Context
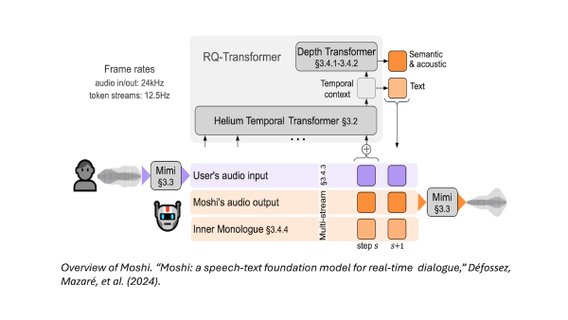
A voice assistant needs to keep hearing you while it speaks if it is to handle overlapping conversation. Moshi models the user's audio and its own audio as parallel streams, including periods of silence. Its technical paper describes how this permits simultaneous listening and speaking without imposing a fixed sequence of speaker turns.
That is the meaning of full duplex explored in this video. A brief acknowledgment can arrive while the assistant continues its sentence, while an interruption can supply new input during an answer. The architectural change concerns how conversation unfolds, separately from whether the assistant's answer is knowledgeable or correct.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
- RAG — Retrieval-augmented generation — fetching relevant documents first and pasting them into the model's context so it answers from your data instead of memory.
“They're not turn-based. They're more like time-based interaction where they're continuously taking in audio, text, video, and continuously providing output.”
Mira Murati
“It's almost ideological, I would say, right? In a way, when you impose by your human hands a cascade in several gesture rings or signal network, you know, you go against the philosophy of machine learning.”
Nao
“Being a bit pessimistic, I would say 1 or 2 years.”
Nao
“AI doesn't love you.”




Checking sign-in…
Loading comments…