Do Automated Evals Work?
- Source
- hamel.dev
- Author
- Hamel Husain
- Date
Context
Automated reviewers of AI-product traces caught many real failures in one test, but missed requirements that the traces themselves did not show. In a study of 100 production apartment-leasing conversations, Hamel Husain and coauthor Antaripa Saha compared six automated systems with 39 failures a domain expert had labeled by hand. The best system recovered about 87% of those failures, and every system found additional valid issues, though each also flagged some non-failures.
The reviewers received deliberately light product . All of them missed failures that looked fine in the transcript but fell short of the business's goals, such as giving up at a prospect's first objection, using Markdown in text messages, and keeping conversations that property rules said should go to a human. The authors recommend annotating traces yourself and letting an AI learn from those annotations over repeated rounds, because the criteria for good behavior often emerge only while reading. This is one dataset with 39 labeled failures, so the authors say it cannot rank the vendors.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
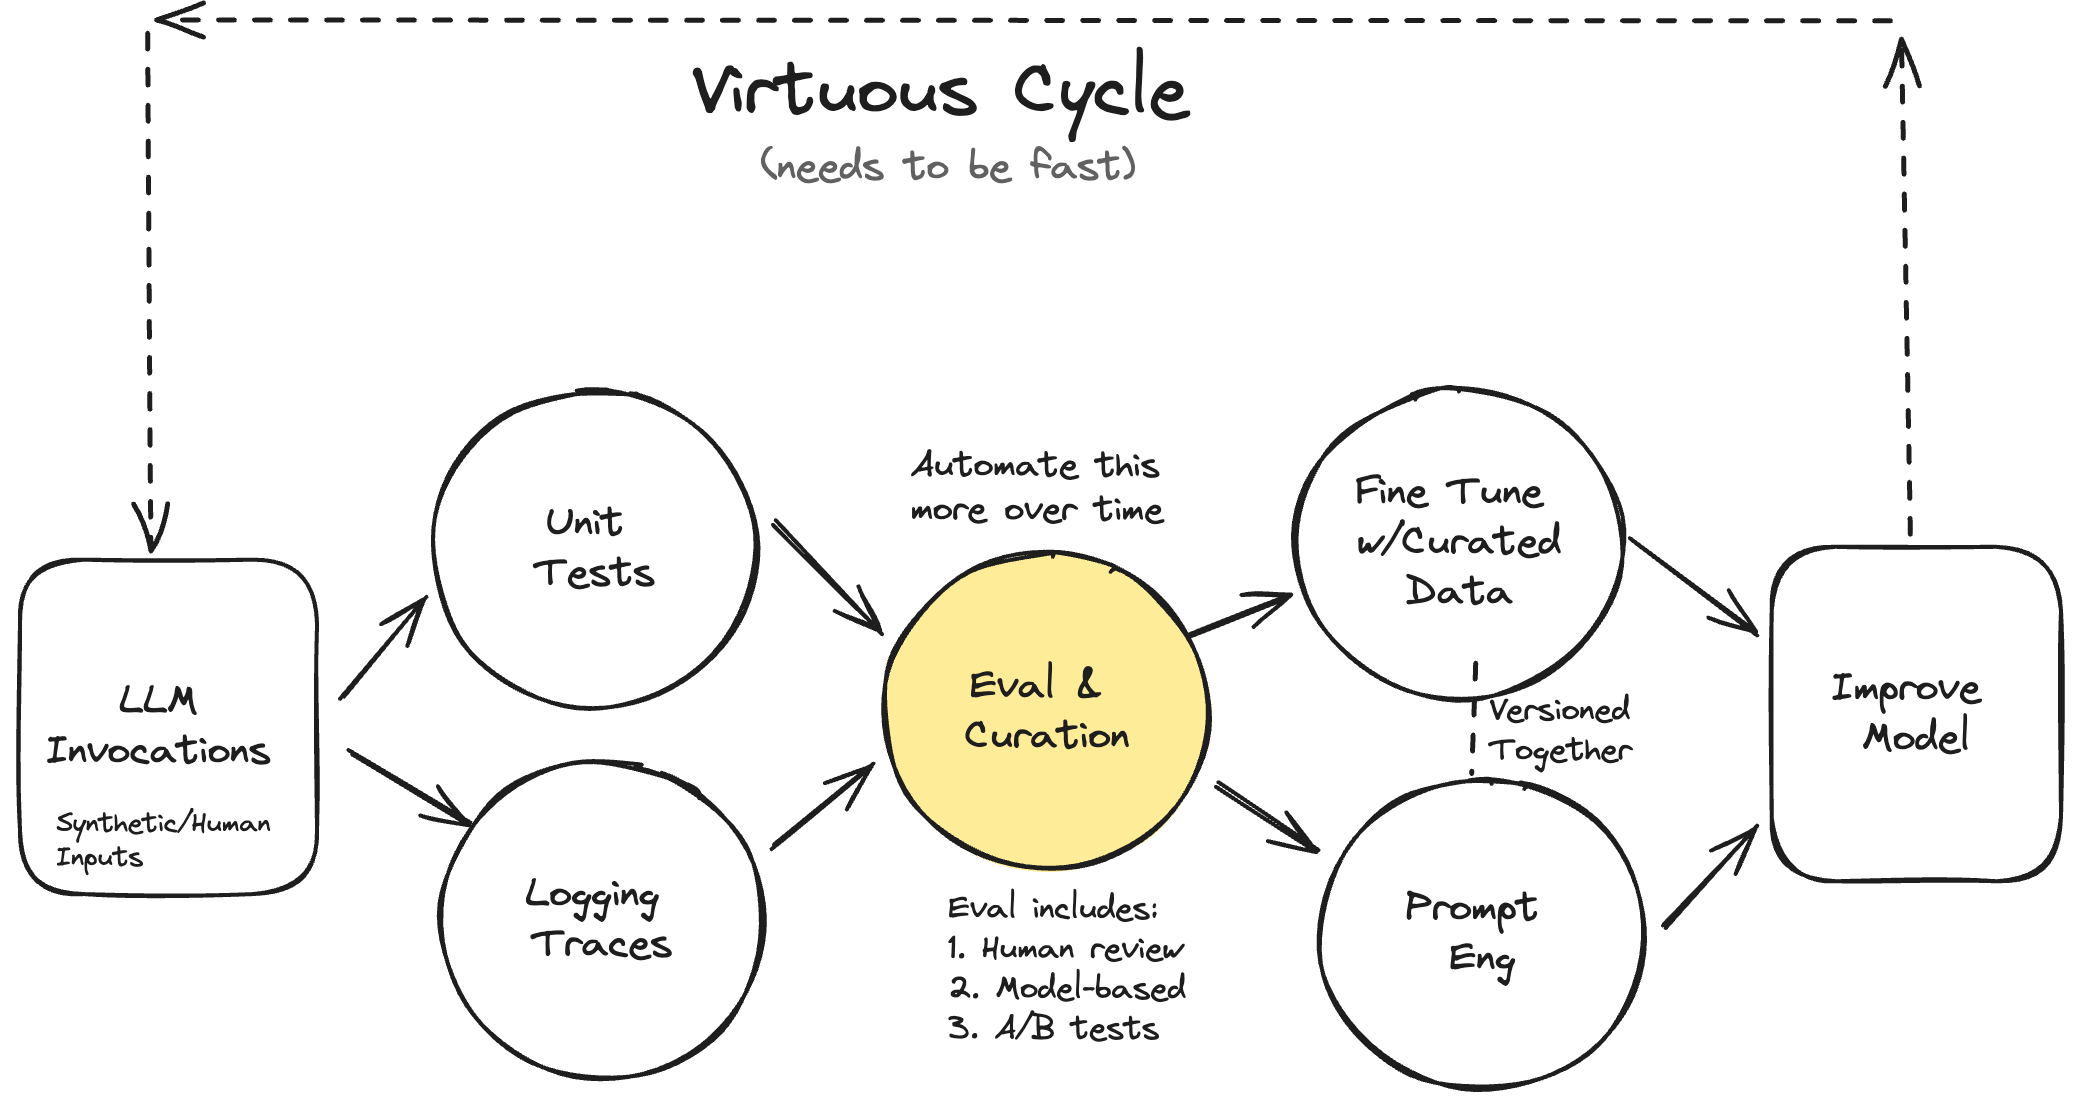
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…