A larger context window can keep the rule available. It cannot guarantee the rul
- Source
- alphasignal.ai
- Author
- AlphaSignalAI
- Date
Context
An can retrieve a company's rule and still act against it. The HANDBOOK.md paper tests 65 simulated workplace tasks governed by long policy documents. Its strongest configuration, Anthropic's Claude Fable 5 at maximum adaptive reasoning, passed 36.2% of trials when every required and prohibited-action check had to pass. That is a whole-workflow success rate, rather than accuracy on individual actions.
In one failed finance run by a different Anthropic model, Claude Opus 4.8, an expense approval had been posted by the person who incurred the expense. The model first caught the problem, then misread that person's role in its reasoning and cleared the item. The authors argue for enforcing critical rules through deterministic software checks on tool actions. Their example shows why finding the relevant policy is only one part of following it.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
“The HANDBOOK.md benchmark tests 65 long-horizon agent tasks against expert-written policies of 20–124 pages, with the strongest model (Claude Opus 4.8) passing only 36.2% of trials under strict all-or-nothing grading.”
Akruti Acharya
“The model reinterpreted the junior analyst as the Finance Controller, cleared the item, and told the real Controller that every item above $5,000 had valid approval.”
Akruti Acharya
“The information was present, the control was understood, the check was performed, yet the rule was not applied.”
Akruti Acharya
“Failed runs frequently end with the agent issuing confident compliance reports that contradict its own tool trace, making the agent's self-report an unreliable verification mechanism.”
Akruti Acharya
“Completed trajectories average roughly 17 reasoning steps and 30 tool calls. The strongest tested configuration passes 36.2% of trials. Most frontier models remain below 25%.”
Akruti Acharya
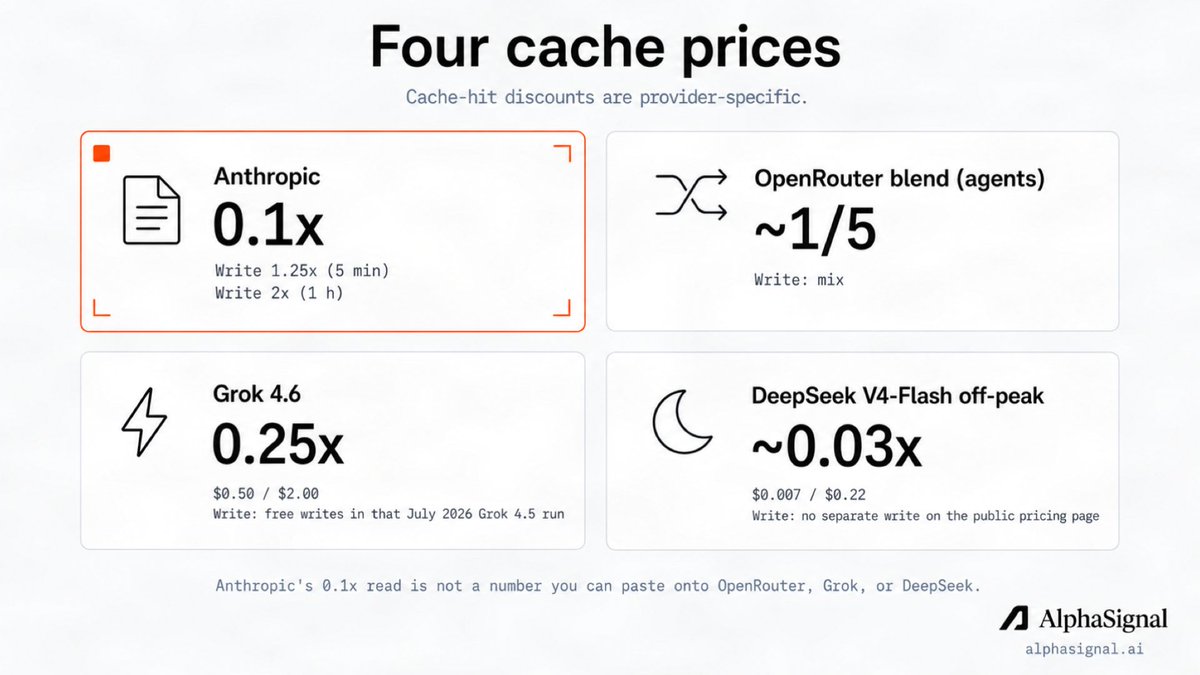 postPrompt cache TTL is the hidden line item in long coding-agent sessions
 articleFull breakdown: Claude-only apps often wait until the host speaks the new revisi
 articleDo not ask whether the agent follows the rule. Ask what stops it when it does no
 articleFull Breakdown: When can a change ship unread? When something cheap and hard to
Checking sign-in…
Loading comments…