Qwen 3.8 Max: Alibaba's 2.4T Open-Weight Model for Coding and Cowork
- Source
- latent.space
- Author
- Latent Space
- Date
Context
Qwen’s flagship launch opened a path toward running the model outside its hosted service, but availability arrived in stages. The launch digest described API access with downloadable weights promised later. The team’s official release log subsequently dated the large model’s weight release to August 12, 2026, and the 27B release to August 14.
The download also has a different capability boundary. The large model’s official card identifies it as text-only and requiring thinking mode. It describes hosted Qwen3.8-Max as adding features including visual input and non-thinking operation. Choosing self-hosting therefore requires checking the downloadable model’s own capabilities rather than assuming every hosted feature comes with it.
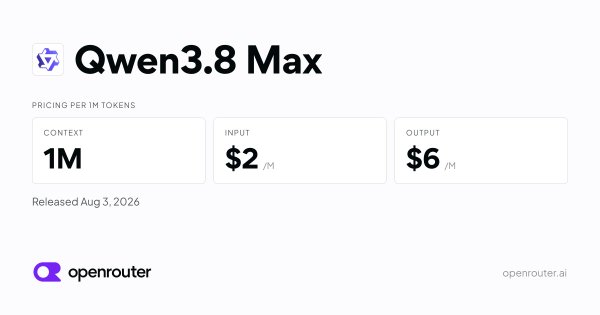
- Qwen 3.8 Max is a 2.4T-parameter (~95B active, ~4% activation) with 1M , promised , priced at $2/$6 per million tokens - and its 27B sibling goes open-weight too.
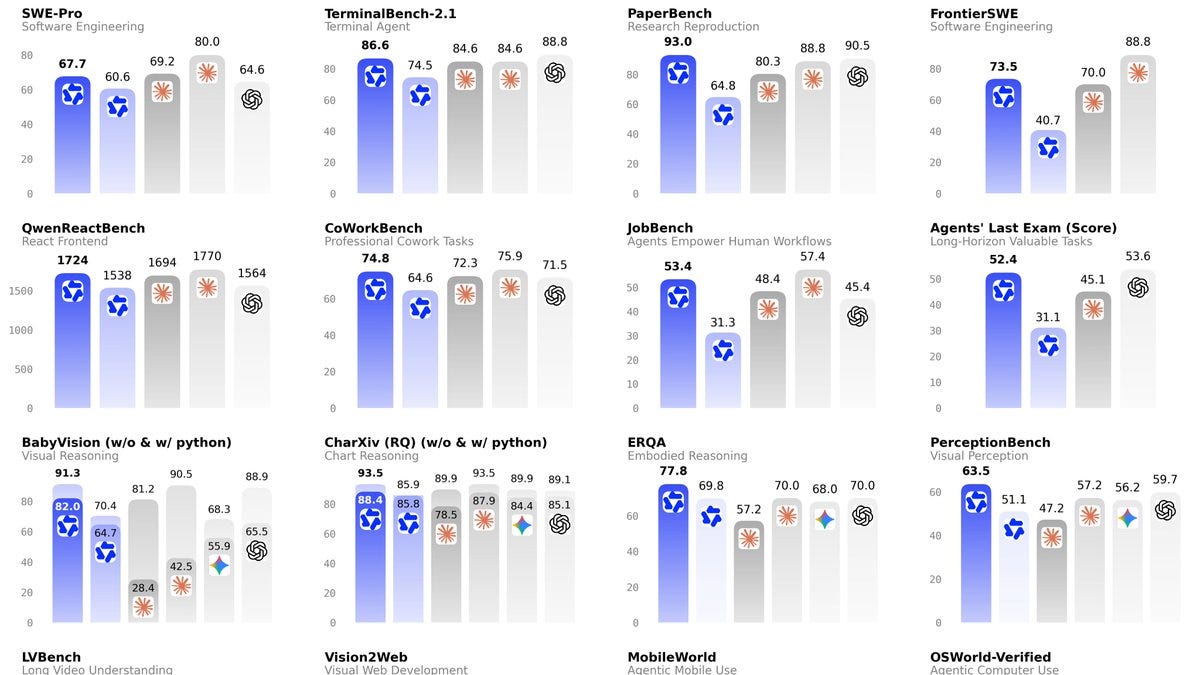
- The demos are long-horizon: 10+ days of unattended coding, a 125-hour autonomous research loop that beat the original papers data-selection benchmark by +2.71, top-13% against 526 human teams in a data-science challenge, and a chip-design flow that cut 8,298 gates to 678 with 81%
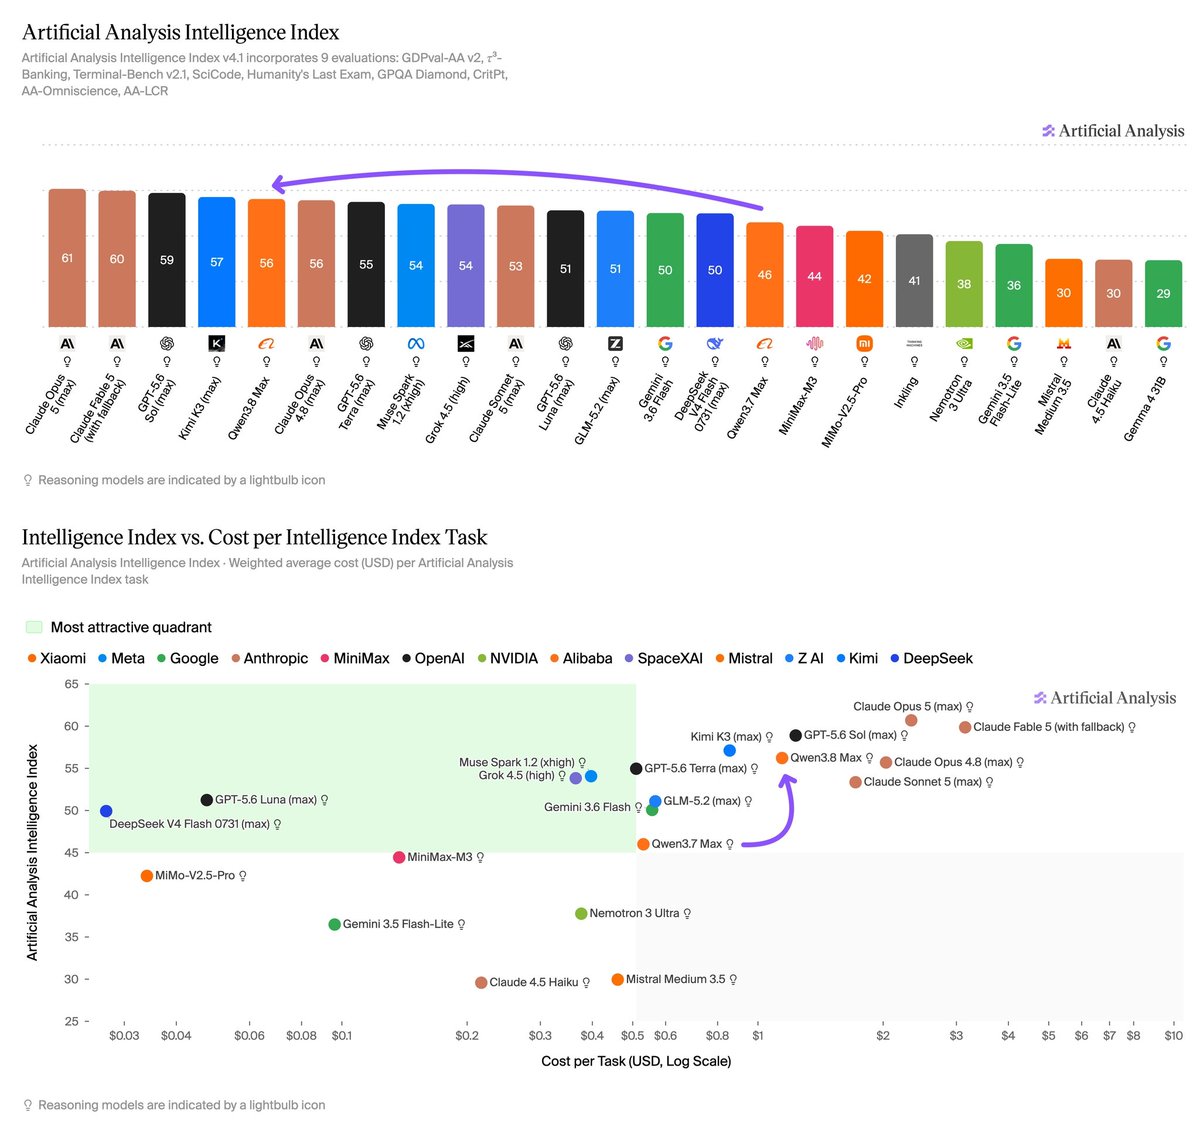
- Independent numbers hold up: Vals Index 66.1 (#2 open-weight, matching Claude Opus 4.7 at ~2.3x lower cost), 87.3%, #4 on Frontend Code Arena, #2 on Vision Arena.
- The 2.5-month pace is the trend to watch: Qwen 3.7 Max to 3.8 Max gained 8.6 Vals points while cutting prices.
- Counterpoint: open-weight is not locally runnable at this tier - these giant sparse models need 8+ H100/B200-class GPUs just to load, so open increasingly means operationally open, not laptop-open.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
“China is no longer lagging behind but competing on equal footing”
kimmonismus
“Open models are winning now”
JonathanRoss321
“Looks like Opus 4.8 is mostly subsumed”
deliprao
“the two biggest OSS models in the world use linear attention?”
Elie Bakouch


Checking sign-in…
Loading comments…