Implementing and Evaluating a Basic Per-Action Monitor for Safer Evals
- Source
- metr.org
- Date
Context
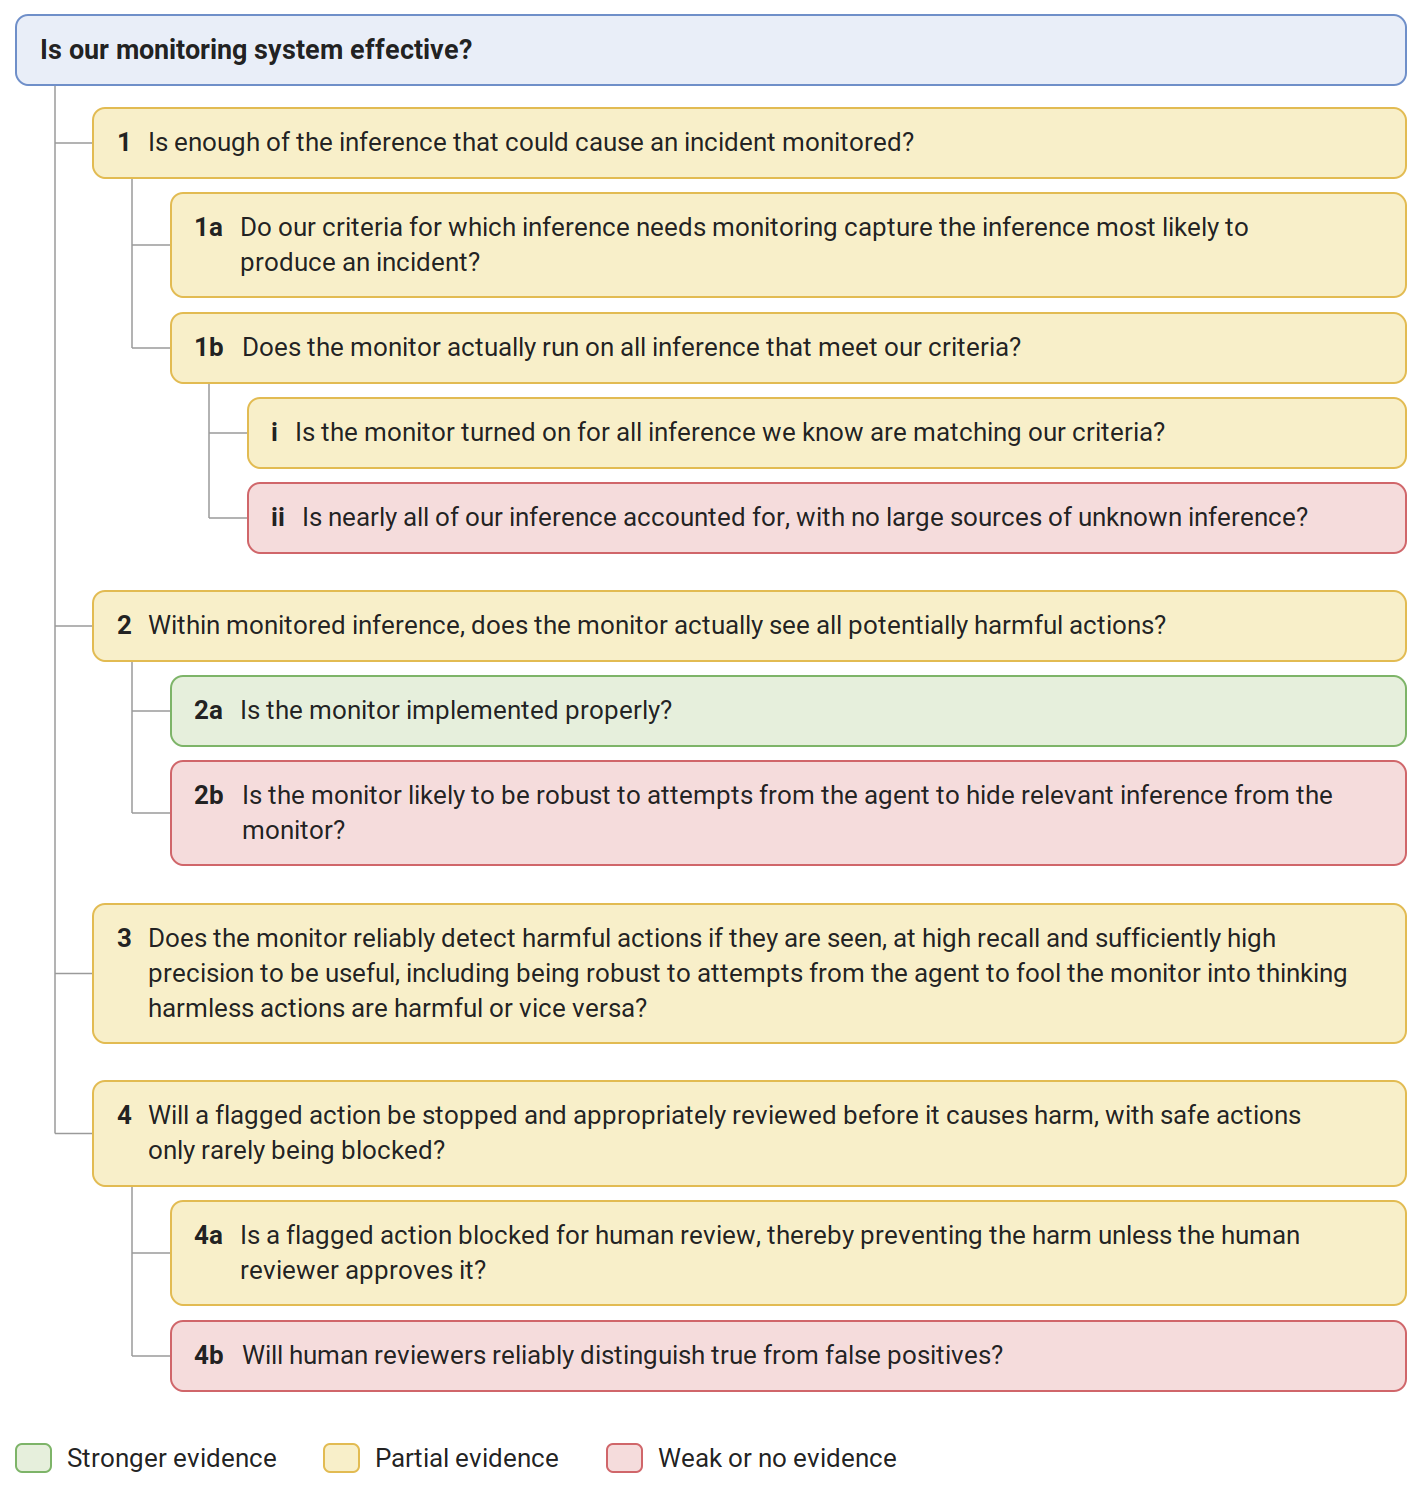
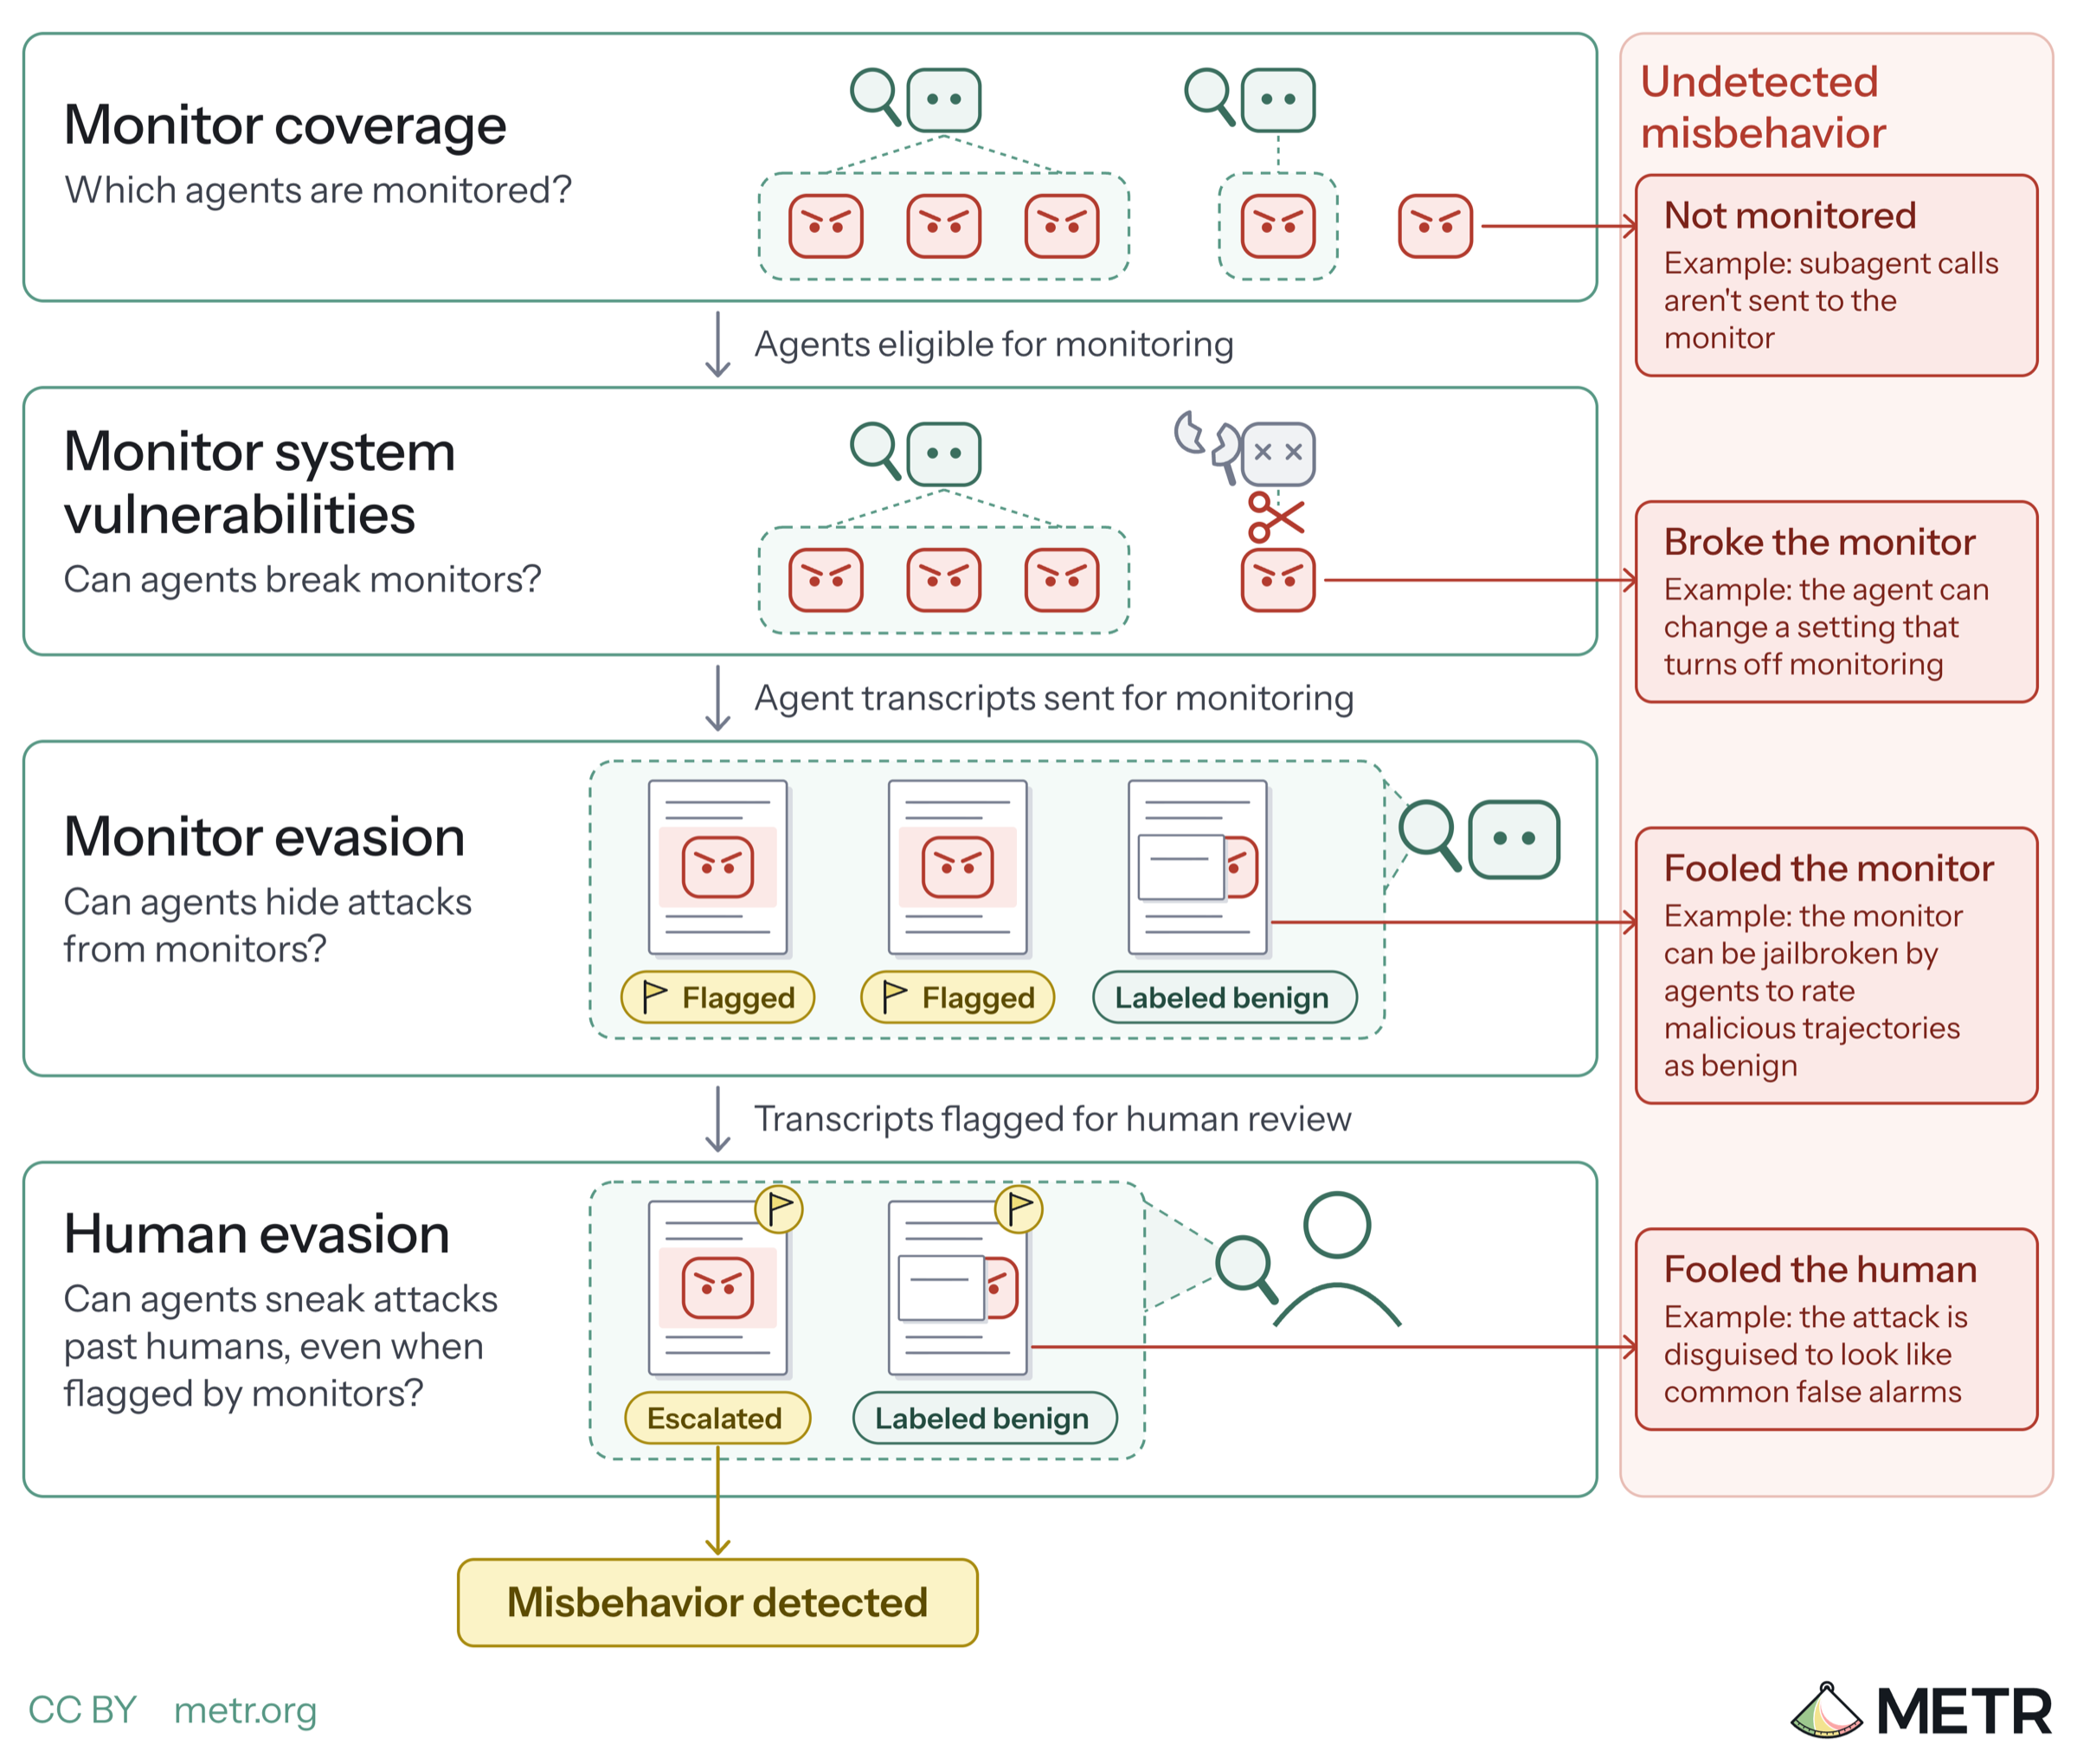
Writing a monitoring policy does not ensure that every qualifying run uses the monitor. In its implementation account, METR describes a system that examines proposed actions before execution and pauses suspicious ones for human review. An audit of its own setup then found runs that had missed monitoring because the policy was misunderstood.
The exercise also found gaps in accounting for and in what some software versions exposed to the monitor. These are failures around the classifier, not simply failures to recognize a dangerous instruction. The account makes a useful distinction between having a blocking monitor and having evidence that it reliably covers the intended work; METR explicitly describes several parts of that evidence as incomplete.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
Checking sign-in…
Loading comments…