An Agentic Paper Reviewer That Matches Human Reviewer Agreement
- Source
- x.com
- Date

Releasing a new "Agentic Reviewer" for research papers. I started coding this as a weekend project, and @jyx_su made it much better. I was inspired by a student who had a paper rejected 6 times over 3 years. Their feedback loop -- waiting ~6 months for feedback each time -- was painfully slow. We wanted to see if an agentic workflow can help researchers iterate faster. When we trained the system on ICLR 2025 reviews and measured Spearman correlation (higher is better) on the test set: - Correlation between two human reviewers: 0.41 - Correlation between AI and a human reviewer: 0.42 This suggests agentic reviewing is approaching human-level performance. The agent grounds its feedback by searching arXiv, so it works best in fields like AI where research is freely published there. It’s an experimental tool, but I hope it helps you with your research. Check it out here:
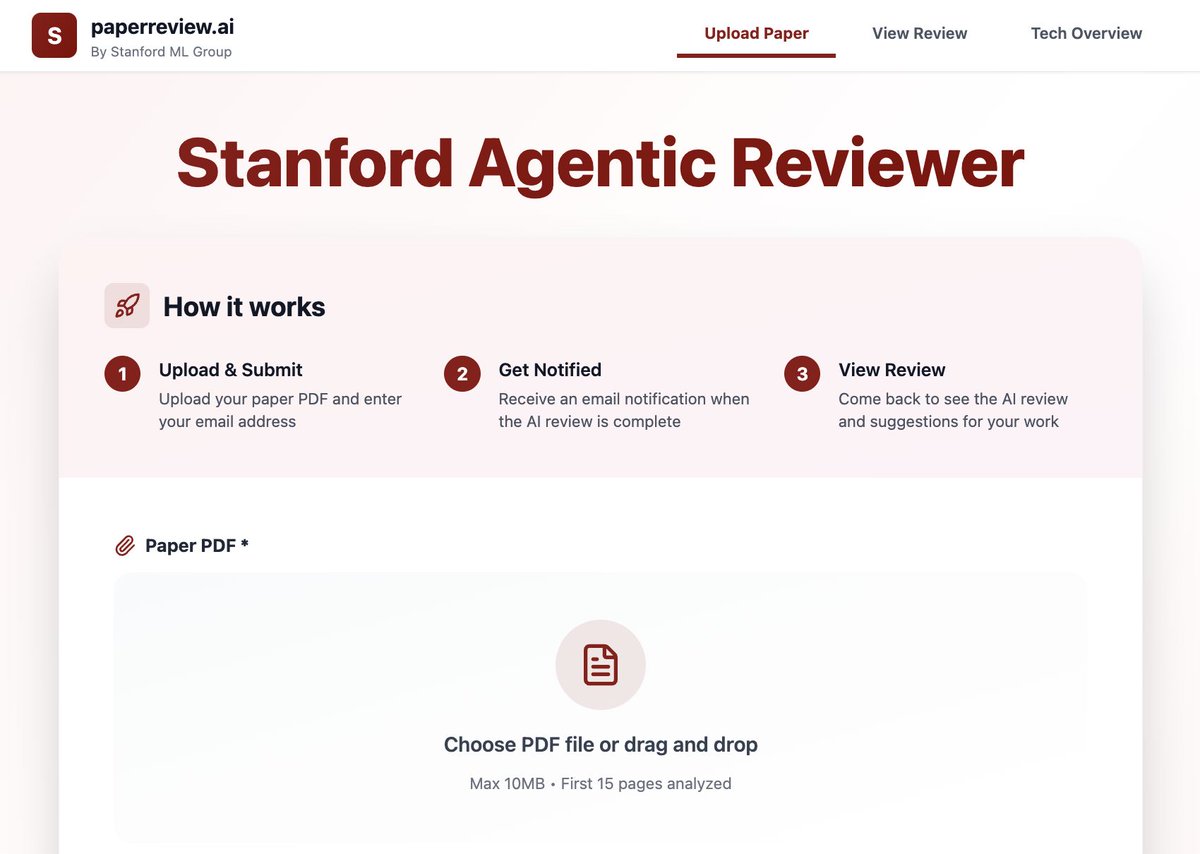
NeurIPS received 21,575 paper submissions this year. Our Agentic Reviewer, released last week, just surpassed this in number of papers submitted and reviewed. It's clear agentic paper reviewing is here to stay and will be impactful! https://t.co/v4ZjnCgskN
Context
The Agentic Reviewer introduced by Andrew Ng is designed to give researchers faster feedback while they revise papers. Its technical overview describes finding related research on arXiv and using that material alongside the submitted paper to generate a review.
The reported human comparison concerns ratings. After fitting a scoring model on 150 conference submissions, the team tested it on 147 others. AI-to-human rank correlation was 0.42, compared with 0.41 between human reviewers. This measures similarity in how scores order papers. It leaves the factual accuracy and usefulness of individual criticisms unproven, and the tool is described as experimental.
 articleHumanize: Judgement Engineering for Agentic CodingSihao Liu, Ligeng Zhu, Zijian Zhang, Dongyun Zou, Zhengyang Zhang, Changye Li, Song Bian, Song Han, Tony Nowatzki
 blogReviewBench: An open benchmark for AI code reviewMichelle Zhou
 postSakana AI benchmarks LLM peer review with planted contradictionsSakana AI
Checking sign-in…
Loading comments…