Many SWE-bench-Passing PRs Would Not Be Merged into Main
- Source
- metr.org
- Date
Context
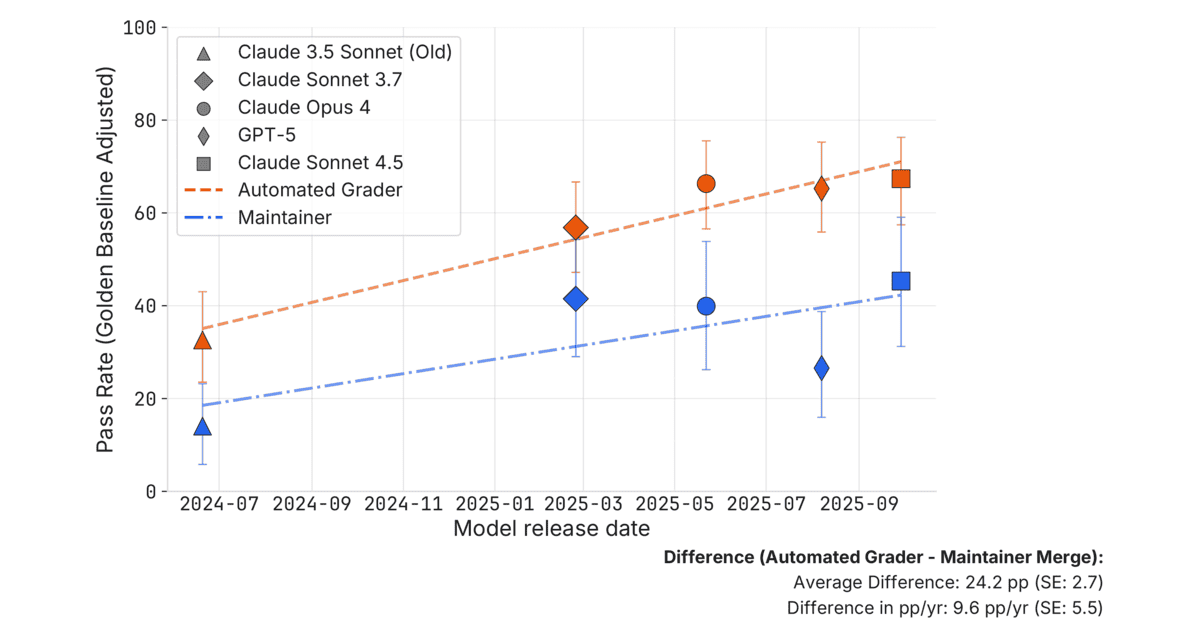
Passing a 's tests is a narrower achievement than producing a change a maintainer would merge. In METR's review study, maintainers found problems with functionality, effects on other code and code quality in patches that passed 's automated checks. The study also re-reviewed original human patches to account for disagreement in maintainer decisions.
The agents had one submission opportunity, whereas developers normally revise work after feedback. The result therefore does not establish that those models could never produce acceptable fixes. It identifies a gap between the benchmark's acceptance rule and the project's: test success is evidence of progress, while maintainability and review remain part of completing the work.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.

Checking sign-in…
Loading comments…