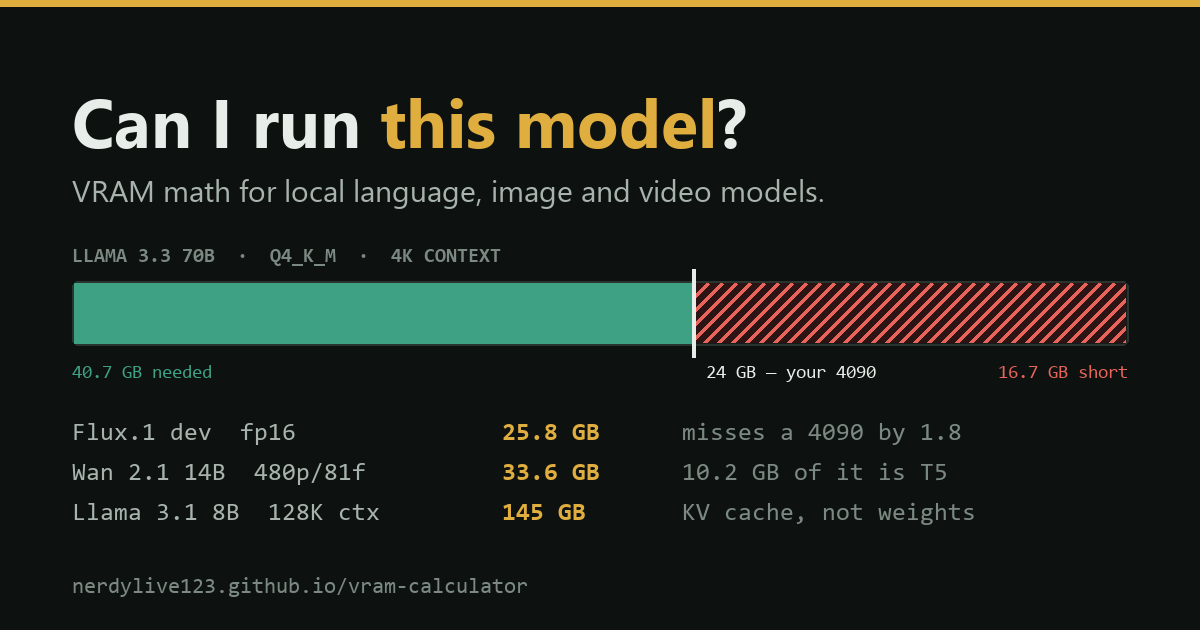
Can I Run This Model? explains why a LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition →'s stored weights are only part of its GPU-memory requirement. Its calculator adds memory for the attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → cache, which retains information used while processing a sequence, and runtime overhead.
In the displayed formula, cache memory grows with context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → and the number of simultaneous sequences. A configuration that fits a short, single conversation can therefore require more memory when either setting increases. The page exposes its arithmetic so users can see which component changes the estimate. These are planning estimates, rather than benchmark results proving that a particular deployment will fit or achieve a given speed.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.