Introducing Scout 1.0: A new SRE model powering Bits AI with frontier performance at a fraction of the cost
Source
datadoghq.com
Date
Context
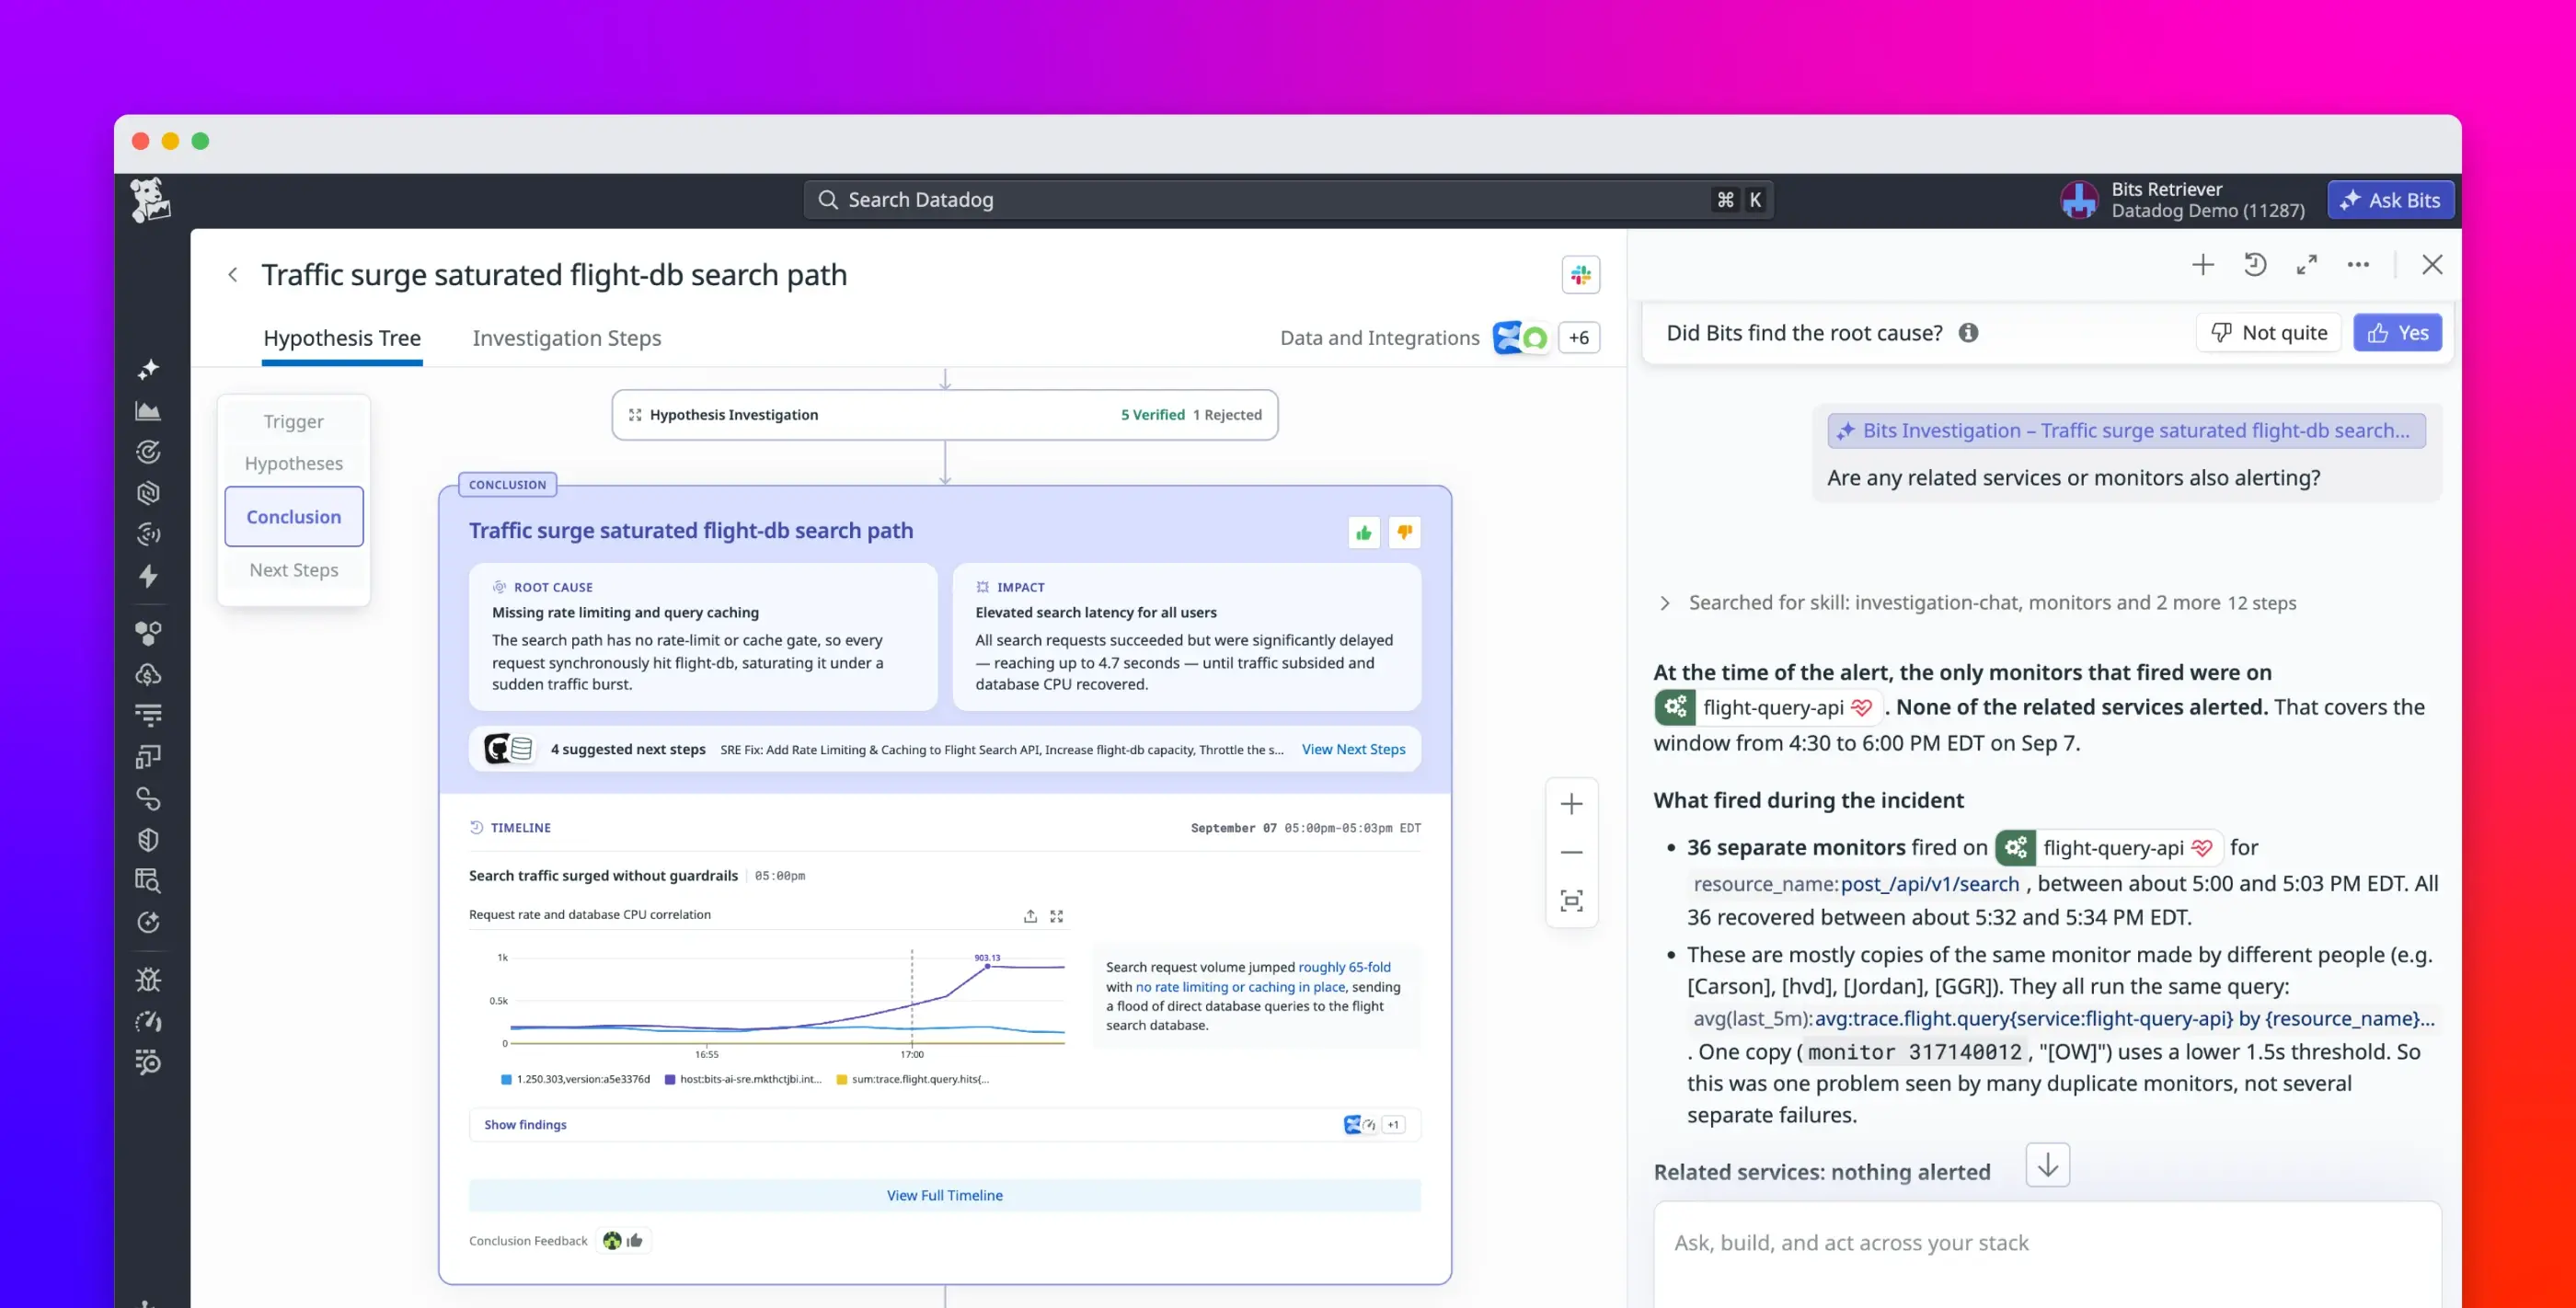
An investigation score is not the percentage of incidents an AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → resolves. In Datadog's Scout announcement, the reported score measures agreement with expert explanations. The company trained the model to gather telemetry and support a diagnosis, while autonomous remediation remains a planned extension.
The specialization is intended to make repeated investigations inexpensive enough to run on more alerts. That is a different claim from replacing the full incident-response process: identifying a likely cause still leaves the decision and work of restoring service. The reported cost comparisons are estimated inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → costs under the company's evaluations, and the product was in a limited preview at announcement.
Key takeaways · AI-distilled
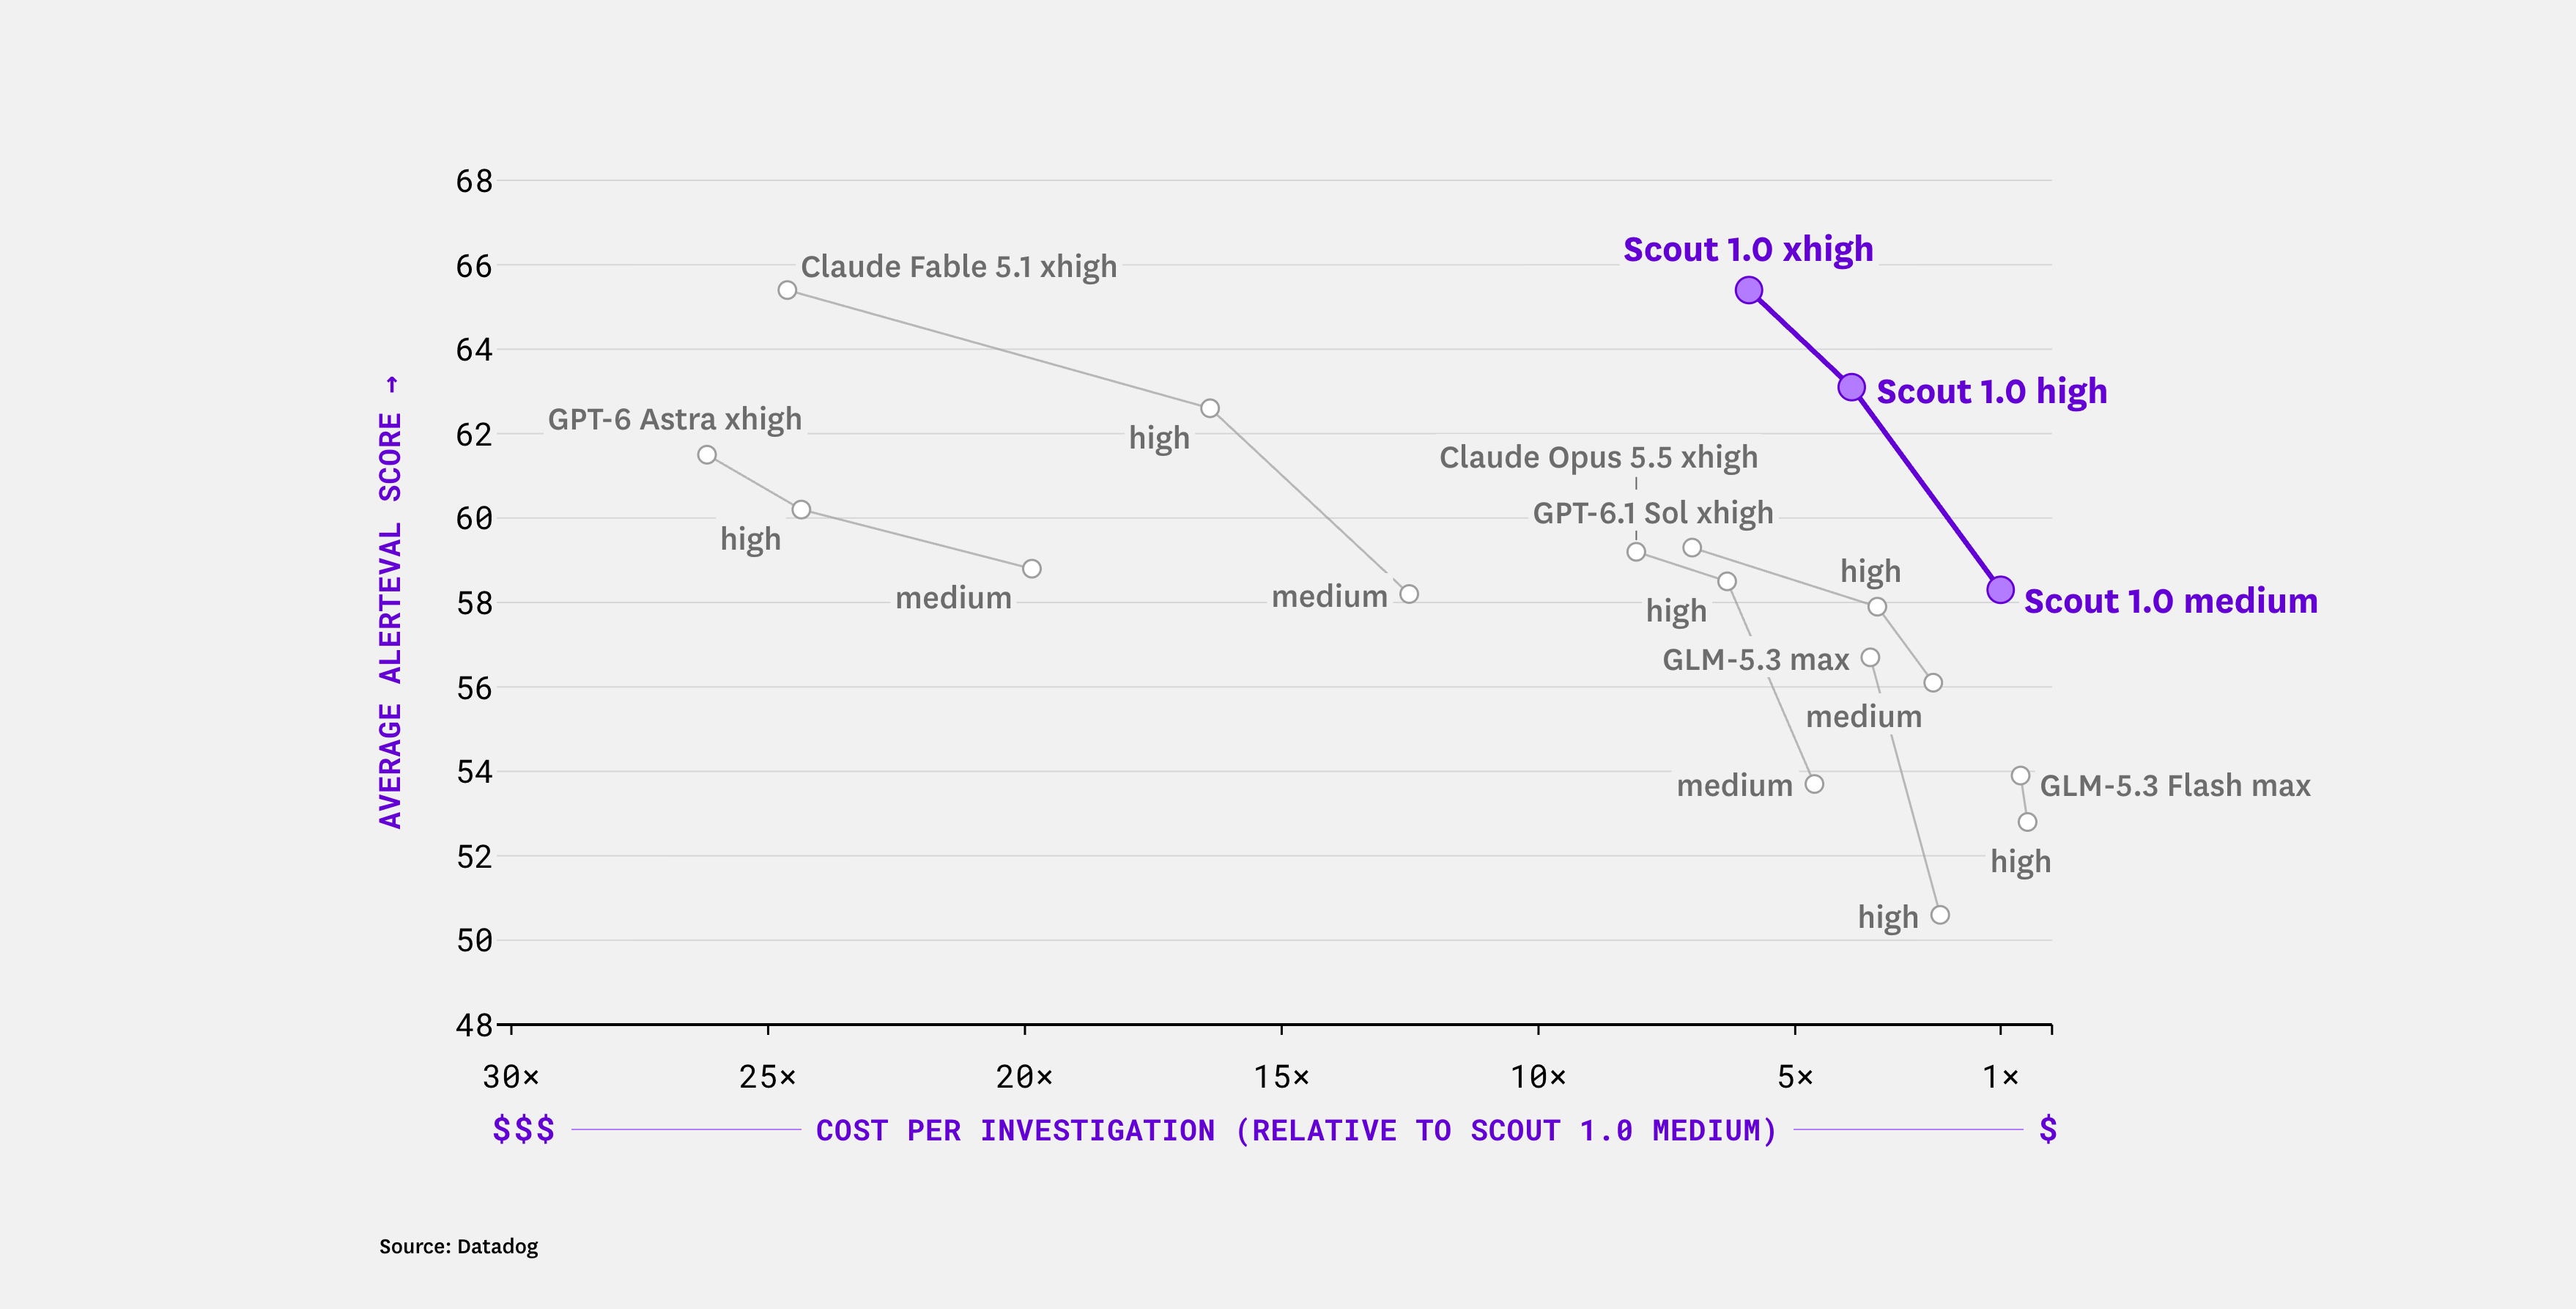
Datadog reports Scout 1.0 medium matches GPT-6.1 Sol high and Claude Opus 5.5 high at 3-8x lower estimated inference cost on its target scenarios, and Scout 1.0 xhigh matches Fable xhigh at 4x lower cost.
Scout is GLM-5.3 Flash post-trained with reinforcement learning in investigation simulations built from historical incidents and telemetry with known causes, rewarded for finding the cause and supporting it with evidence; Datadog says the simulations contain no customer data.
evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → uses AlertEval, built from real alerts, archived telemetry and engineer-written root causes, plus the third-party SREGym benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition →, where Datadog says Scout 1.0 medium surpasses GLM-5.3 at more than 4x lower cost.
Datadog notes its scores measure agreement with expert reference explanations on a 0-100 scale, not the share of incidents solved, and costs are estimates per investigation relative to Scout 1.0 medium.
The rationale is volume: each investigation needs repeated model calls to form hypotheses and query telemetry, so cheaper inference lets Bits run an order of magnitude more investigations, earlier in incidents; remediation is the stated next step.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.