Prompt caching in LLMs, clearly explained
- Source
- x.com
- Author
- Avi Chawla
- Date
Context
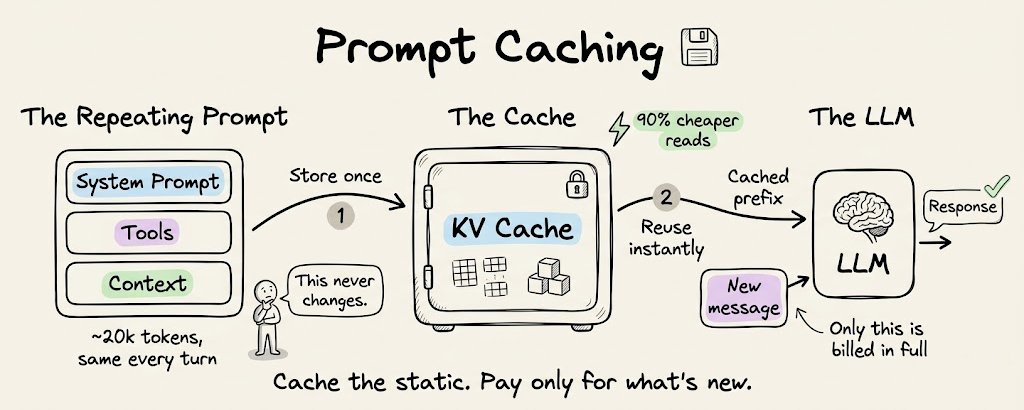
lets an AI service reuse processing of an unchanged beginning of a request. Avi Chawla's explanation focuses on why this matters for agents: successive requests often repeat instructions and earlier conversation content.
The condition is exact matching. As Chawla explains, the reusable portion is identified by the precise sequence from the start of the request, so changing even the order of earlier content forces it to be processed again at full price. Stable instructions, tool definitions and reference material therefore belong first, with the growing conversation after them. Caching saves work on repeated input; the model still generates each new reply. In his account of Anthropic's API, writing to the cache costs more than ordinary input, so savings depend on how often later requests actually reuse it.
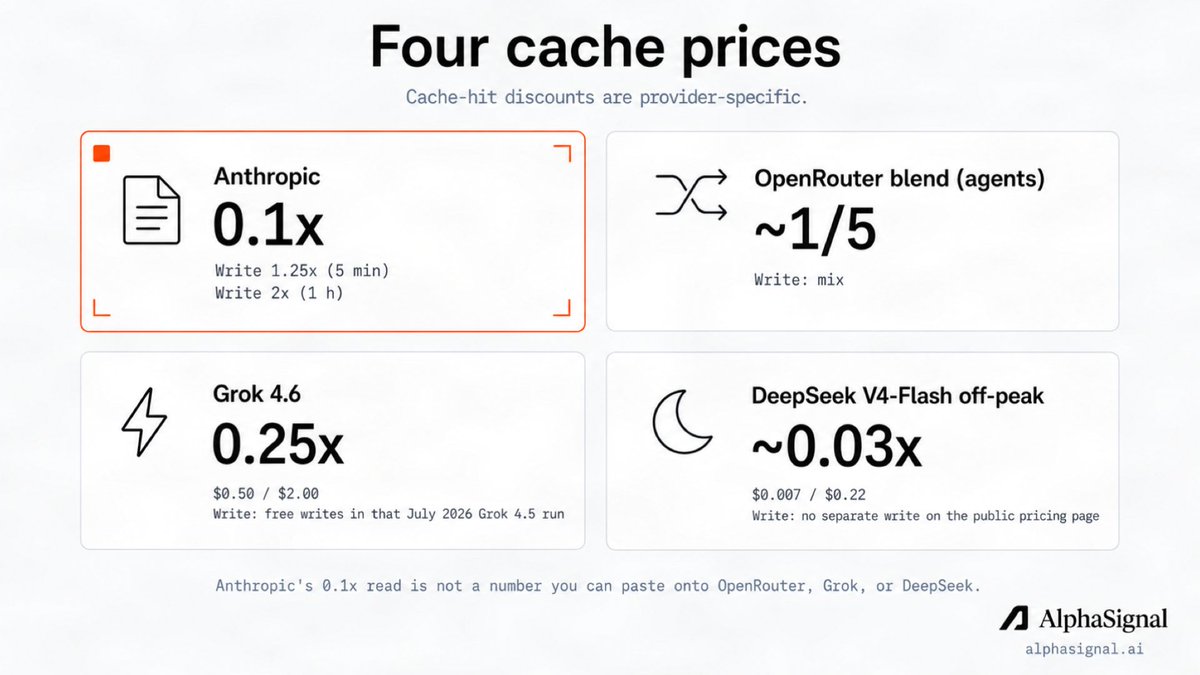
- The price sheet is what makes the design decision: reading a cached costs 0.1x the base input price, writing the cache costs 1.25x, and an extended one-hour cache costs 2.0x. A write pays for itself on the very next hit.
- Caching only works on a prefix because a token's Key and Value vectors depend solely on the tokens before it and never change once computed. The cache is keyed by a hash of the exact sequence, so one edited word near the top invalidates everything after it.
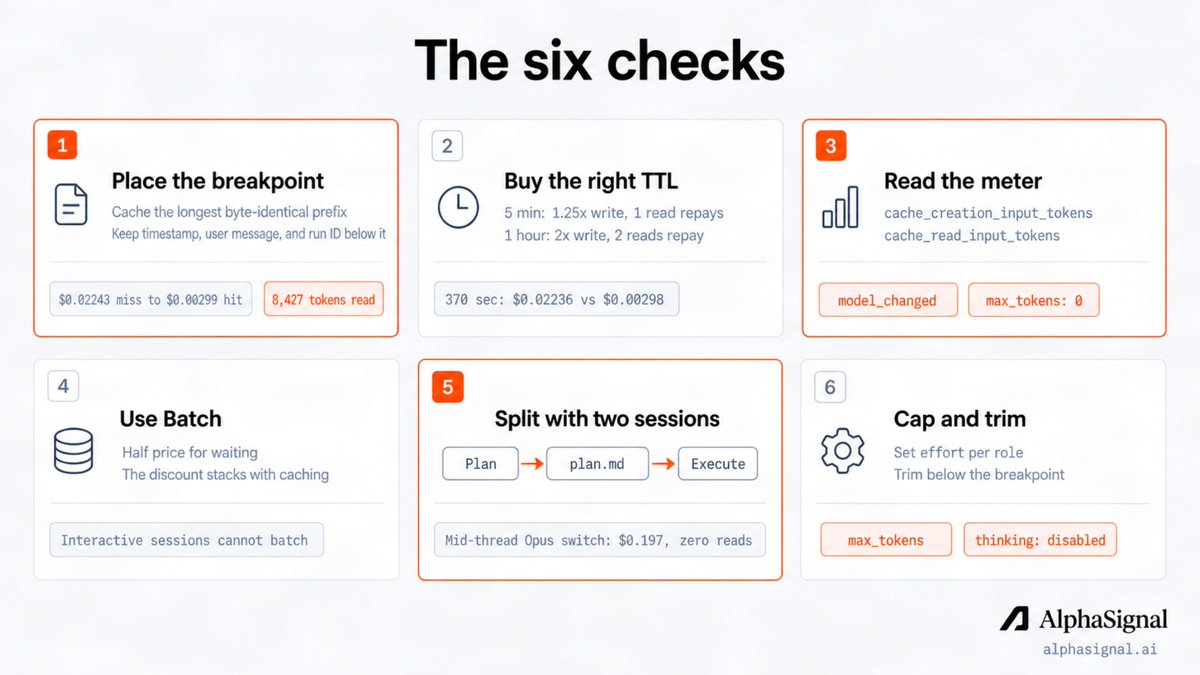
- That mechanic dictates layout: system instructions, tool definitions and project go first and stay byte-identical; user turns, tool results and terminal output accumulate at the end where they cannot break the match.
- Two habits keep the hit rate high: every cache read resets the expiry, so steady activity keeps it warm, and handing sub-agents a summarized brief instead of raw tool output keeps the changing tail from ballooning.
- prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
“A system prompt with 20,000 tokens running over 50 turns means 1 million tokens of redundant computation billed at full price, producing zero new value.”
“Cache reads cost 0.1x the base input price, which is a 90% discount on every cached token.”
“Claude Code is built entirely around one objective: keep the cache hot.”
“This drops computational complexity from O(n²) per generated token to O(n).”

Checking sign-in…
Loading comments…