Reiner Pope – The math behind how LLMs are trained and served
- Source
- dwarkesh.com
- Author
- Dwarkesh Patel
- Date
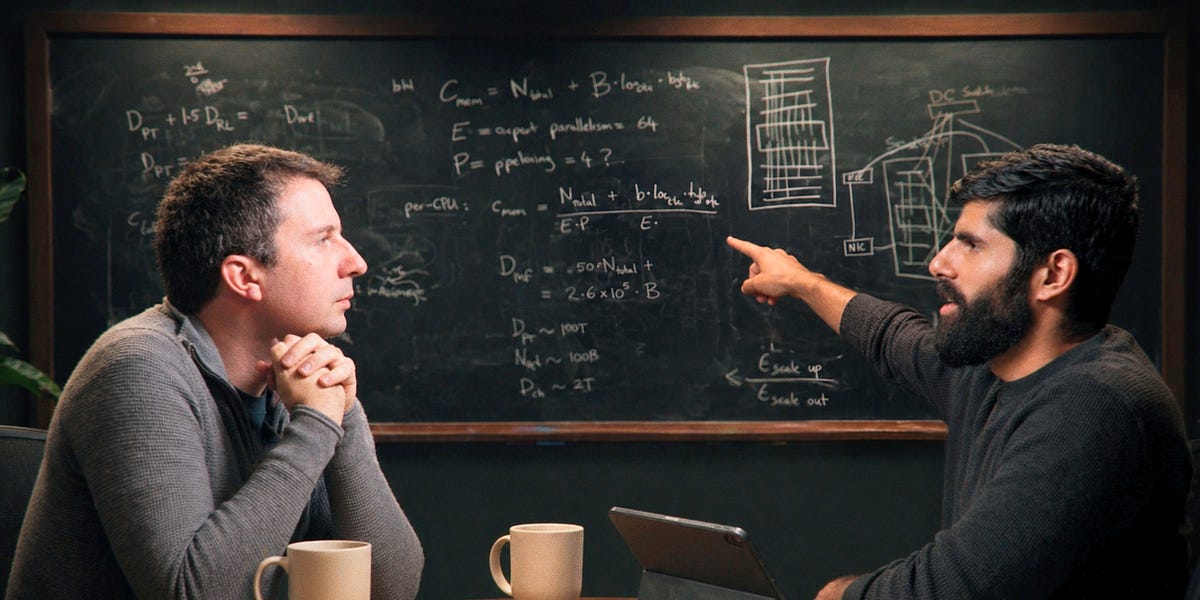
You get a first-principles derivation of training and serving economics from someone who has worked across chip design, compilers, and TPU architecture — including how to infer what frontier labs are doing from a handful of equations and public API prices.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
“if you do not batch together many users, the cost and the economics you get can be a thousand times worse than if you do batch many users together”
Reiner Pope
“Pipelining totally solves the capacity problem, but scale-up size helps solve the bandwidth problem.”
Reiner Pope
“I mean, you are incentivized to price close to your costs because otherwise someone could scoop you.”
Reiner Pope
“This is why you should just approximate everywhere, because there are big error bars on this. But it’s kind of empowering to just set A equal to B and figure it out.”
Reiner Pope
“The empirical result is that the context lengths haven’t been increasing that much. I think it’s because there is no solution to the memory wall here.”
Reiner Pope
- 00:00:00How batch size affects token cost and speed
- 00:32:09How MoE models are laid out across GPU racks
- 00:47:12How pipeline parallelism spreads model layers across racks
- 01:03:37Why Ilya said pipelining is not wise
- 01:18:59Models may be 100x over-trained beyond Chinchilla-optimal
- 01:33:02Deducing long context memory costs from API pricing
- 02:04:02Convergent evolution between neural nets and cryptography


Checking sign-in…
Loading comments…