Task-Specific LLM Evals that Do & Don't Work
- Source
- eugeneyan.com
- Author
- Eugene Yan
- Date
Context
A single accuracy score does not show whether an extraction system misses important information or returns incorrect information. Eugene Yan's task-specific evaluation guide separates these questions: recall measures how much of the required information was found, while precision measures how much of the returned information was correct.
For a checker that produces a score, the cutoff for flagging a case determines which mistakes it makes. Examining precision and recall at the intended cutoff reveals the balance between missed problems and false alarms. An aggregate score across many cutoffs cannot, by itself, tell a team whether that operating choice suits its task.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
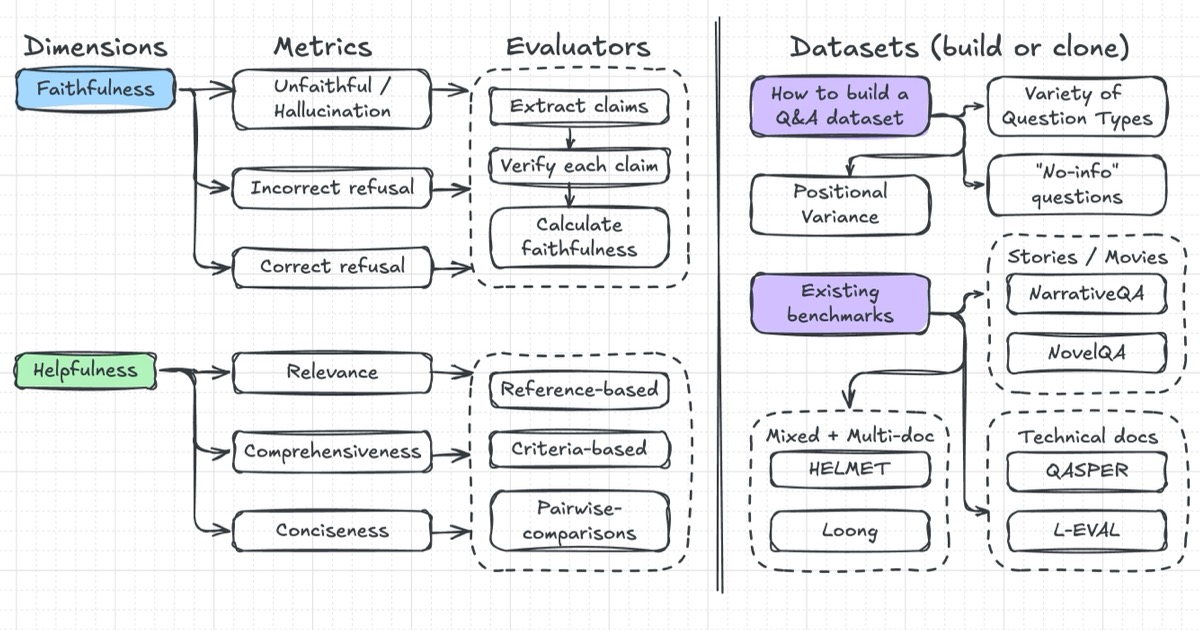
“If you’ve ran off-the-shelf evals for your tasks, you may have found that most don’t work. They barely correlate with application-specific performance and aren’t discriminative enough to use in production.”
Eugene Yan
“IMHO, accuracy is too coarse a metric to be useful. We’d need to separate it into recall and precision at minimum, ideally across thresholds.”
Eugene Yan
“I seldom see grammatical errors or incoherent text from a decent LLM (maybe 1 in 10k). Thus, no need to invest in evaluating fluency and coherence.”
Eugene Yan
“it shows how a little finetuning on open-source, permissive-use data can help improve ROC-AUC from 0.56 (which is practically random) to 0.85!”
Eugene Yan
“While it’s the most used translation eval, it’s also bottom of the leaderboard at WMT22 and WMT23”
Eugene Yan
Checking sign-in…
Loading comments…