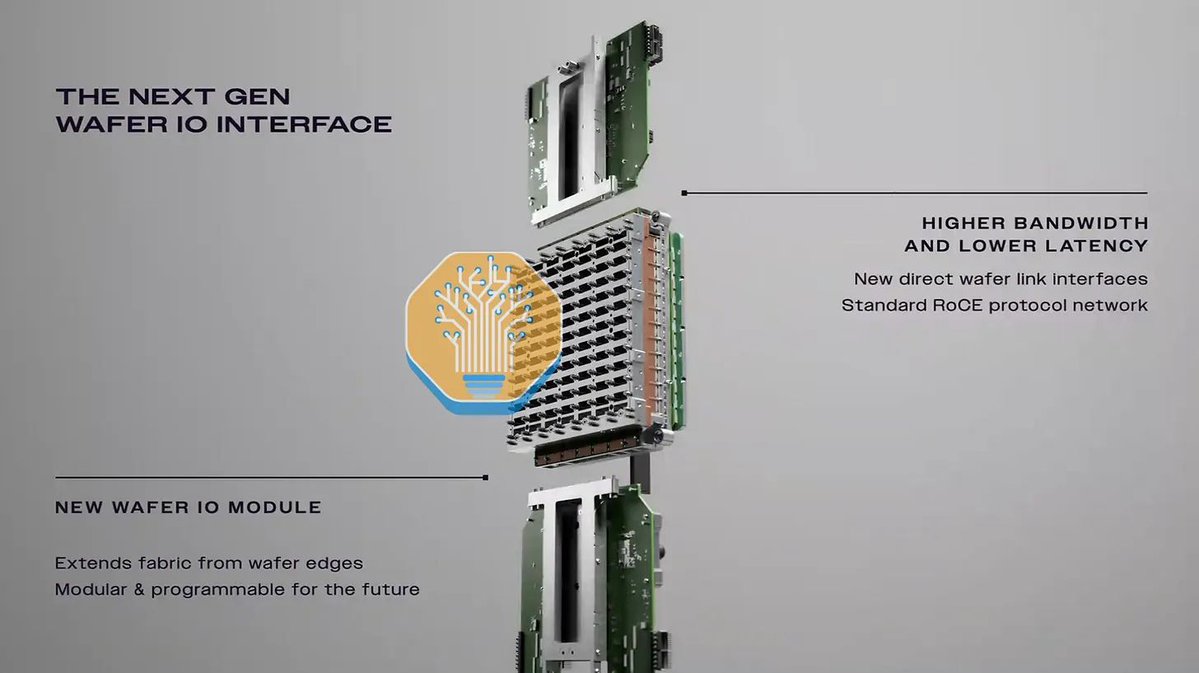
Cerebras's enormous chip makes room for a type of fast memory that stores relatively little data per unit of silicon. In the interview, the chipmaker's chief executive explains that using an entire wafer provides more area for that memory. His argument is that generating AI responses requires moving substantial amounts of information between memory and computation, so faster access can reduce waiting. The design targets that data-movement bottleneck; its size serves a specific memory strategy.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.