Introducing Claude Haiku 5.5
- Source
- simonwillison.net
- Date
Context
Simon Willison argues that Anthropic's Claude Haiku 5.5 is as cheap as OpenAI's GPT-6 Luna only for short prompts. In his October 7 post, he notes Haiku 5.5 costs $0.10 per million input and $0.50 per million output tokens up to 100,000 tokens, the same as Luna and a tenth of Haiku 4.5's $1 and $5. Above 100,000 tokens Haiku's price rises fivefold, while Luna's rises only to $0.20 and $0.75 at 272,000.
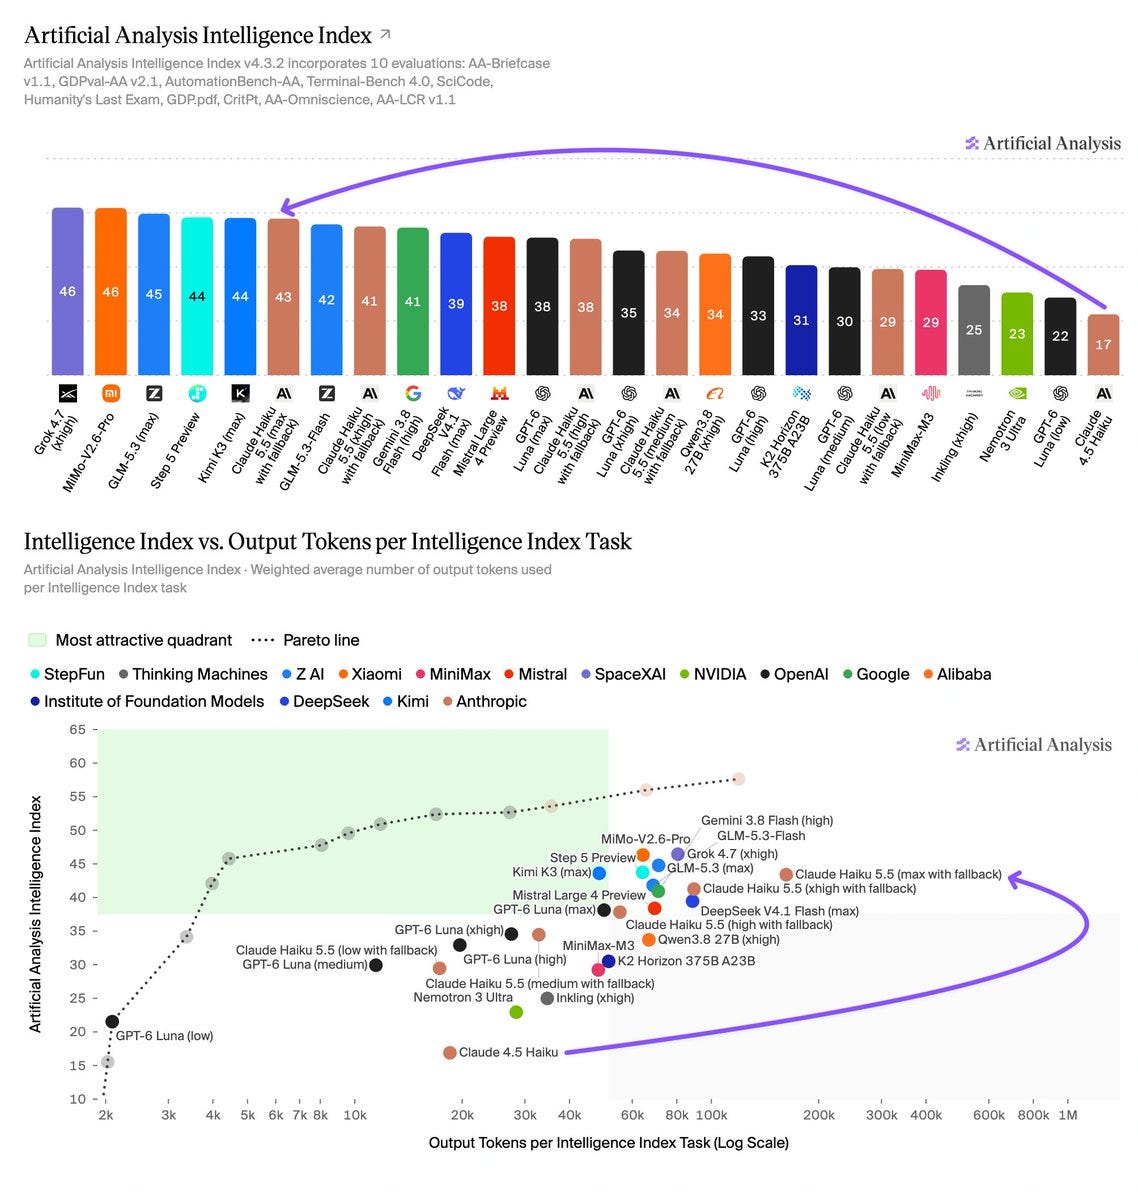
He also found that Haiku 5.5 uses a new tokenizer, the step that splits text into the pieces models are billed on. For one long prompt, his token counter showed about 1.25 times as many tokens as Haiku 4.5, a hidden price increase that offsets part of the cut. Anthropic's own page likewise says the updated tokenizer uses slightly more tokens per task, and lists prices 90 percent lower than Haiku 4.5 up to 100,000 tokens and 50 percent lower above that.
His takeaway is that within 100,000 tokens Haiku matches Luna on price and reports higher scores, while above that Luna looks like a much better deal. His pelican-drawing tests are informal, costing from under a tenth of a cent at low effort to about 3.4 cents at max effort, and are not a quality benchmark. Background on the earlier model is in Intel coverage of Haiku 4.5.
- Above 100,000 tokens Haiku 5.5's price rises 5x to $0.50/$2.50 per million, while GPT-6 Luna only steps up at 272,000 tokens, to $0.20/$0.75, so Simon Willison judges Luna the much better deal for long- work.
- Haiku 5.5 cannot disable reasoning and defaults to medium effort. In Willison's pelican SVG test, low effort cost 0.0936 cents in 7 seconds, while max effort took 5 minutes 9 seconds and still cost only 3.3826 cents.
- Anthropic is adding a monthly API credit for Max and Team subscribers: $100 for Max 5x, $200 for Max 20x and up to $500 pooled for Team, claimed under Settings, Billing. Willison notes the credit matches the subscription's own cost.
- Anthropic now lets API users disable auto-reload so requests stop when the balance runs out, which Willison says avoids billing surprises. He still rates OpenAI's Codex subscription, usable for personal API calls, the better deal for heavy API users.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…