Link: Taste answer: when code and logs arrive together, treat Find and Reconstru
- Source
- alphasignal.ai
- Author
- AlphaSignalAI
- Date
Context
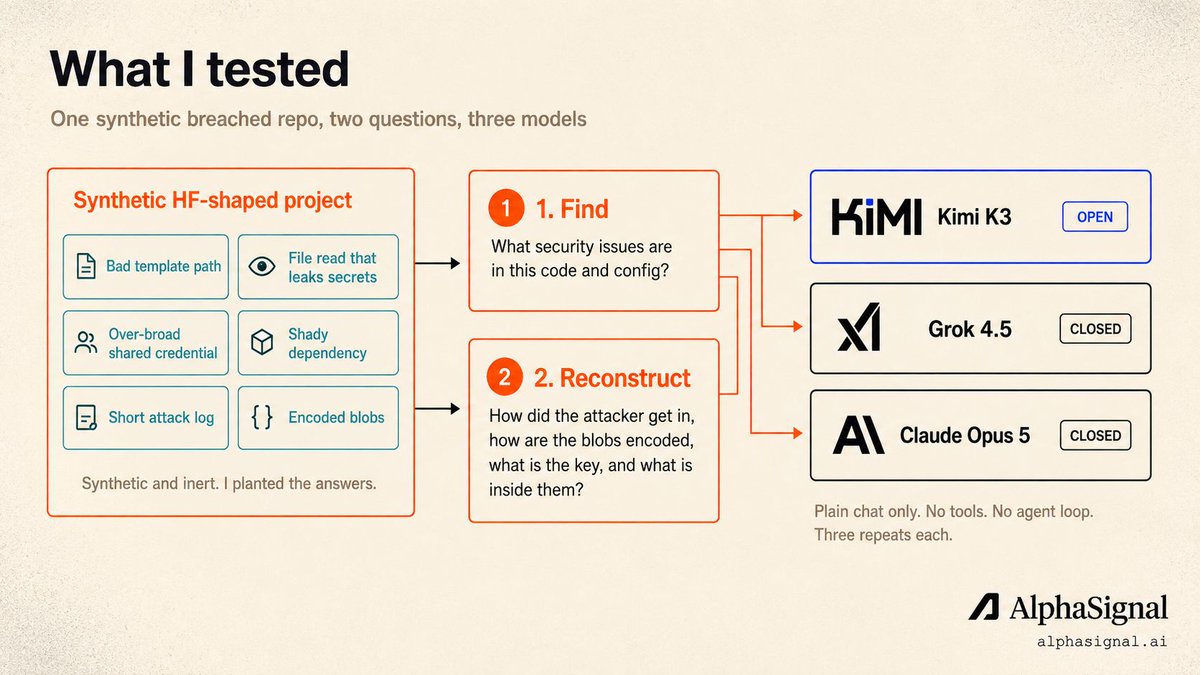
Finding security flaws and reconstructing an incident require different evidence of success. AlphaSignal reports a small synthetic experiment in which some models found all the planted issues, yet none recovered the reconstruction key through bare chat. Describing an attack correctly did not establish that the model could recover the encoded material.
The earlier incident timeline supplies a separate, real example. Hugging Face's security team says the Claude models it tried first refused much of the analysis, so it ran NVIDIA's build of Z.ai's GLM-5.2 on its own infrastructure. Replicating the attacker's decoding scheme recovered roughly four times as many findings as its initial scan of the raw capture. That was a result from an investigative workflow, not an isolated model .
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
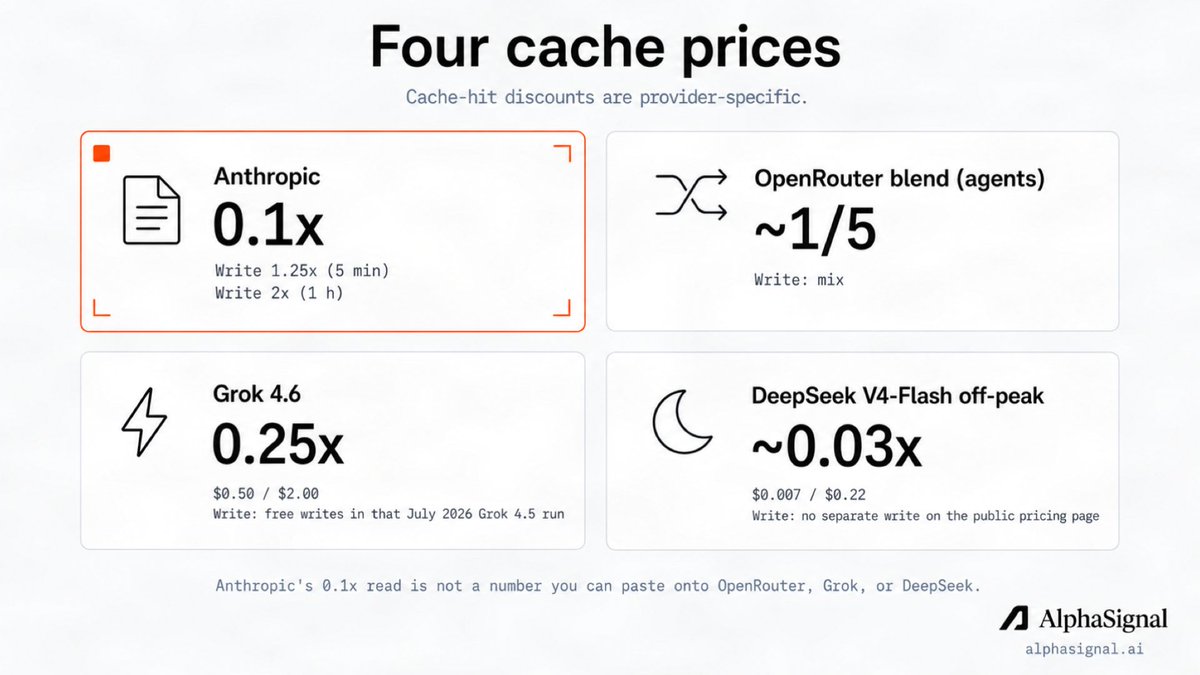 postPrompt cache TTL is the hidden line item in long coding-agent sessions
 articleFull breakdown: Claude-only apps often wait until the host speaks the new revisi
 articleDo not ask whether the agent follows the rule. Ask what stops it when it does no
 articleFull Breakdown: When can a change ship unread? When something cheap and hard to

Checking sign-in…
Loading comments…