LLM Research Papers: The 2025 List
- Source
- magazine.sebastianraschka.com
- Author
- Sebastian Raschka, PhD
- Date
Context
Research on better reasoning can target either how a model learns or how it is used after training. Sebastian Raschka's 2025 paper collection makes that distinction part of its organization, separating reasoning-model training from -time strategies and .
This helps a reader choose a relevant starting point. Training papers concern changing the model through learning; inference-time papers concern improving answers during use without retraining. Evaluation papers address how to assess those answers. The collection is a categorized reading guide, so those headings help locate a research question without implying that every listed method has been validated by the curator.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
“Also, as LLM research continues to be shared at a rapid pace, I have decided to break the list into bi-yearly updates.”
“This year, my list is very reasoning model-heavy. So, I decided to subdivide it into 3 categories: Training, inference-time scaling, and more general understanding/evaluation.”
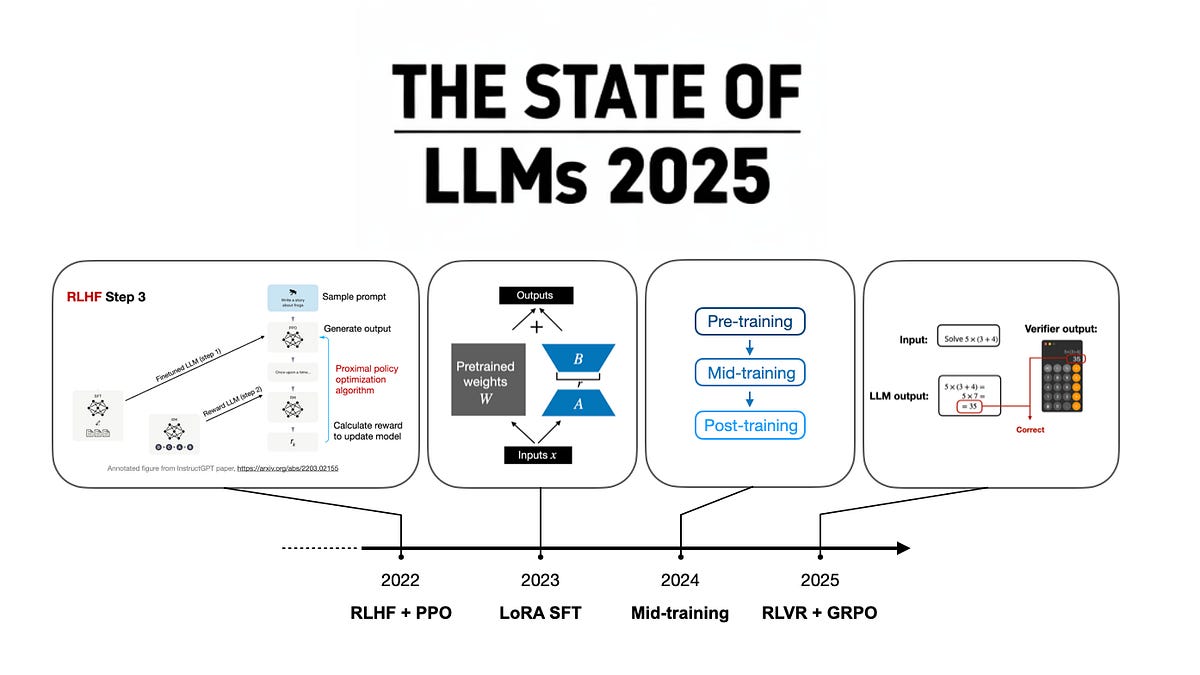
“As you may see, much of the recent progress has centered around reinforcement learning (with verifiable rewards), which I covered in more detail in a previous article.”

Checking sign-in…
Loading comments…