Wafer says it beat Cerebras on latency for YC's AI Office Hours
- Source
- x.com
- Date
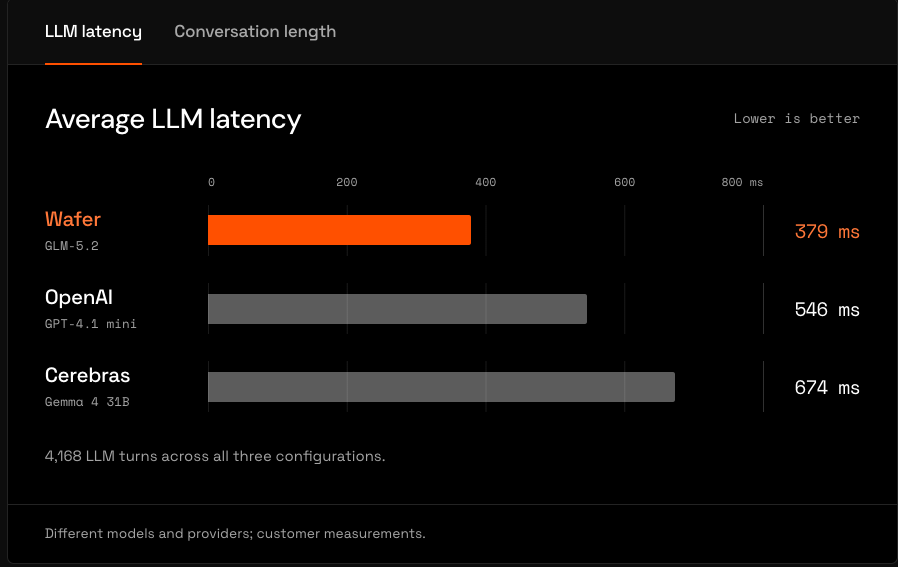
Wafer says it served Y Combinator's AI Office Hours, where users get startup advice from AI versions of YC partners, faster than Cerebras did. By Wafer's account, GLM-5.2 on its endpoint averaged 379 milliseconds of latency against 674 milliseconds for Gemma 4 31B on Cerebras, a 44% cut with a much larger model. YC had tested lightweight Gemma and OpenAI models before moving to a dedicated Wafer endpoint. Wafer says its own agents tuned the serving setup to YC's request rate, cache usage and prompt and response lengths, and that users spent 2.5 more minutes talking on Wafer than with other providers. These are vendor figures from a customer story, not an independent benchmark. The useful point for builders is that serving tuned to a specific workload can outweigh raw model size when conversational latency drives engagement.

Wafer beat Cerebras on latency for @ycombinator's AI Office Hours. GLM-5.2 on Wafer averaged 379 ms versus 674 ms for Gemma 4 31B on Cerebras. that's 44% lower latency with a much larger model. YC wanted people to get startup advice from AI versions of its partners at conversational speed. after testing lightweight Gemma and OpenAI models, they moved to a dedicated Wafer endpoint. Wafer agents tuned the serving setup for YC’s request rate, cache usage, and prompt and response lengths. users spent 2.5 minutes longer talking to its AI partners on Wafer compared to other providers. read how YC built the experience and landed on Wafer 🧵 link in thread
@ycombinator Read YC's Story: https://t.co/ruwnPCng5w
Context
Y Combinator wanted people to get startup advice from AI versions of its partners at conversational speed. According to Wafer in its post, YC tested lightweight Gemma and OpenAI models before moving to a dedicated Wafer endpoint, and Wafer agents tuned the serving setup for YC's request rate, cache usage, and prompt and response lengths.
Wafer reports that GLM-5.2 on Wafer averaged 379 milliseconds against 674 milliseconds for Gemma 4 31B on Cerebras, which it calls 44% lower latency with a much larger model. Wafer also says users spent 2.5 minutes longer talking to the AI partners on Wafer than on other providers. The post does not say the latency difference caused the longer sessions, and all figures are Wafer's own.

Checking sign-in…
Loading comments…