Beyond LoRA: Can you beat the most popular fine-tuning technique?
Source
huggingface.co
Date
Context
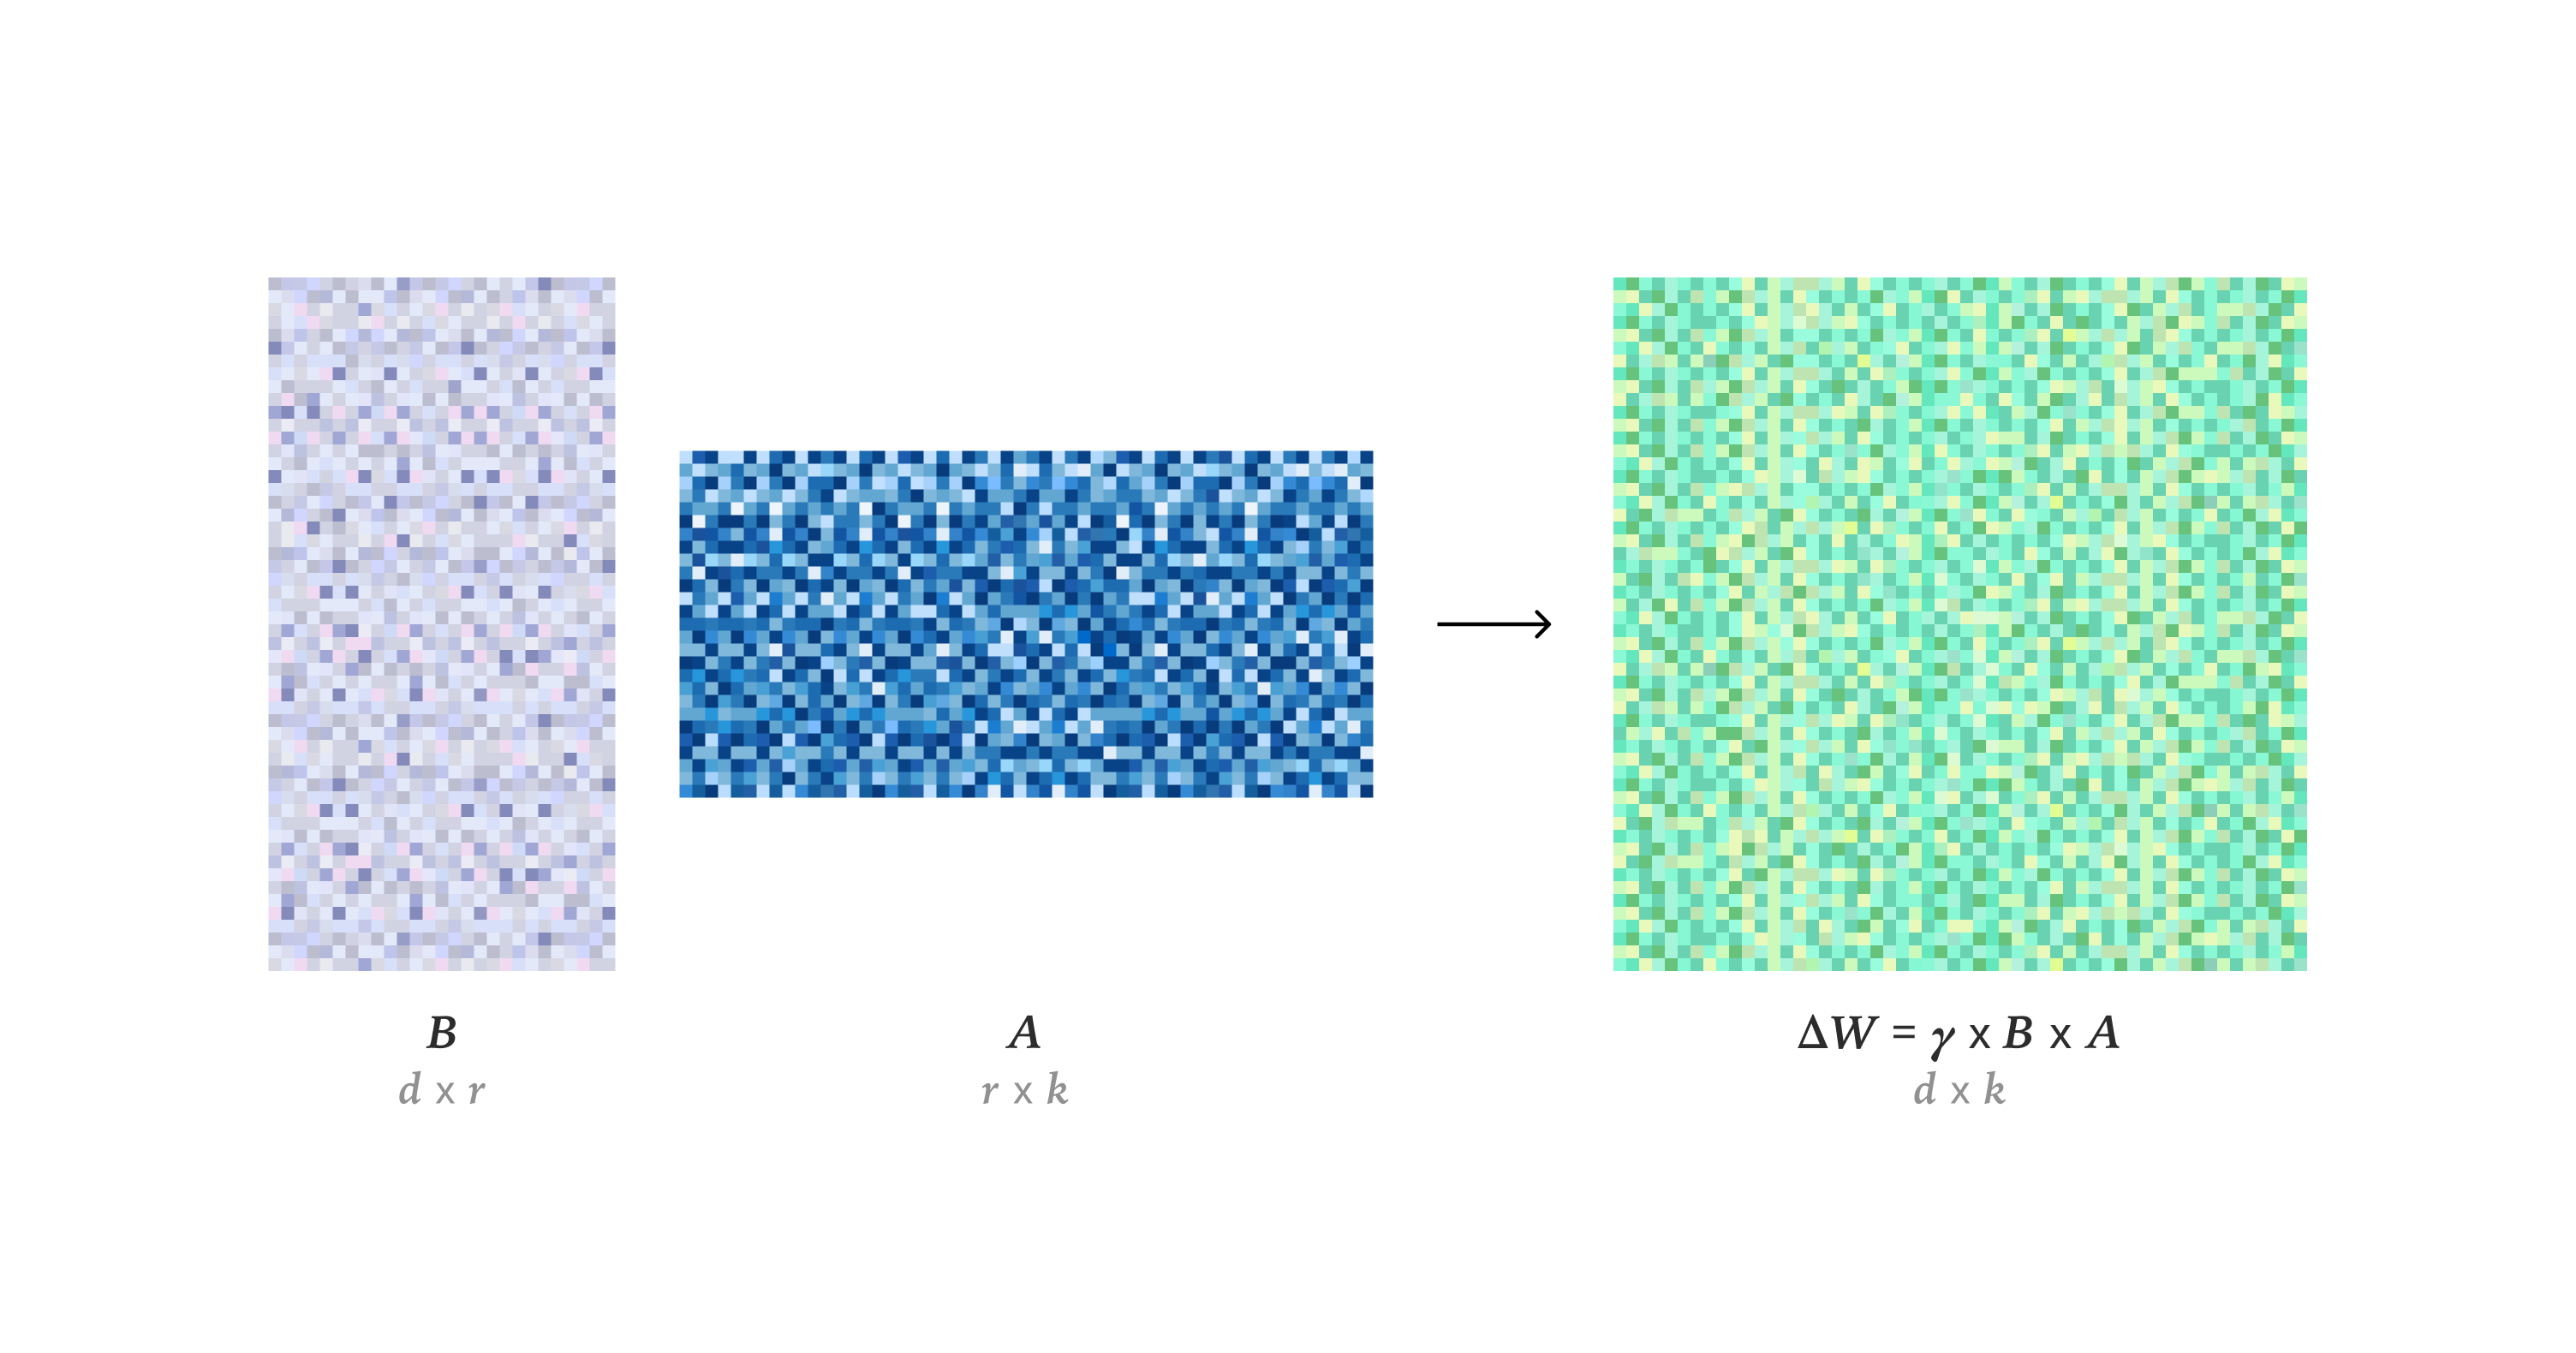
LoRAA cheap way to fine-tune a model by training a small add-on layer instead of changing all of the model's weights.Full definition → adapts a model by training a small set of added parameters while leaving its original weights fixed. A comparison from the PEFT library's developers shows why it need not be the automatic choice. In their image-personalization test, which taught a model a particular cat plush toy, OFT achieved a higher image-similarity score while using less peak GPU memory: 9.01 GB versus LoRA's 9.97 GB.
That is a useful alternative for the tested task, rather than a universal winner. The authors acknowledge incomplete tuning across methods, and their math benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → showed different trade-offs. Choosing a method requires comparing the accuracy, memory, and deployment requirements relevant to the intended task.
Terms in this piece · Glossary
LoRA — A cheap way to fine-tune a model by training a small add-on layer instead of changing all of the model's weights.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.