KellyBench
gr.inc- Category
- AI Tools
- Rank
- No. 3336Tools index
Previous survey · No. 3218 ·
- Listed in
- Find AI benchmarks
- Pricing
- Open Source
- Type
- TOOL
- Use case
- Model & Agent Evaluation
- Builder
- @BradAllenNFL
- Date
About
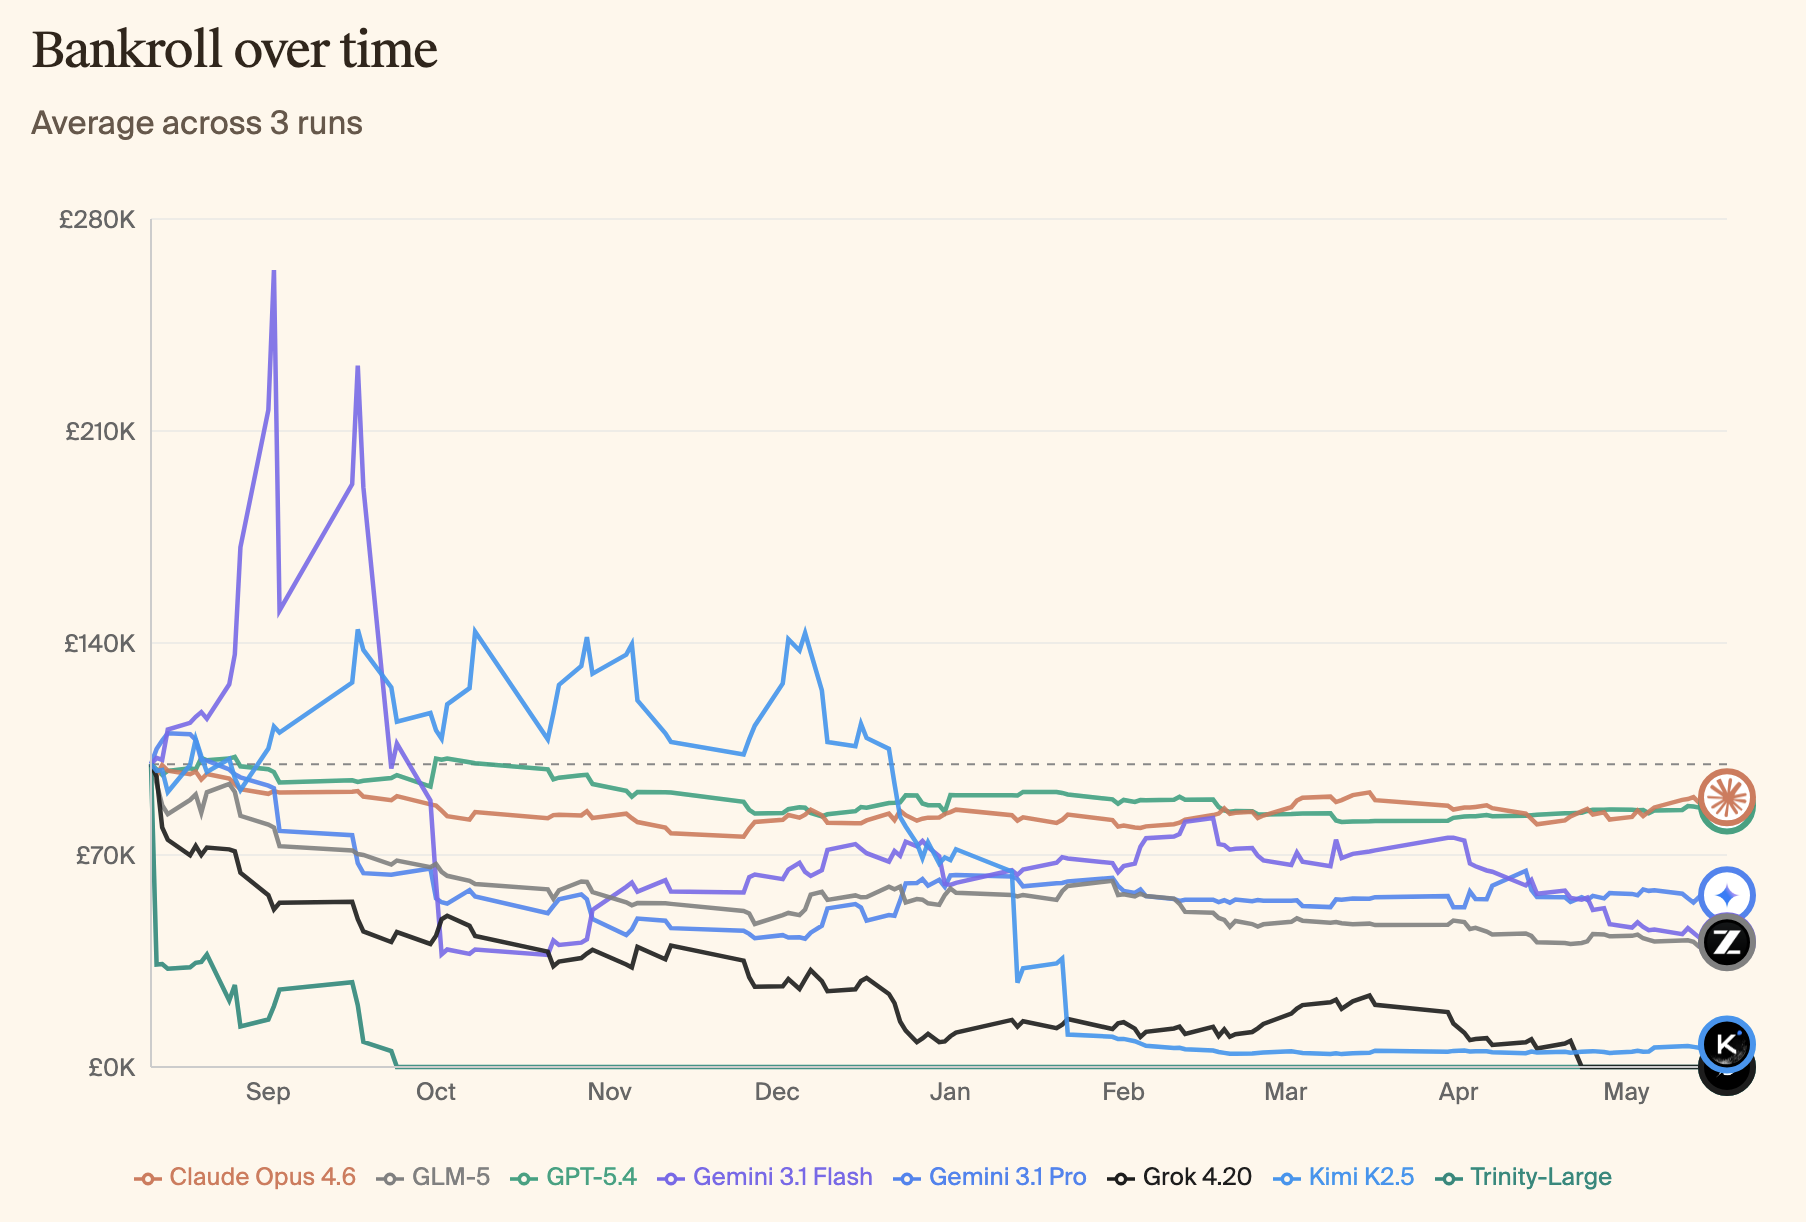
A long-horizon evaluation environment that tests language models' ability to develop quantitative betting strategies for a full Premier League season. All tested frontier models lost money, revealing limitations in sequential decision-making under uncertainty.
What it does
The General Reasoning site says KellyBench is a long-horizon environment for testing how AI agents make sequential decisions in sports betting markets. Agents work through a simulated Premier League season using historical data, building models, sizing bets and managing risk. The site says it is offered as an open-access API endpoint on OpenReward.
Stated on the product site
- Stated purpose
- Evaluates sequential decision-making in sports betting markets
- Setting
- A simulated betting market for an English Premier League season
- Agent inputs
- Historical statistics, lineups, results and public odds
- Access
- Open-access endpoint on OpenReward
- Process measure
- An expert-built rubric scores strategy sophistication alongside returns
- Rubric disclosure
- Rubric is only partly published
Not stated on the site
- The page does not explain what ORS, the framework KellyBench is said to be built on, is.
- The page does not show the access terms, limits or cost of the OpenReward endpoint.
- The page does not say whether the environment can be downloaded and run locally.
- The full sophistication rubric is not on the page; the site says it is withheld to extend the benchmark's life.
- The page does not say whether seasons other than the one described are planned.
Written from the product site at gr.inc.
What it can do
Simulate a full Premier League season for betting evaluation
Season parameters and betting constraints → Complete season simulation with match outcomes
Test language model betting strategies
Language model and betting parameters → Performance metrics and profit/loss results
Generate quantitative betting strategies
Match data and team statistics → Betting recommendations with stake amounts
Evaluate sequential decision-making performance
Model decisions over time series → Decision quality analysis and consistency metrics
Track model performance under uncertainty
Model predictions and actual outcomes → Uncertainty handling assessment and accuracy scores
Benchmark frontier language models
Multiple language models → Comparative performance rankings and analysis
Tags
Media
Comments (0)
No comments yet
Editorially curated, with community endorsements as a secondary signal. Corrections welcome.