Cheap agents are closing the CUDA portability gap
- Source
- x.com
- Date

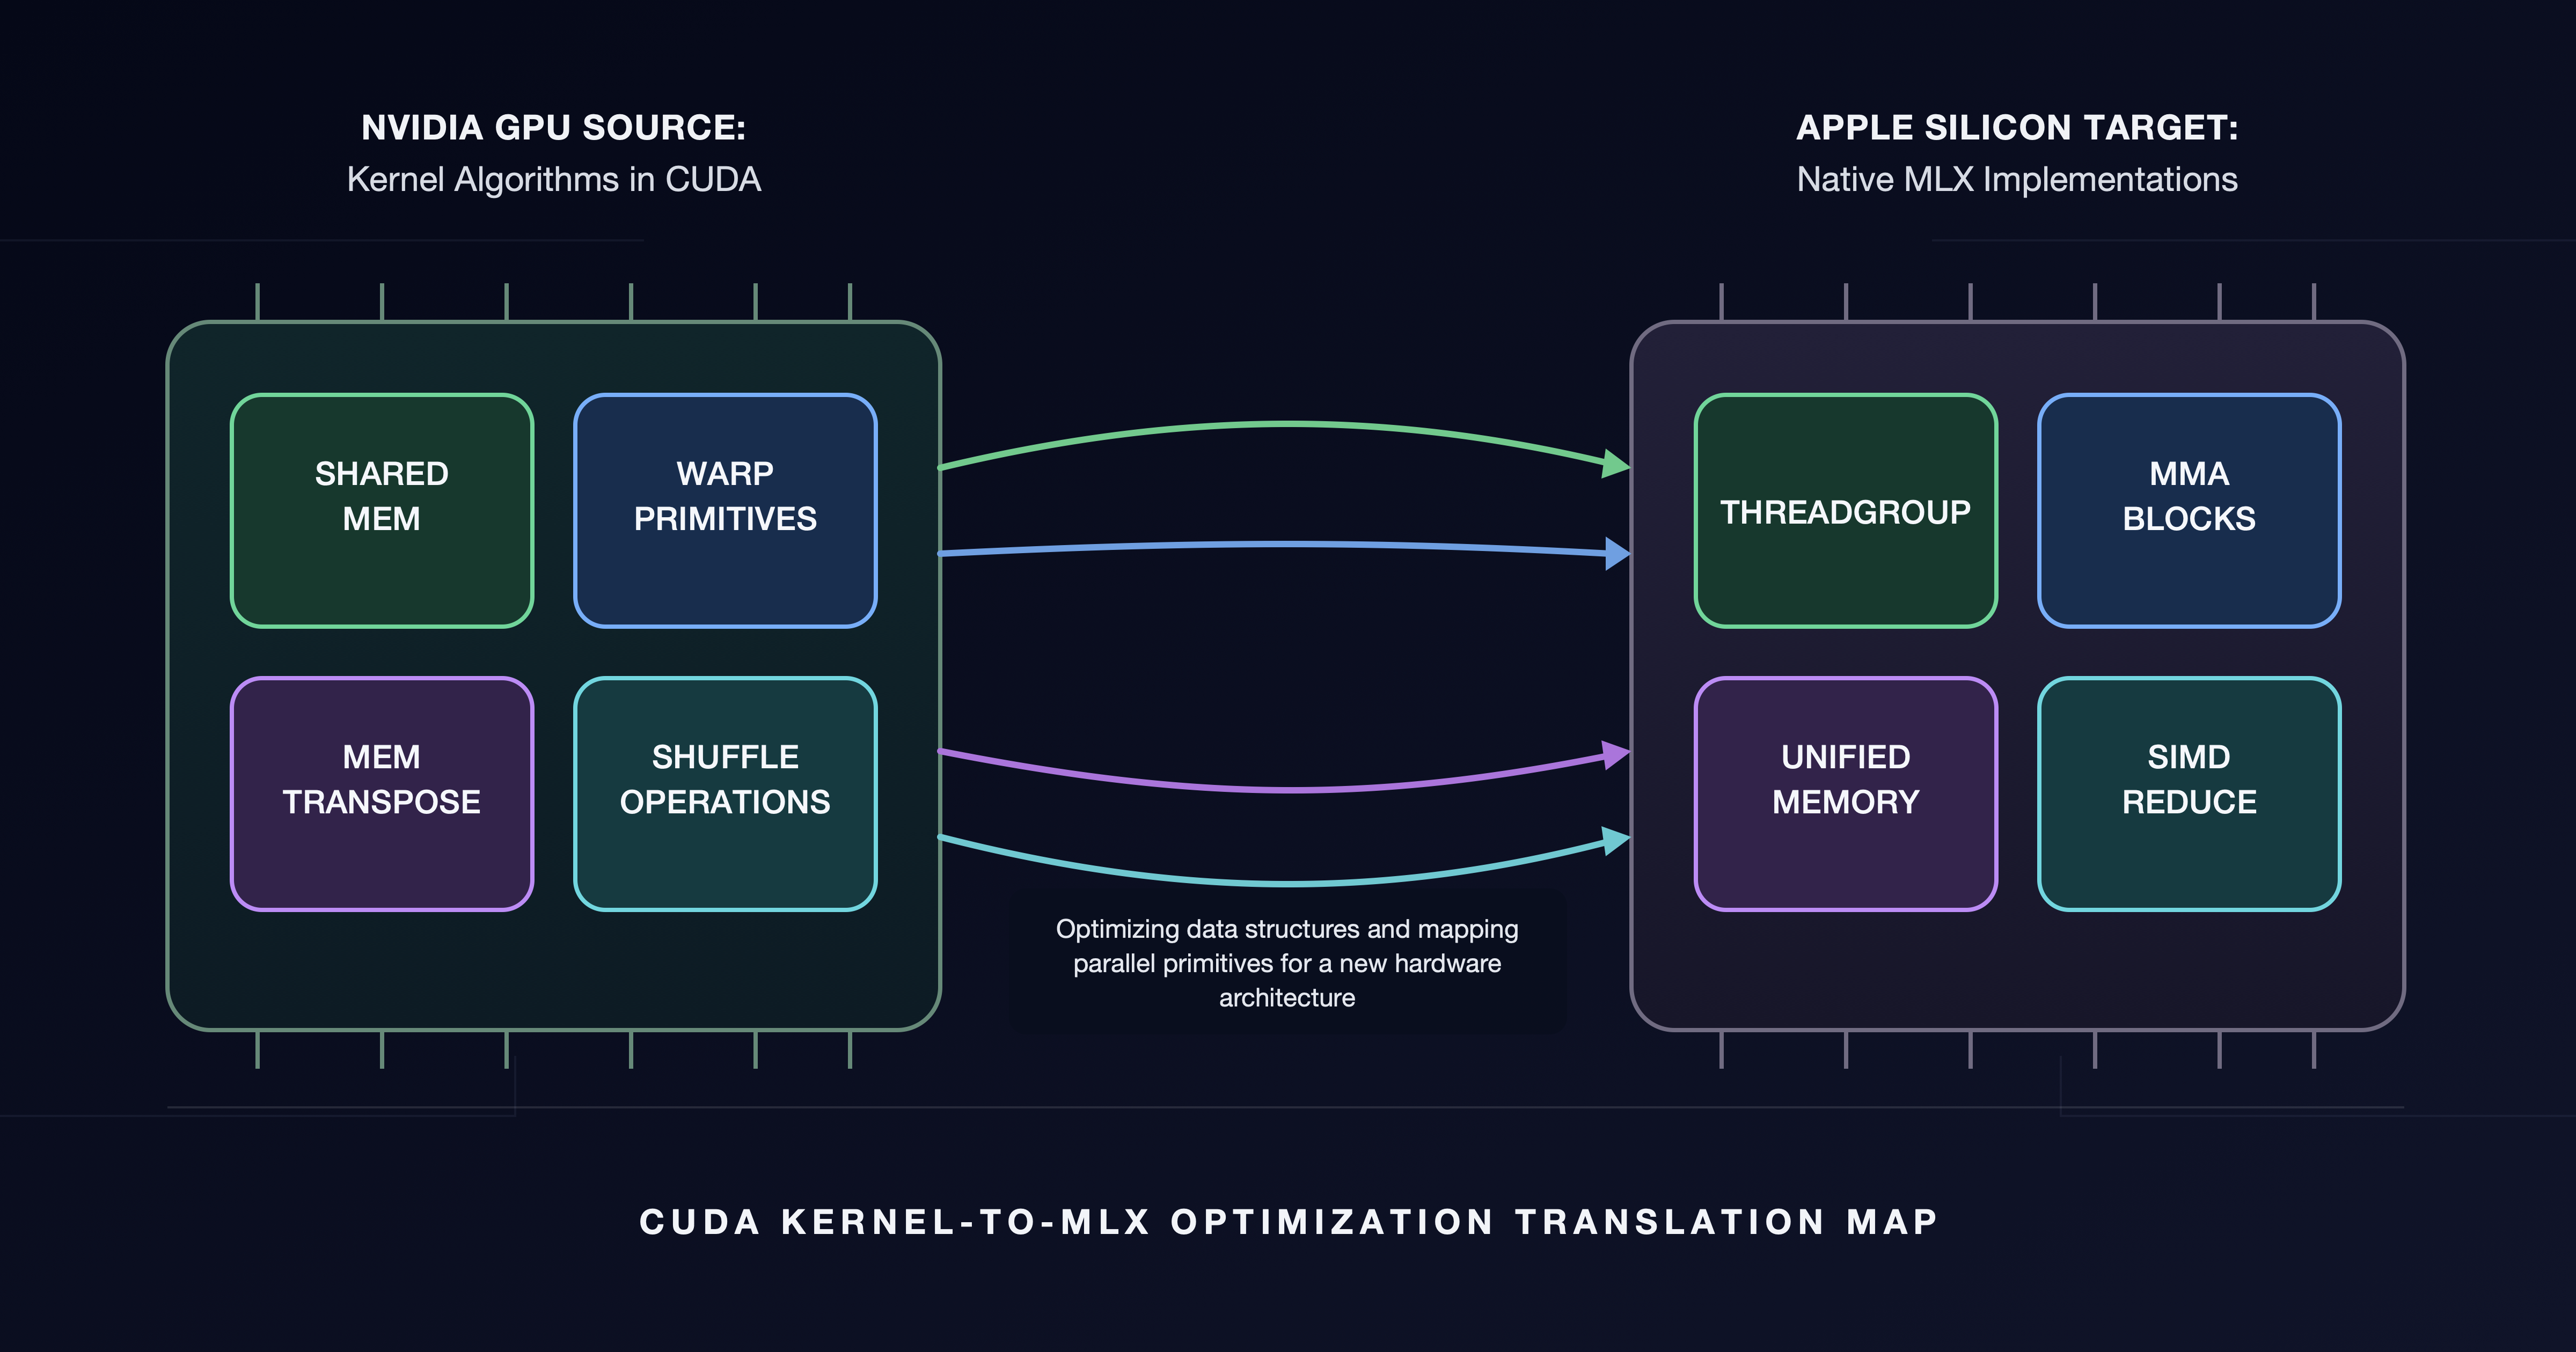
A year ago the consensus was everyone would be using one or two frontier models, running entirely on NVIDIA GPUs. The reality now is we have hundreds of models each with different cost/speed/intelligence tradeoffs for different tasks, running on dozens of different local / data center chips (even older hardware). Ironically the frontier models that were trained on NVIDIA GPUs have made it faster and easier to port kernels from CUDA to other hardware targets (AMD, Apple Silicon, Intel, ...). There are people with no experience writing kernels using relatively cheap AI agents to implement efficient kernels for Apple Silicon, synthesizing all the tricks from existing CUDA implementations that were meticulously hand written by experts. Funnily enough, since the performance of these kernels can be quickly and objectively evaluated by an agent by actually running the kernel on the hardware, it's an unreasonably tractable task for agents. They can continuously improve them in a fairly simple autoresearch loop. Kernel interoperability is solved ("The unreasonable effectiveness of AI agents"). The next continuation of this trend is to have millions of small, specialized models for…

Context
Alex Cheema argues that hardware-specific kernels are promising targets for coding agents because the agents can run their proposals and use measured performance to guide another attempt. Kernels are low-level programs that perform computations on a processor; transferring their optimizations between hardware families requires adapting to different constraints.
The related K-Search translation work provides a concrete example. Its research account combines hardware-specific translation rules with a loop that generates, compiles and benchmarks candidates, feeding measurements into the next round. This supports a narrower conclusion than universal portability: agents can search for suitable implementations when they have explicit hardware knowledge and access to the target machine for .
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference

Checking sign-in…
Loading comments…