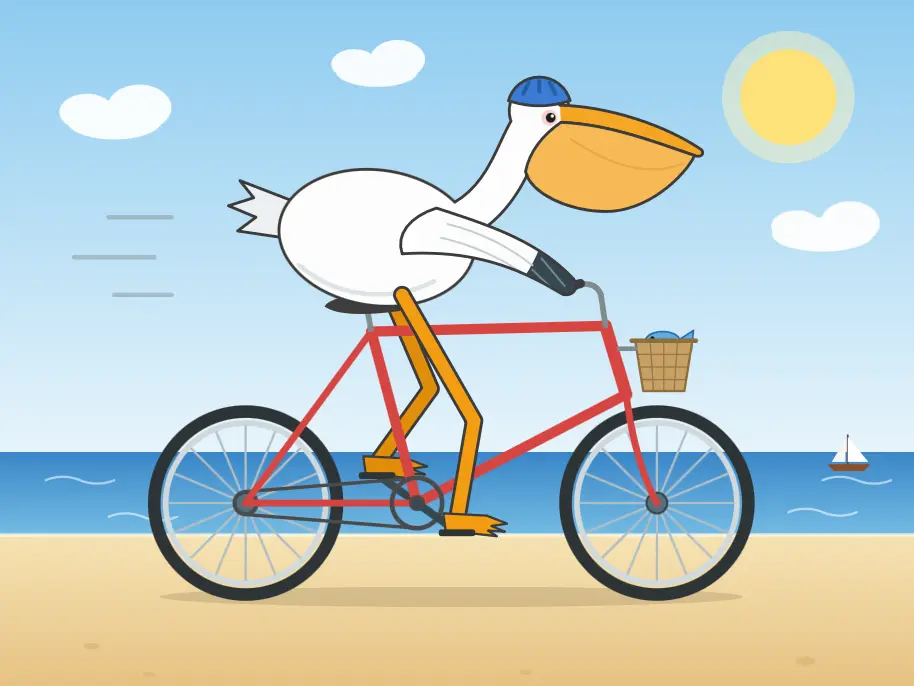
Claude Fable 5.1 made me a really nice animated pelican
Source
simonwillison.net
Date
Context
Simon Willison's pelican experiment shows how strongly a reasoning setting can change the cost of one task. Willison asked Anthropic's Fable 5.1 to generate an SVG, a code-defined illustration, of a pelican riding a bicycle. At high effort the run took 29.6 seconds and cost about $0.13; at maximum effort it took 13 minutes 54 seconds and cost $3.30.
Willison called the maximum-effort result the best pelican from any Anthropic model that Willison had seen, but this was a comparison on one creative prompt. The evidence shows a substantial time-and-cost tradeoff within the model, without establishing a general improvement across coding tasks.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.