Mistral Large 4 targets agent workloads with benchmark claims
- Source
- x.com
- Date

Mistral Large 4 runs general-purpose agents that gather information and produce finished deliverables across complex workflows.

Gmail. Google Sheets. Slack. Salesforce. i.e. the four horsemen of Monday. On AutomationBench, Mistral Large 4 took on 657 business workflows across simulated workplace apps, all four included, finishing ahead of Kimi K3, MiMo-V2.6-Pro and DeepSeek V4 Pro.
The Ballon d'Or, legal division: On Harvey's Legal Agent Benchmark (LAB), Mistral Large 4 is the #1 oss model.

Context
Mistral AI is promoting Mistral Large 4, a it describes as running general-purpose agents that gather information and produce finished deliverables across complex workflows. In its launch thread, the company says that on AutomationBench, which it describes as 657 business workflows across simulated workplace apps including Gmail, Google Sheets, Slack and Salesforce, Large 4 finished ahead of Kimi K3, MiMo-V2.6-Pro and DeepSeek V4 Pro. It also says Large 4 is the '#1 oss model' on Harvey's Legal .
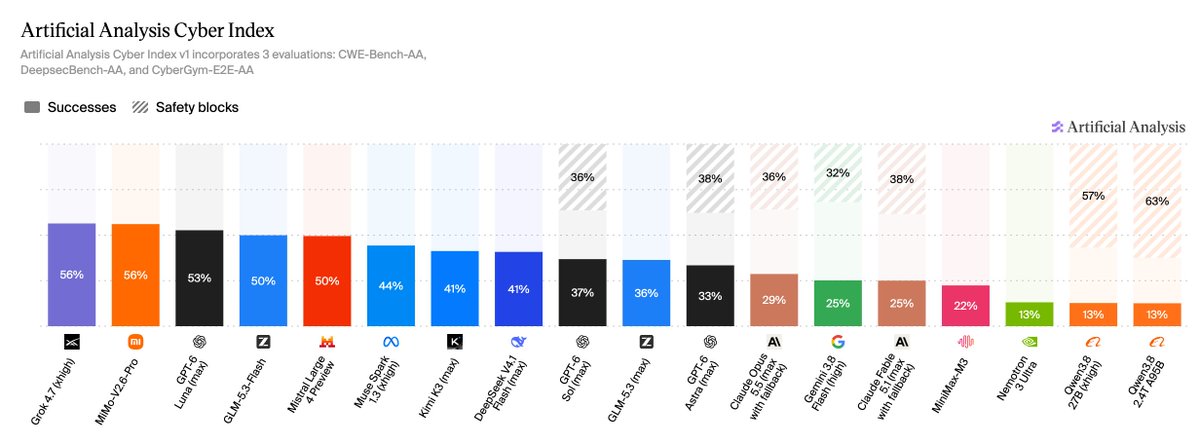
These are Mistral's own claims, and the thread's charts have no text description, so the scores and margins are not visible here. The text does not say which models were tested on the legal benchmark, or what 'oss' covers. Intel's item on Mistral's Large 4 announcement gives the launch , but the thread alone does not show how large the benchmark gaps are.
- Model — A computational system that uses learned patterns to produce an output from information supplied to it.
- Agent — A system in which a model repeatedly chooses operations, a harness carries them out, and the results return to the model to inform its next choice.
- Benchmark — A fixed set of tasks with a stated way of scoring them, used to compare models or setups.
- Context and context window — Context is the information available for a generation; the context window is the capacity available to hold it.
Checking sign-in…
Loading comments…