← All IntelClip / AI Tools
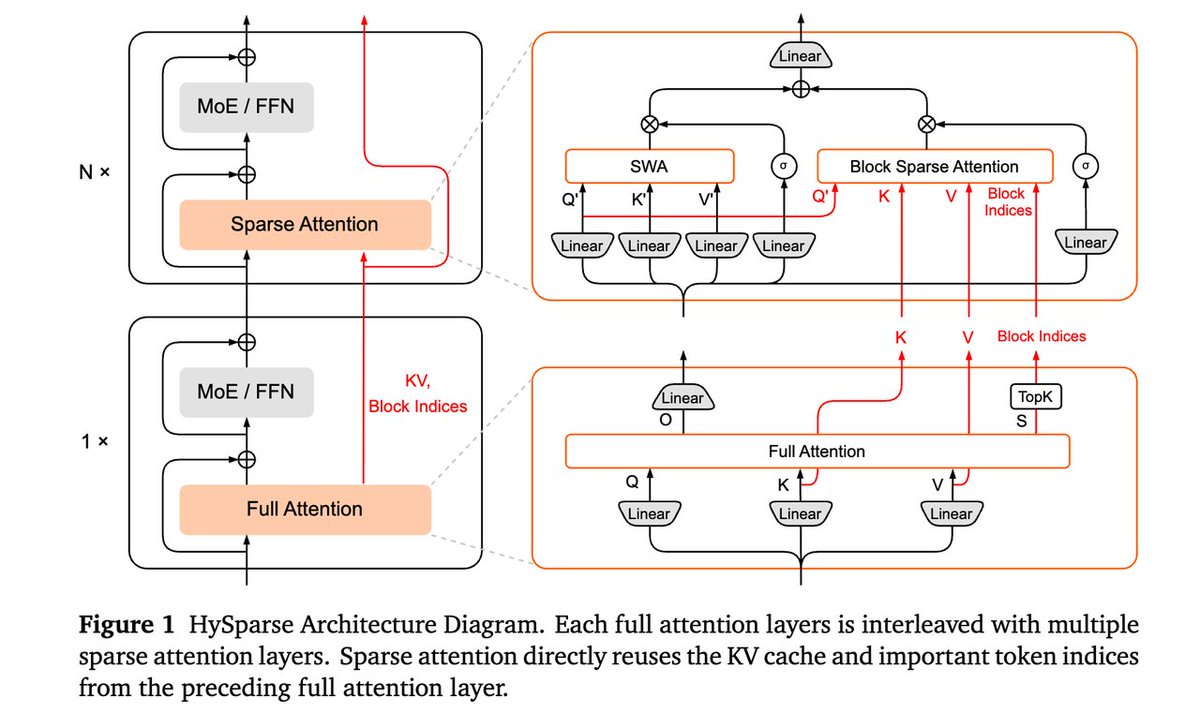
Kernel lessons transfer between different sparse attentions
From MiniMax's Open Weight Model Strategy and Inference Stack · ≈12:58
Each open model's sparse attention differs, but the optimization and kernel-writing process carries over, which is why day-zero support keeps getting faster across the open-model zoo.
What’s in it
- Each open model's sparse attention differs, but the optimization and kernel-writing process carries over, which is why day-zero support keeps getting faster across the open-model zoo.
Clip transcript
thinking about the inference engine, the kernels, like how does that work? >> Right. Um yeah, so there there's definitely things that you learn from optimizing one model that you take to another. Um so I think sparse attentions are something that have become quite popular now. So the MiniMax sparse attention is a little bit different from the uh from the deep seek and the and and and those and the and the ones that you find in JLM. Um but the they're still similar lessons that you can take from that optimization process and that kernel writing process that you can then bring to to the new sparse attentions. And you know, we've been in in some form or or another I've been thinking about this problem for for many years. So going all the way back to my PhD. So it's it's it's great to see some validation that that folks can now train it at scale and people are using it and and it's and it's it's going pretty
Recommended reads
Comments
Checking sign-in…
Loading comments…