DenseOn with the LateOn: Fully Open Dense and Late-Interaction Models for Multilingual, Long-Context, and Code Search
- Source
- arxiv.org
- Author
- Rapha\"el Sourty, Antoine Chaffin, Paulo Roberto Moura Junior, Am\'elie Chatelain
- Date
Context
Training search models on translated examples did not help every model generalize equally. The DenseOn and LateOn researchers compared multilingual models with the same underlying model, training data and objectives, but different ways of representing text. One compresses text into a single numerical representation; the other preserves finer-grained matching between text units. After training with translations into eight languages, the latter generalized better to languages and writing systems absent from those translations, while the single-representation model degraded outside them. The authors also released models, data and training code. Research abstract.
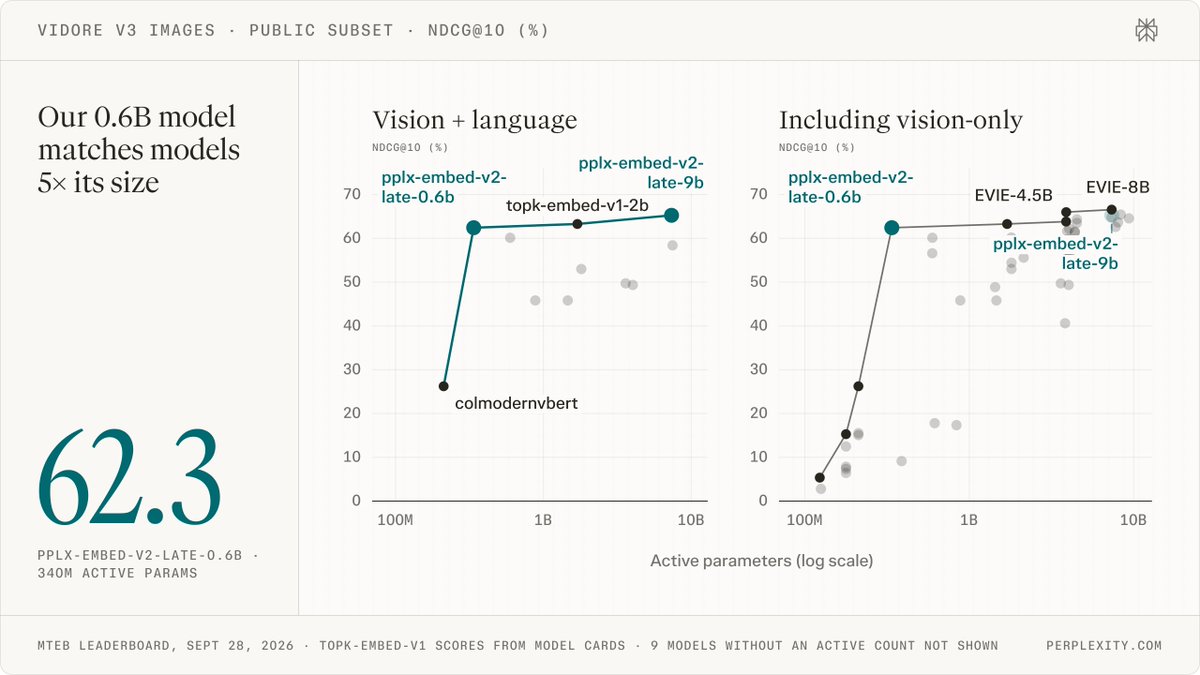
- Two 149M-parameter retrieval models trained on the same open data behave differently: the dense single-vector DenseOn scores 56.20 average nDCG@10 on the BEIR suite, the ColBERT-style late-interaction LateOn 57.22 — a new best for that size class.
- The multilingual models share a backbone, data, and objective, yet split on generalization: the dense model is strong on English and the eight translated languages but falls off outside them, while the late-interaction model holds up on languages and scripts it never saw.
- That split points at a mechanism: matching query and document -by-token, instead of squeezing each into one vector, is what lets translate-train stretch past the languages you actually translated into.
- The recipe is fully reconstructible: 665M English contrastive pairs curated down from 1.4B across 34 public sources, then 1.88M supervised pairs with mined hard negatives, with models, data, and training code released.
- determinism — Whether the same input reliably produces the same output — something LLM systems mostly lack, which changes how you test and debug them.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
“State-of-the-art retrieval models increasingly rely on closed training data, creating a reproducibility gap.”
“They achieve 56.20 and 57.22 average nDCG@10 on BEIR, respectively, setting new state-of-the-art results for this size class.”
“Despite sharing their backbone, data, and objectives, their representations behave differently: the dense model is strong on English and translated languages but degrades outside translate-train support, whereas the late-interaction model generalizes better to unseen languages and scripts.”
“This suggests that token-level matching turns translate-train from a target-language expansion strategy into a multilingual generalization recipe.”
Checking sign-in…
Loading comments…