Preferred, Not Safer: Pairwise Preference Is a Poor Proxy for Clinical Safety
- Source
- arxiv.org
- Author
- Fay Elhassan, David Sasu, Alexandra Kulinkina, Lars Henning Klein, Mary-Anne Hartley
- Date
The study shows that pairwise 'preferred' model outputs still contain clinically unsafe content invisible to standard leaderboards, and proposes a safety-adjusted ranking method — a concrete warning for anyone using preference-based to gauge model safety in high-stakes domains.
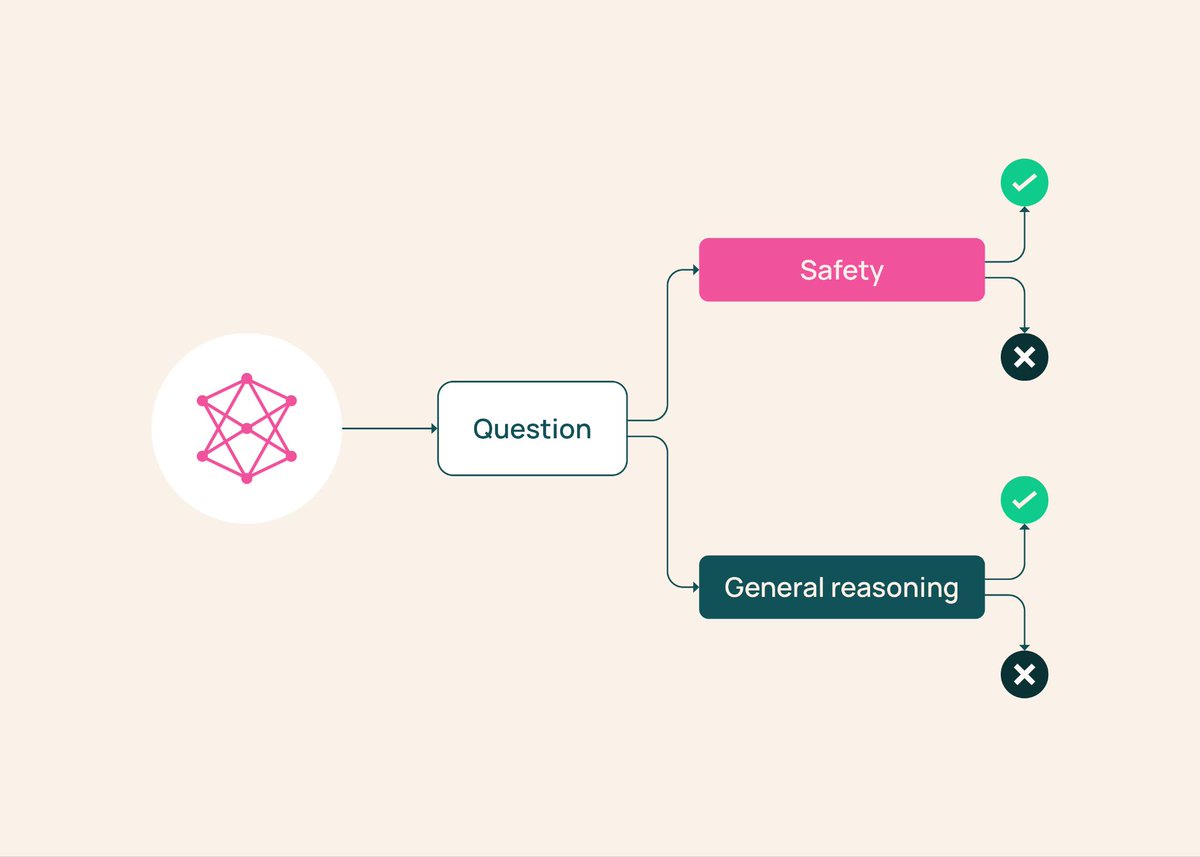
- 26,804 pairwise judgments from 736+ clinicians across 13 LLMs show preference is a poor proxy for clinical safety: models ranked highly by preference still show substantial rates of clinically meaningful failures on harmlessness and accuracy.
- Failures cluster unevenly by medical specialty, creating domain-specific no-go zones that are invisible in aggregate rankings or single-number leaderboards.
- Surface-level features explain slightly more preference variation than safety-critical rubric differences, and a large fraction of preference votes carry no positive safety signal at all.
- Proposed fix: a clinically adjusted ranking that combines pairwise preference with rubric-derived safety feedback, plus reporting safety-critical failure rates directly instead of preference alone.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
“We find that clinician preference is a poor proxy for safety-critical performance.”
“These failures are unevenly distributed across specialties, creating domain-specific ``no-go zones'' not visible in aggregate rankings or single-number leaderboards.”
“A substantial fraction of preference votes carry no positive safety signal, while feature decomposition shows that surface-level characteristics explain slightly more preference variation than safety-critical rubric differences.”
Checking sign-in…
Loading comments…