Gold-medal IMO performance masks a ceiling: no model solved a top-tier difficulty problem. That caps claims about frontier math reasoning.
Key takeaways · AI-distilled
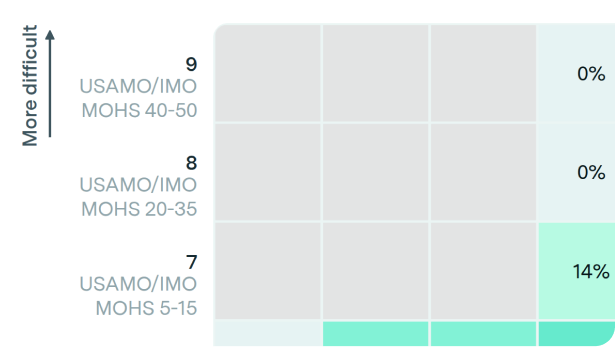
Epoch puts problems on one 10-point difficulty scale by combining Art of Problem Solving competition ratings with Evan Chen's Math Olympiad Hardness Scale, using only 2025 AIME, USAMO and IMO problems scored by MathArena to limit contamination.
Public models exceed 95% on problems rated up to 5. On problems rated 6-7, GPT-5 tops 67%, and Epoch says the remaining gap is reliability: it solved each problem at least once across four samples.
The 2025 IMO had three problems rated 7, two rated 8 and one rated 9; experimental systems such as Google's Deep Think solved all but the rating-9 problem.
Because that top-tier sample is small, Epoch tested the public Deep Think model on two 2024 IMO problems rated 8 and 9: it failed both in all 10 samples each. Epoch still calls full saturation unlikely rather than ruled out.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.