Muteval checks whether an AI application's tests notice deliberate damage. It first verifies that the original system passes, then changes a prompt, retrieved context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, tool output or model and reruns the existing evaluations. A change that affects the output but leaves every test passing identifies a possible gap in what the tests cover.
Its mutation score is the share of evaluated changes the tests catch. That gives developers a way to investigate weak checks, such as a test that overlooks a removed instruction. Surviving changes still need inspection: the score describes these injected changes, not the probability of catching every future failure.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
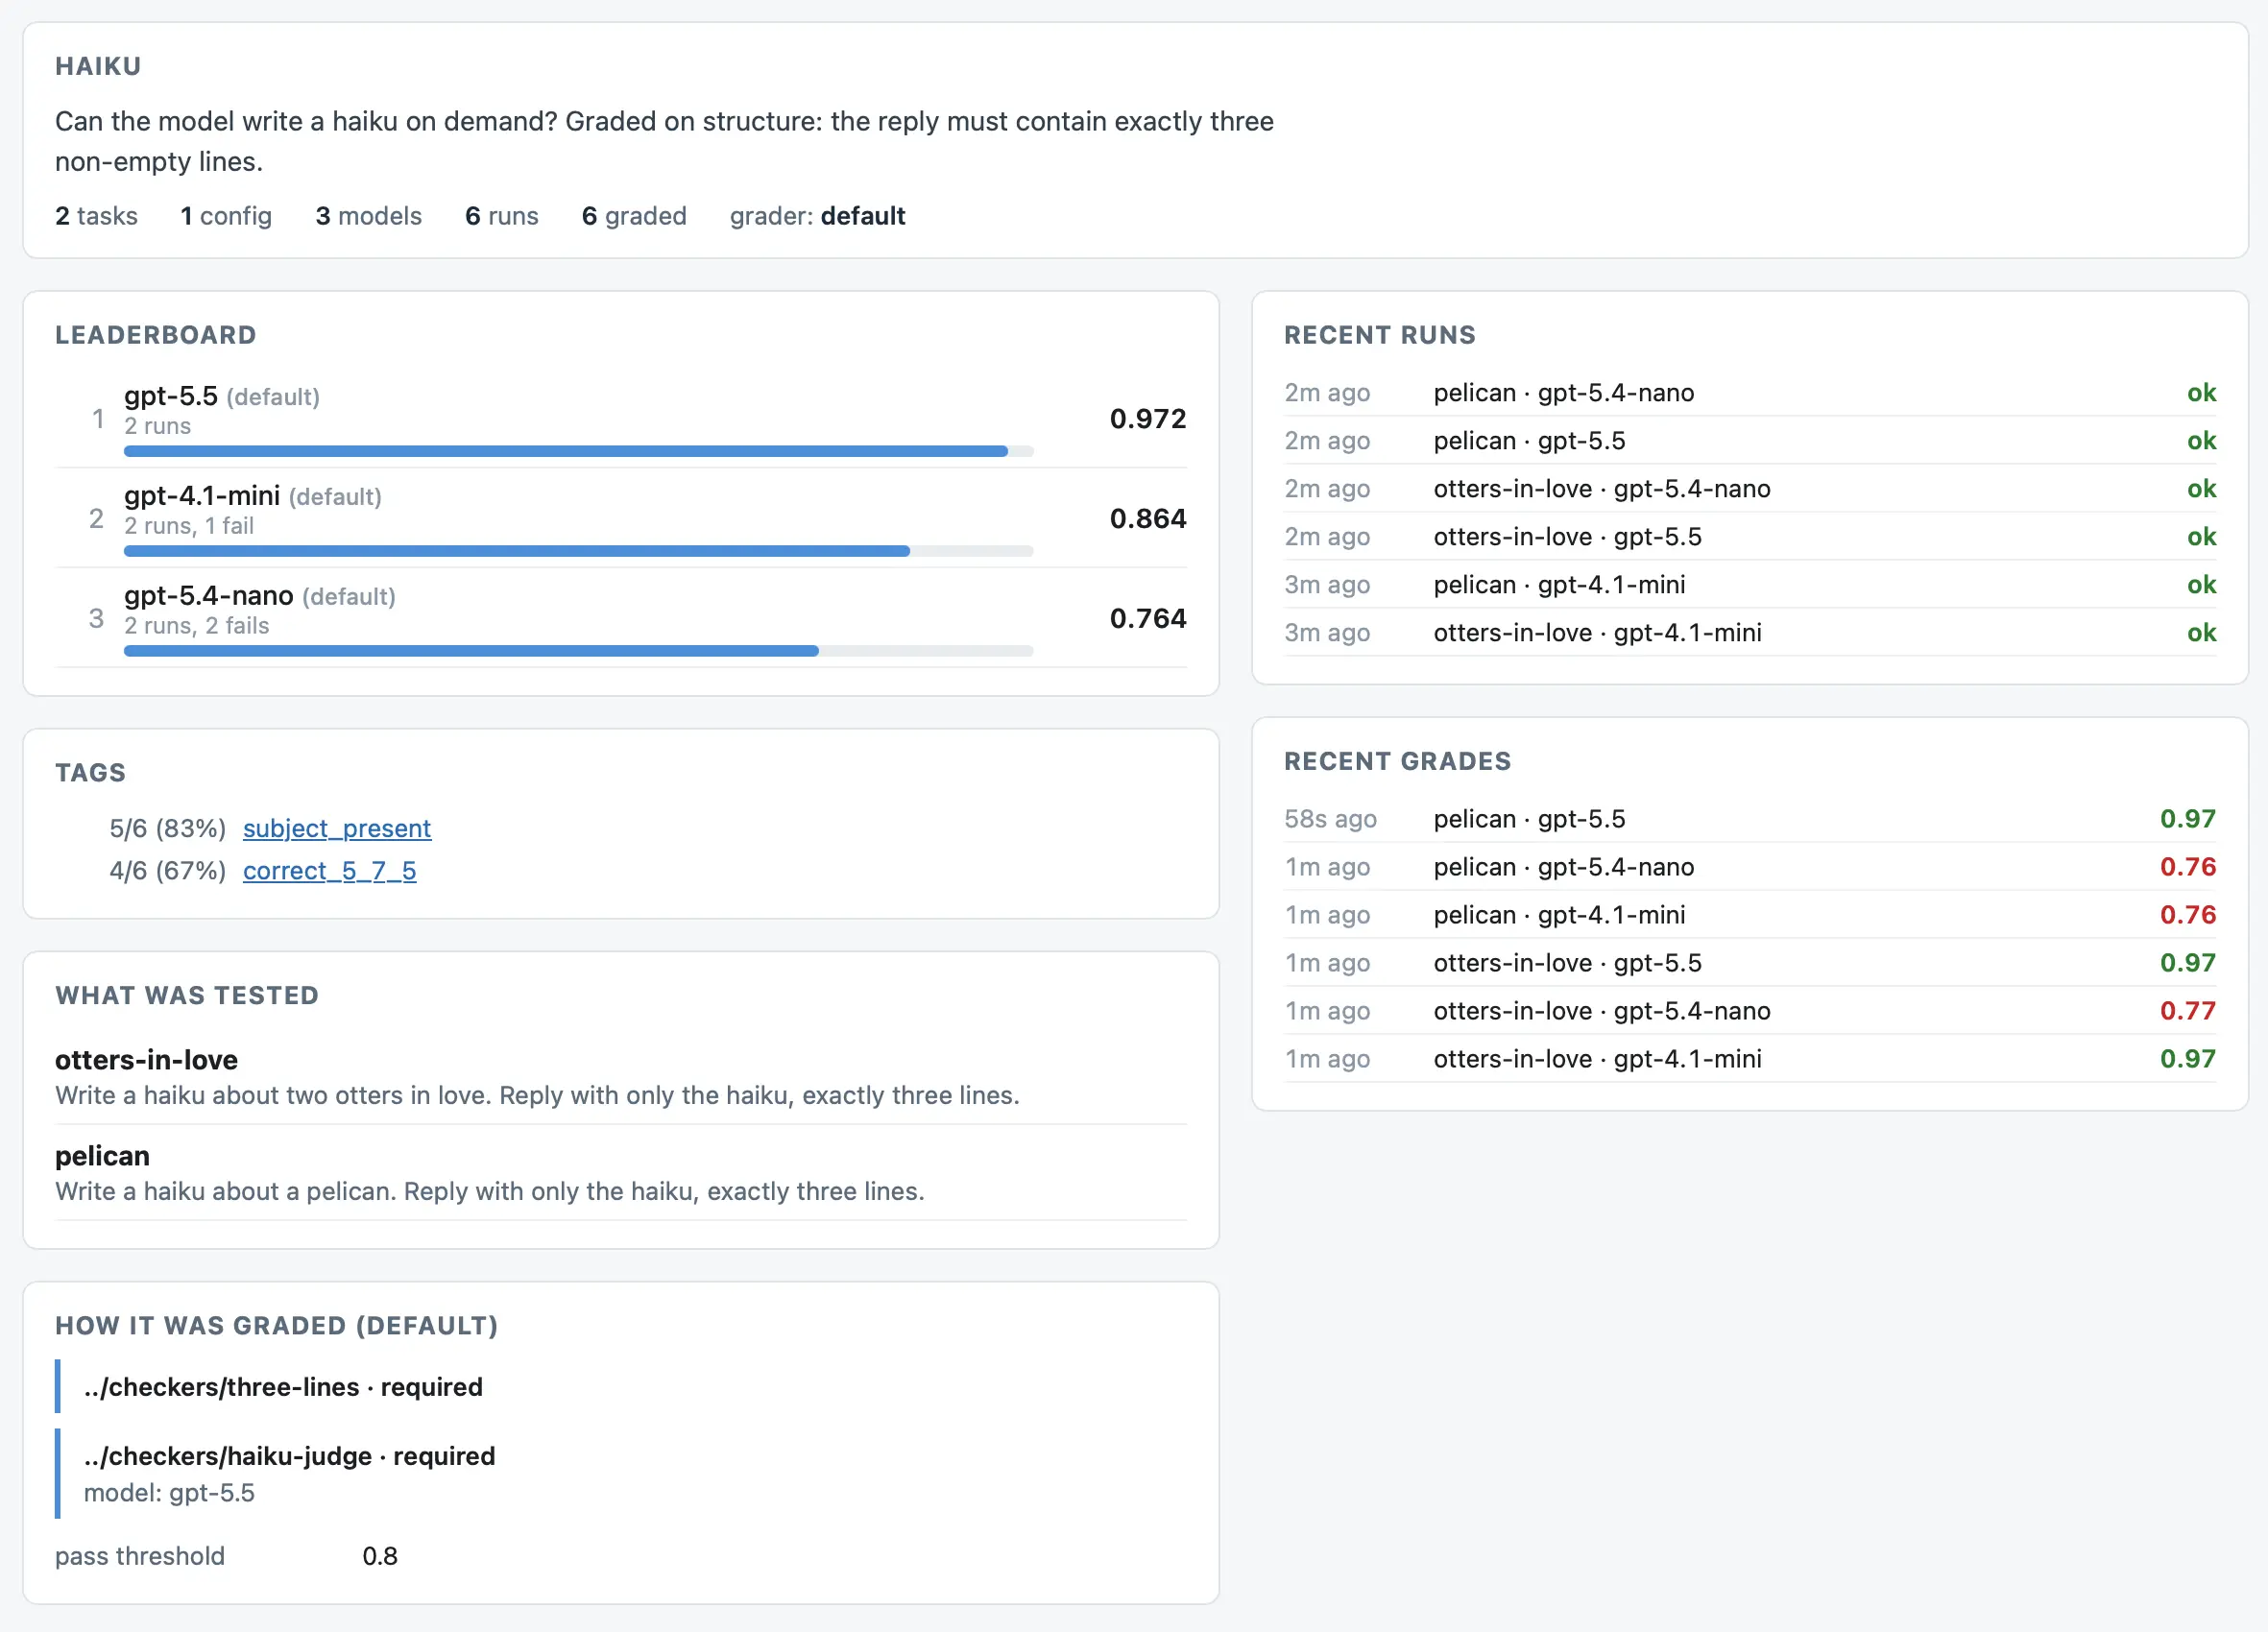 articlesmevals - a small eval suite for evaluating models, prompts, and harnessesSimon Willison
 articleBreaking Models to Test the Judge: A Mutation Testing Approach for Semantic Evaluators of Domain Class DiagramsKevin Delcourt, Meriem Ben Chaaben, Abdelhamid Rouatbi, Luciano Marchezan, Houari Sahraoui
 articleWhen Knowledge Changes: Metamorphic Testing of RAG Systems with MutationsJinhan Kim, Samuele Pasini, Paolo Tonella