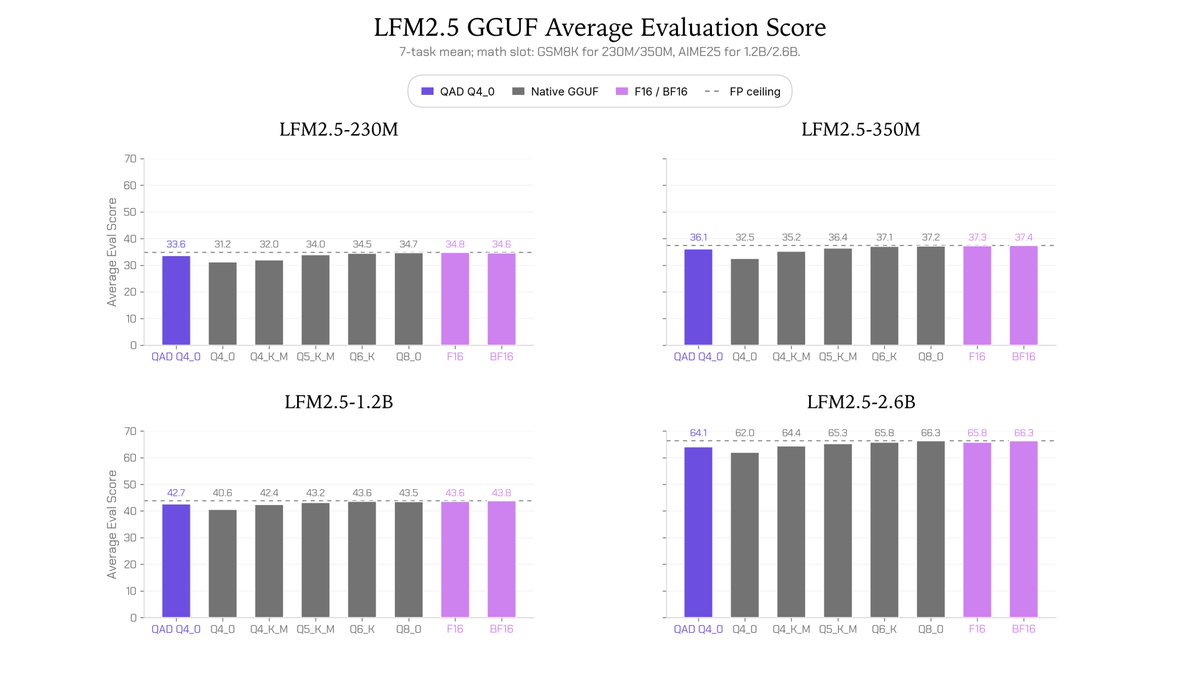
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
Why it matters
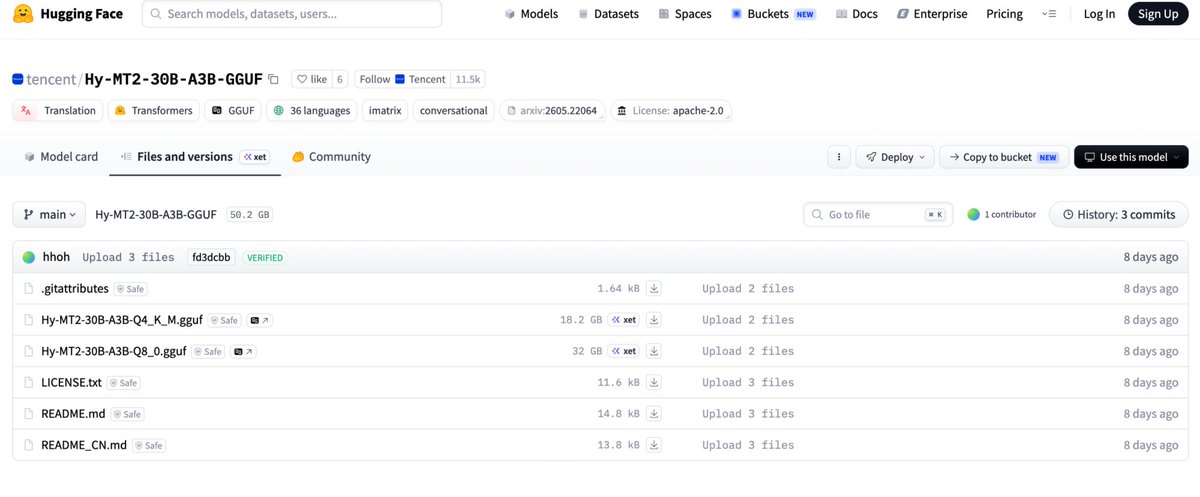
Lets engineers load community GGUF checkpoints straight into the standard transformers API instead of switching toolchains, with benchmarks against llama.cpp and clear size/precision tradeoffs across quantizationShrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.Full definition → levels.