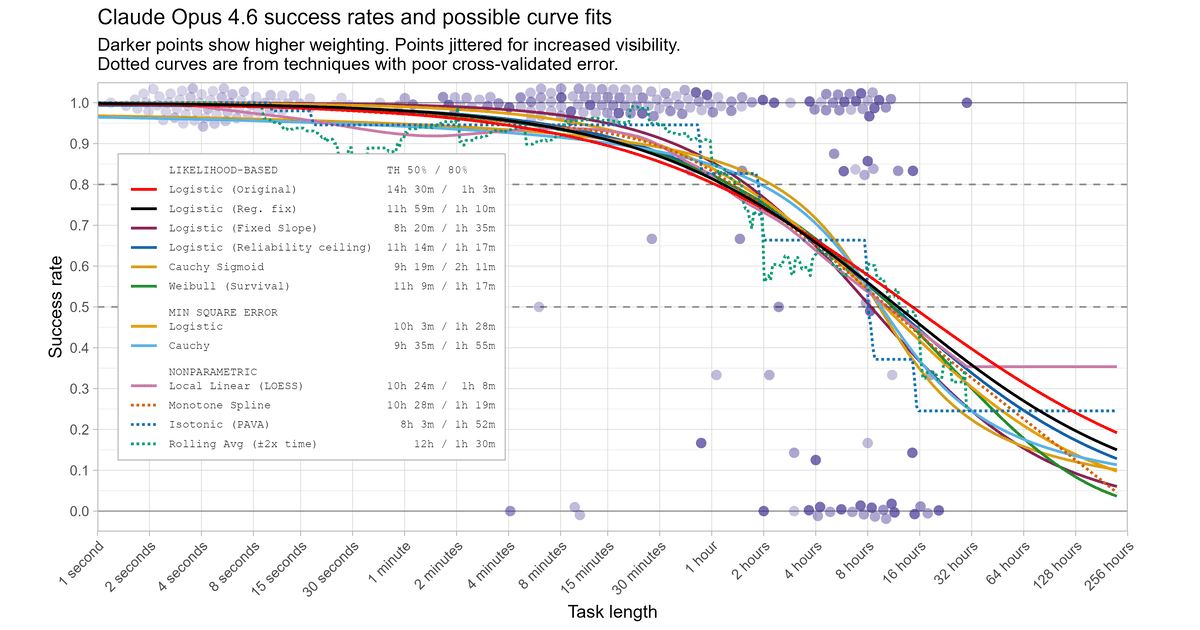
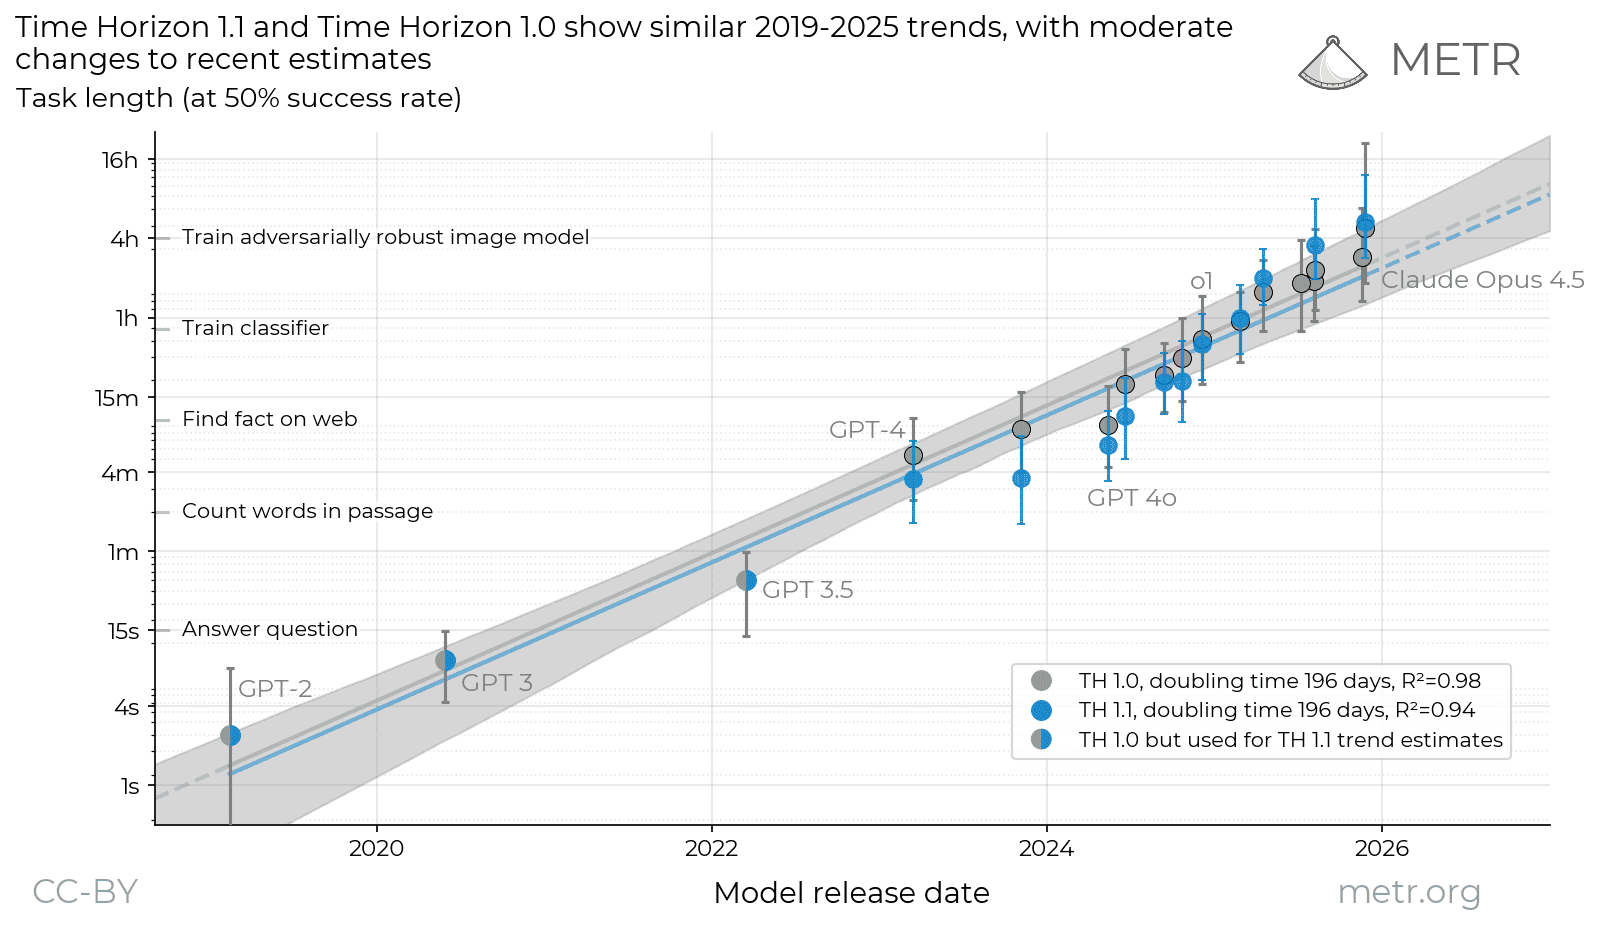
Corrects common misreadings of time horizon: it measures replaceable human labor at 50% success, with error bars around 2x, so don't treat model comparisons as precise.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.