Together Link: open models in the harness you already use. Start with one command today.
- Source
- together.ai
- Date
Context
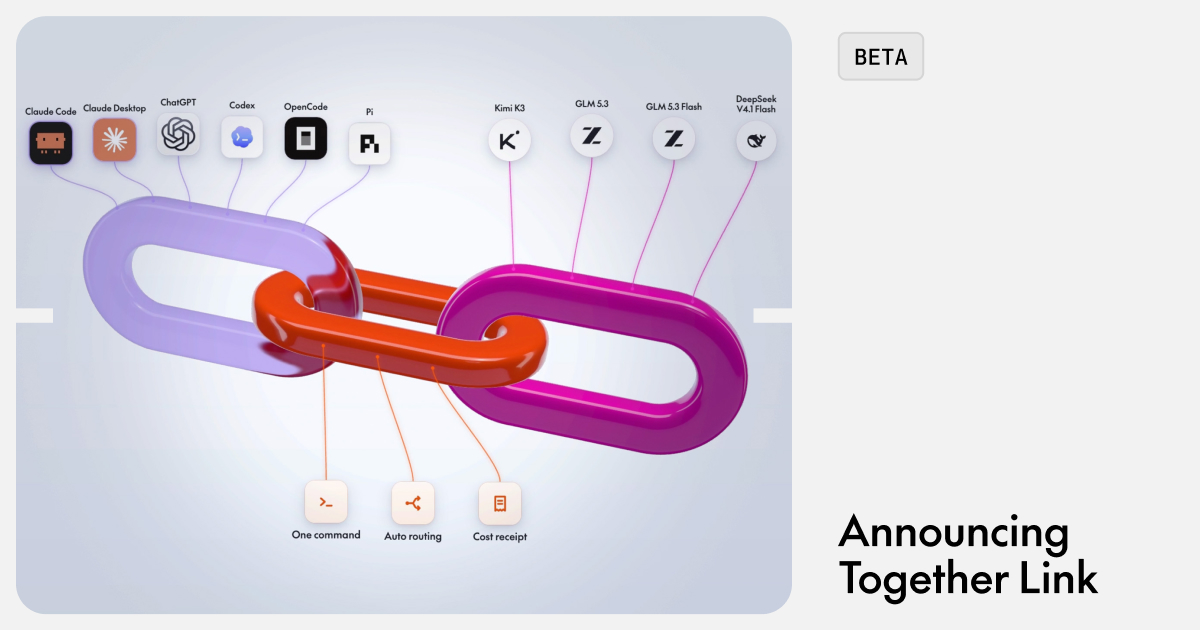
Together Link is a tool from Together AI that connects existing coding agents, including Claude Code, Codex and OpenCode, to open models hosted on Together instead of one premium closed model. Together's announcement says one install command sets it up and one command returns the to its native models.
The cost idea is routing. In Auto mode a router reads a session's first task and sends it to a cheaper or stronger model. With an Anthropic key it chooses between Opus 5.5 and GLM 5.3; without one, between GLM 5.3 and GLM 5.3 Flash. Routing happens once per session, which Together says keeps working, and a tracker shows each session's spend beside what Opus 5.5 would have cost.
The claim that spend falls by over 50% is Together's, and the post gives no method or measured cases. Its OpenRouter -share figures (as of 9/30/2026) describe usage, not quality, so they do not show that cheaper models match the premium one on a given team's tasks.
- Together's Auto router reads only the first task of each session and picks one model for the whole session, so prompt caching keeps working: quick fixes go to fast, low-cost models and hard problems to frontier-capable ones.
- With an Anthropic key the router chooses between Opus 5.5 and GLM 5.3; without one it chooses between GLM 5.3 and GLM 5.3 Flash, according to Together.
- After each session a tracker shows what you spent next to what the same session would have cost on Opus 5.5, and billing runs on an existing Together API key with no separate contract.
- Together says it serves the largest share of OpenRouter tokens for DeepSeek V4.1 Flash (40.8%), GLM 5.3 Flash (28.2%) and Kimi K3 (23.1%), as of September 30, 2026.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…