Why Fei-Fei Li Is Betting on Spatial Intelligence
- Source
- youtube.com
- Author
- a16z
- Date
Context
Atlas is a model from World Labs that takes views of a scene, each tagged with a 3D camera position, and predicts how the scene looks from a new camera position. In an a16z conversation, the team compares it with language models, which predict the next word, and video models, which predict the next frame. Because every input image carries a camera pose, they say one model can both reconstruct a real space from a few views and imagine new camera paths, tasks that were handled by separate specialized systems in computer vision.
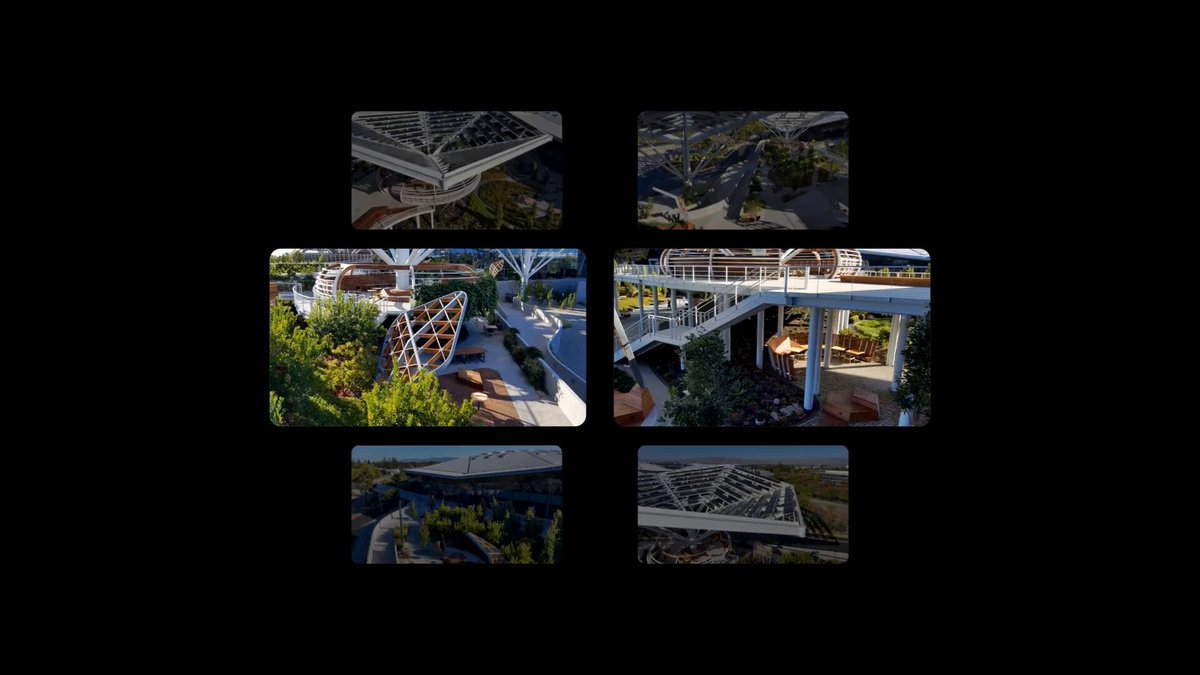
Their demonstration is a slow-motion orbit shot of the kind once filmed with hundreds of cameras, produced from as few as three phone videos. World Labs' own post says Atlas is entering early access with select partners, and that when parts of a scene are not visible in the input views, Atlas imagines a plausible way to fill the gaps; passing more images means less imagination.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.



Checking sign-in…
Loading comments…