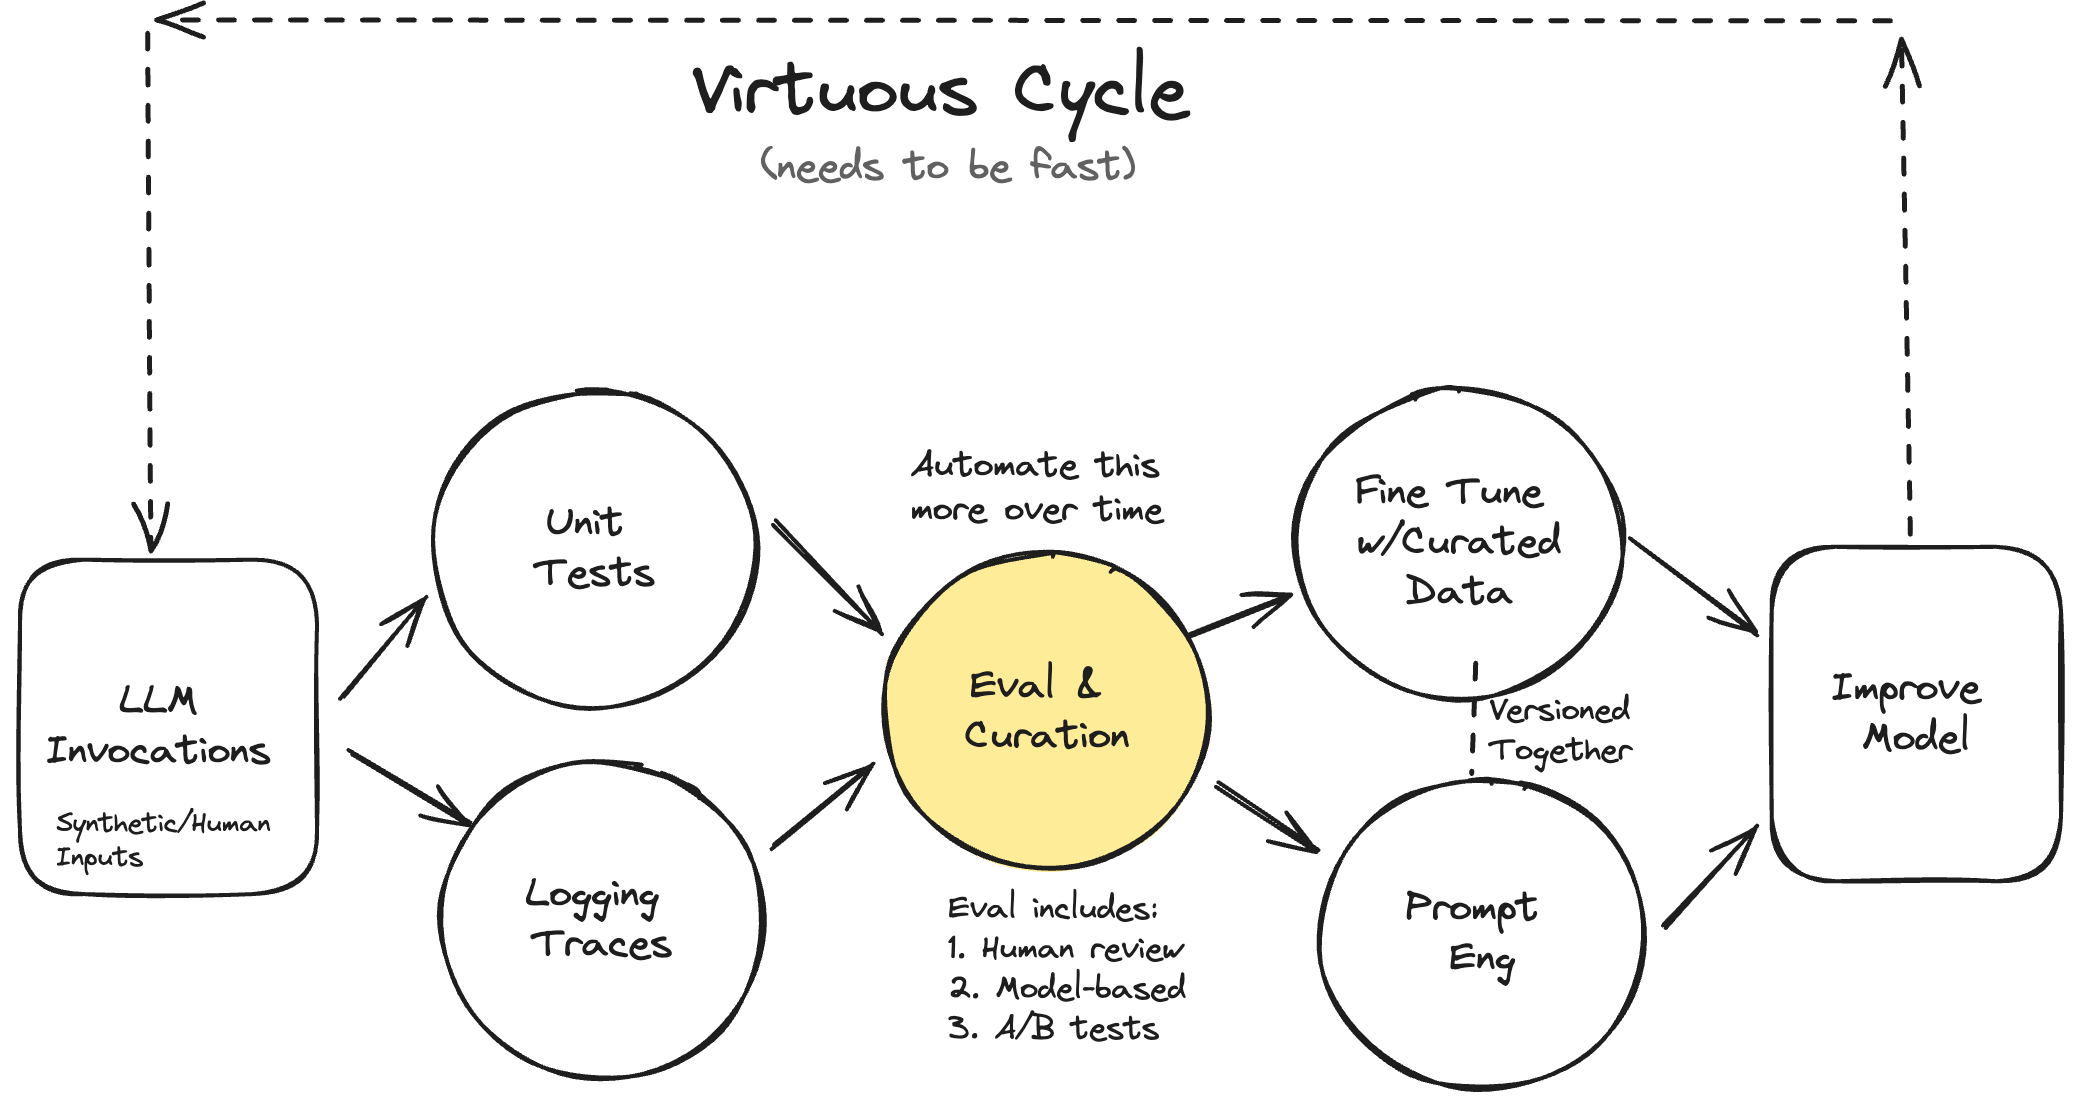
Offline metric gains routinely fail to transfer once real inputs are ambiguous and labels inconsistent. This shows how to build an evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → set that reflects production, and how to trade precision for recall when the task is security-critical.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.